

Most of the DeepSeek vs ChatGPT articles still ranking on Google compare models that neither app runs anymore. DeepSeek moved its website and app to V4.1 Flash 1017 on October 17, 2026. ChatGPT switched Plus and higher plans to GPT-6 Sol on October 7, with Free and Go on GPT-6 Luna a day later. So we sent five identical prompts to both current models through one API key, scored the answers, and timed the responses. Below: the scoreboard, the privacy facts from both companies' own pages, and where Claude fits.
Key Takeaways
- DeepSeek's app now runs V4.1 Flash 1017, while ChatGPT Plus runs GPT-6 Sol, so most older comparisons are out of date.
- On five identical prompts, both models produced correct answers every time, with no quality gap in coding, math, or document work.
- GPT-6 Sol answeredinfewer tokens on every task;DeepSeekspent up to 4.2 times more output tokens on reasoning.
- DeepSeek's privacy policy states that app data is stored in China;themodel weights themselves are MIT licensed and can be self-hosted.
- You can run both models side by side through DeepSeek on Atlas Cloud and the OpenAI family with one key.
DeepSeek vs ChatGPT at a Glance (October 2026)
Before any scoring, it helps to know what each name actually points to today. "DeepSeek" is a model company whose chat app runs one default model. "ChatGPT" is a product that routes you to different OpenAI models depending on your plan.
| DeepSeek | ChatGPT | |
|---|---|---|
| Developer | DeepSeek (Hangzhou, China) | OpenAI (San Francisco, US) |
| Model behind the app today | V4.1 Flash 1017, live on website, app and API since October 17, 2026 | GPT-6 Sol for Plus, Pro, Business and Enterprise; GPT-6 Luna for Free and Go |
| Free plan | The whole app. DeepSeek's launch post describes it as free with no ads and no in-app purchases | Free tier with usage limits on uploads, images and voice |
| Paid plans | None for the consumer app | Go, Plus, Pro (three tiers), Business, Enterprise |
| Open weights | Yes, V4.1 Flash 1017 is published under an MIT license | No |
| Accepts images as input | Yes, V4.1 Flash has native vision | Yes |
| Generates images and voice | No, the model outputs text only | Yes, through ChatGPT Images 2.5 and GPT-Live voice |
The table says nothing about answer quality on purpose. That is what the tests below are for.
From DeepSeek 3.1 vs ChatGPT 5 to Today's Versions
Searches for "deepseek 3.1 vs chatgpt 5" still show up, and the pairing made sense in August 2025: DeepSeek V3.1 arrived on August 21, two weeks after GPT-5 on August 7. Both companies have shipped four or five major updates since then. The timeline below shows why a comparison from early 2026 can be two generations stale on each side.
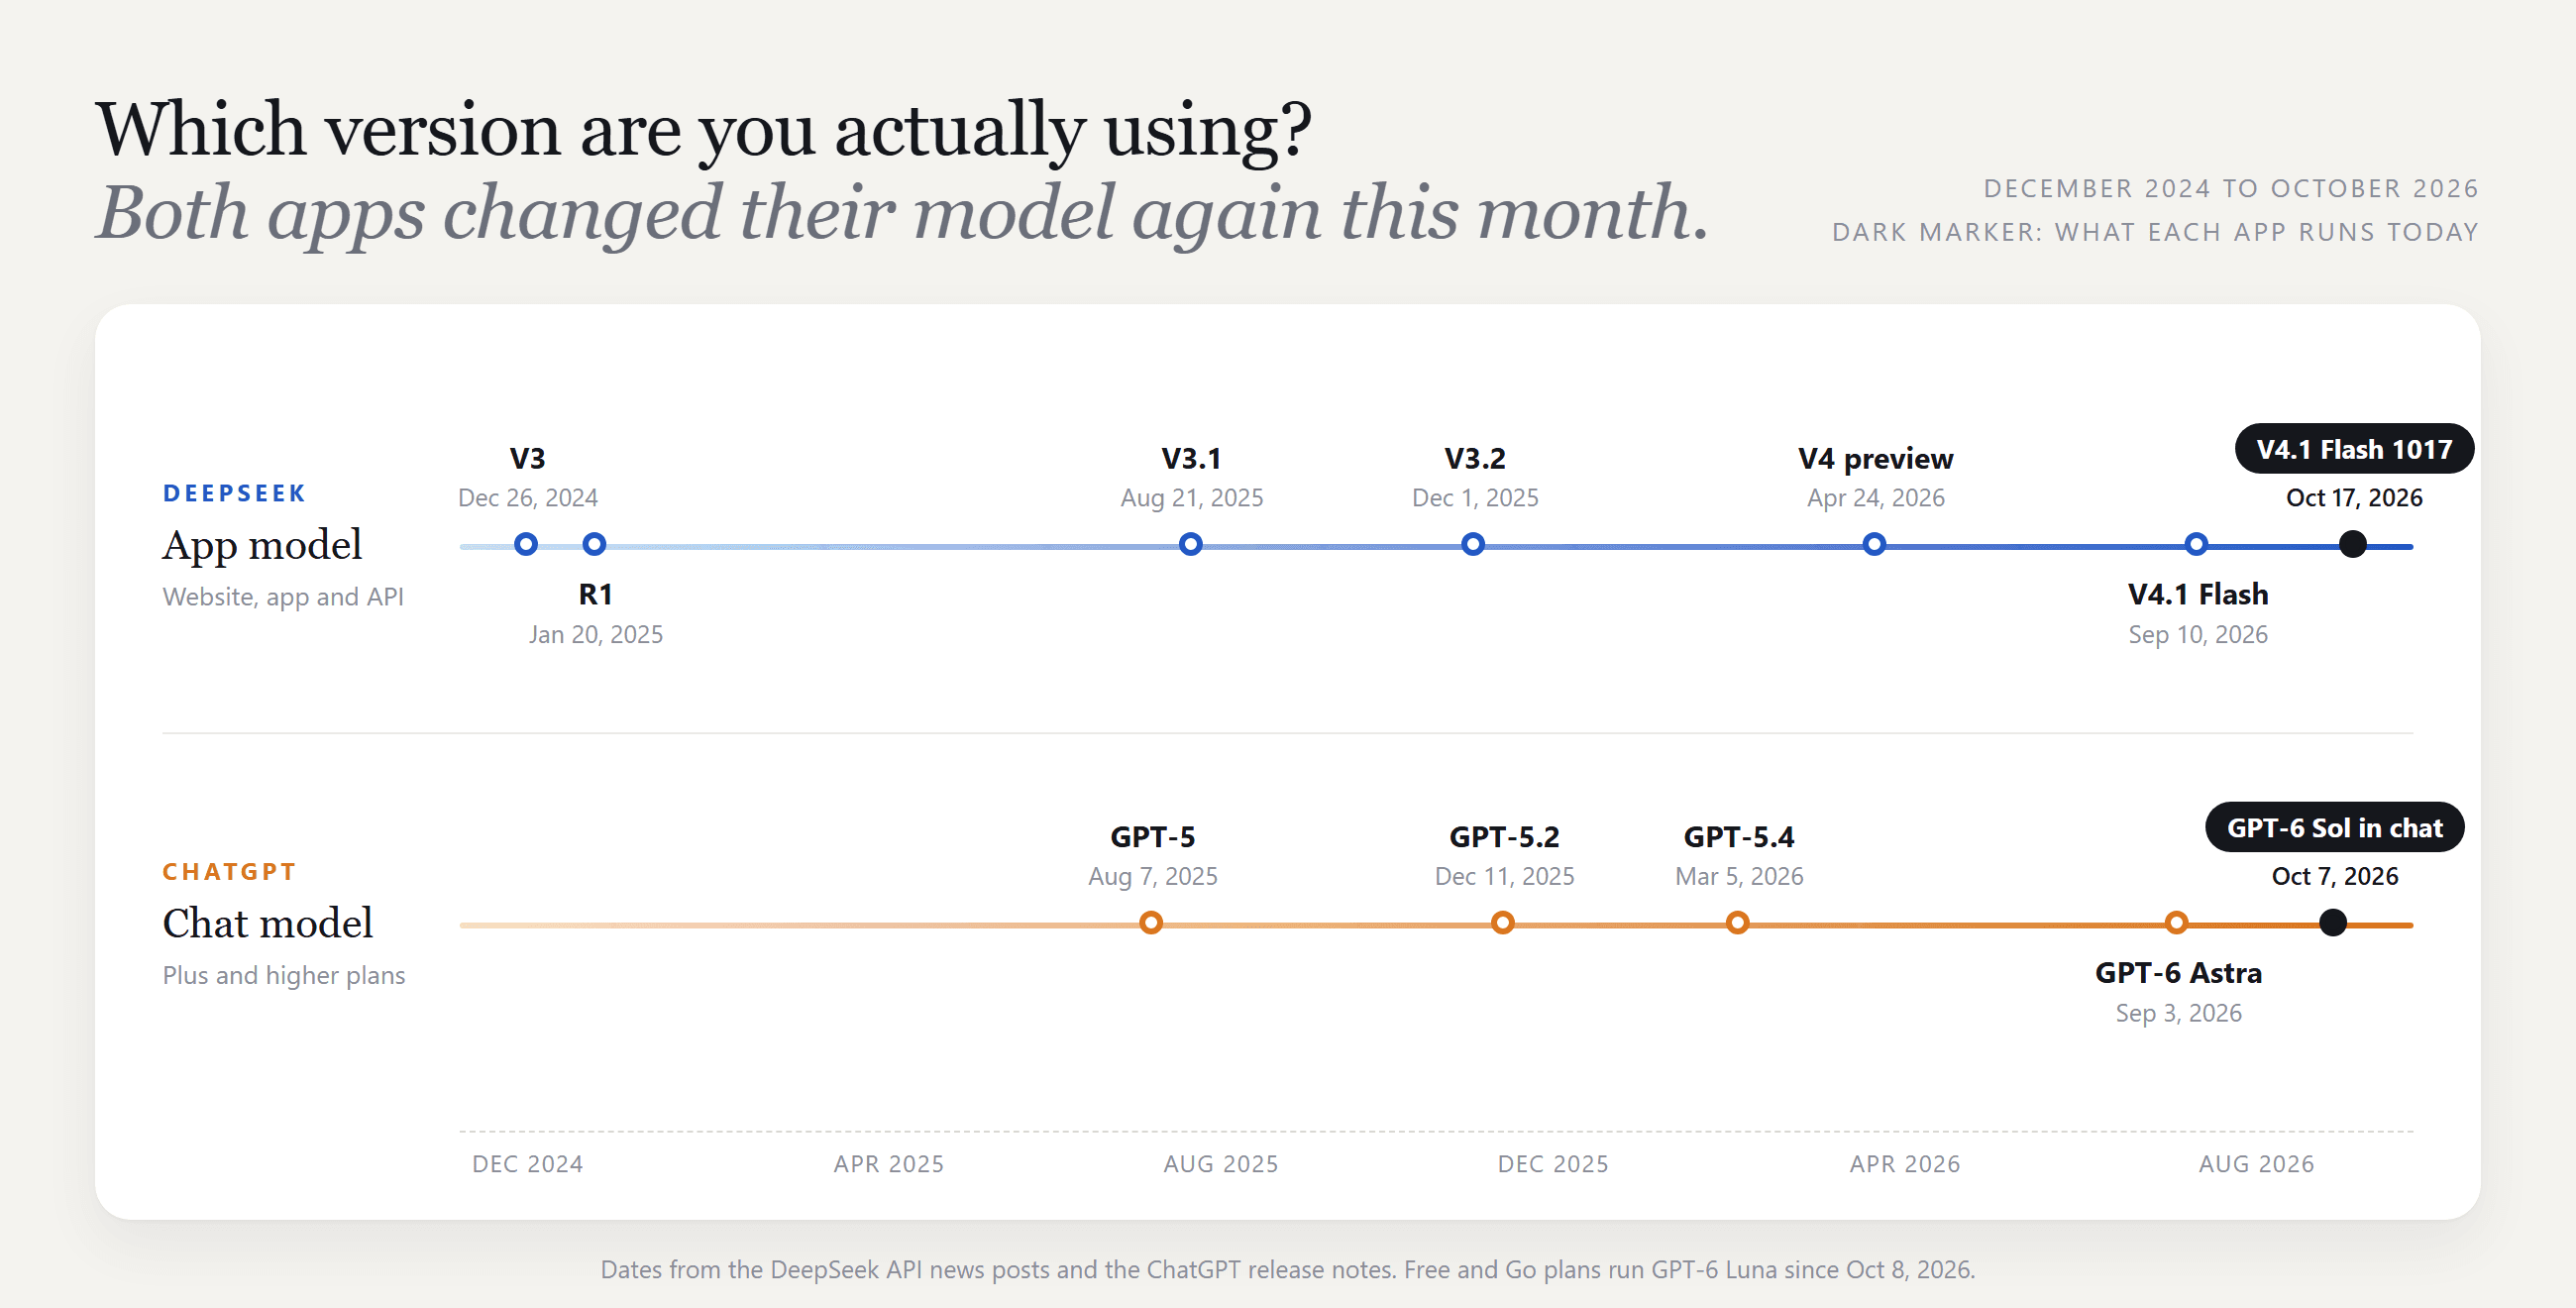
Two details matter for reading any benchmark. DeepSeek's 1017 release is a point update of V4.1 Flash, and DeepSeek describes it as giving shorter outputs than the September version. On the other side, GPT-6.1 Sol exists in ChatGPT Work and Codex, but the chat tab itself runs GPT-6 Sol, according to the ChatGPT release notes from October 7, 2026. We tested the chat-tab model, since that is what a Plus subscriber gets.
How We Compared ChatGPT vs DeepSeek With One API Key
Testing two chat apps side by side means two accounts, two sets of usage limits, and no way to tell whether an app quietly routed you to a smaller model. We avoided that by calling both models through Atlas Cloud, which serves the DeepSeek family and the OpenAI family behind the same chat completions endpoint. Same prompt, same parameters, same day, and the model ID in the request tells you exactly which version answered.
Method 1: Run Both in the Atlas Cloud Playground
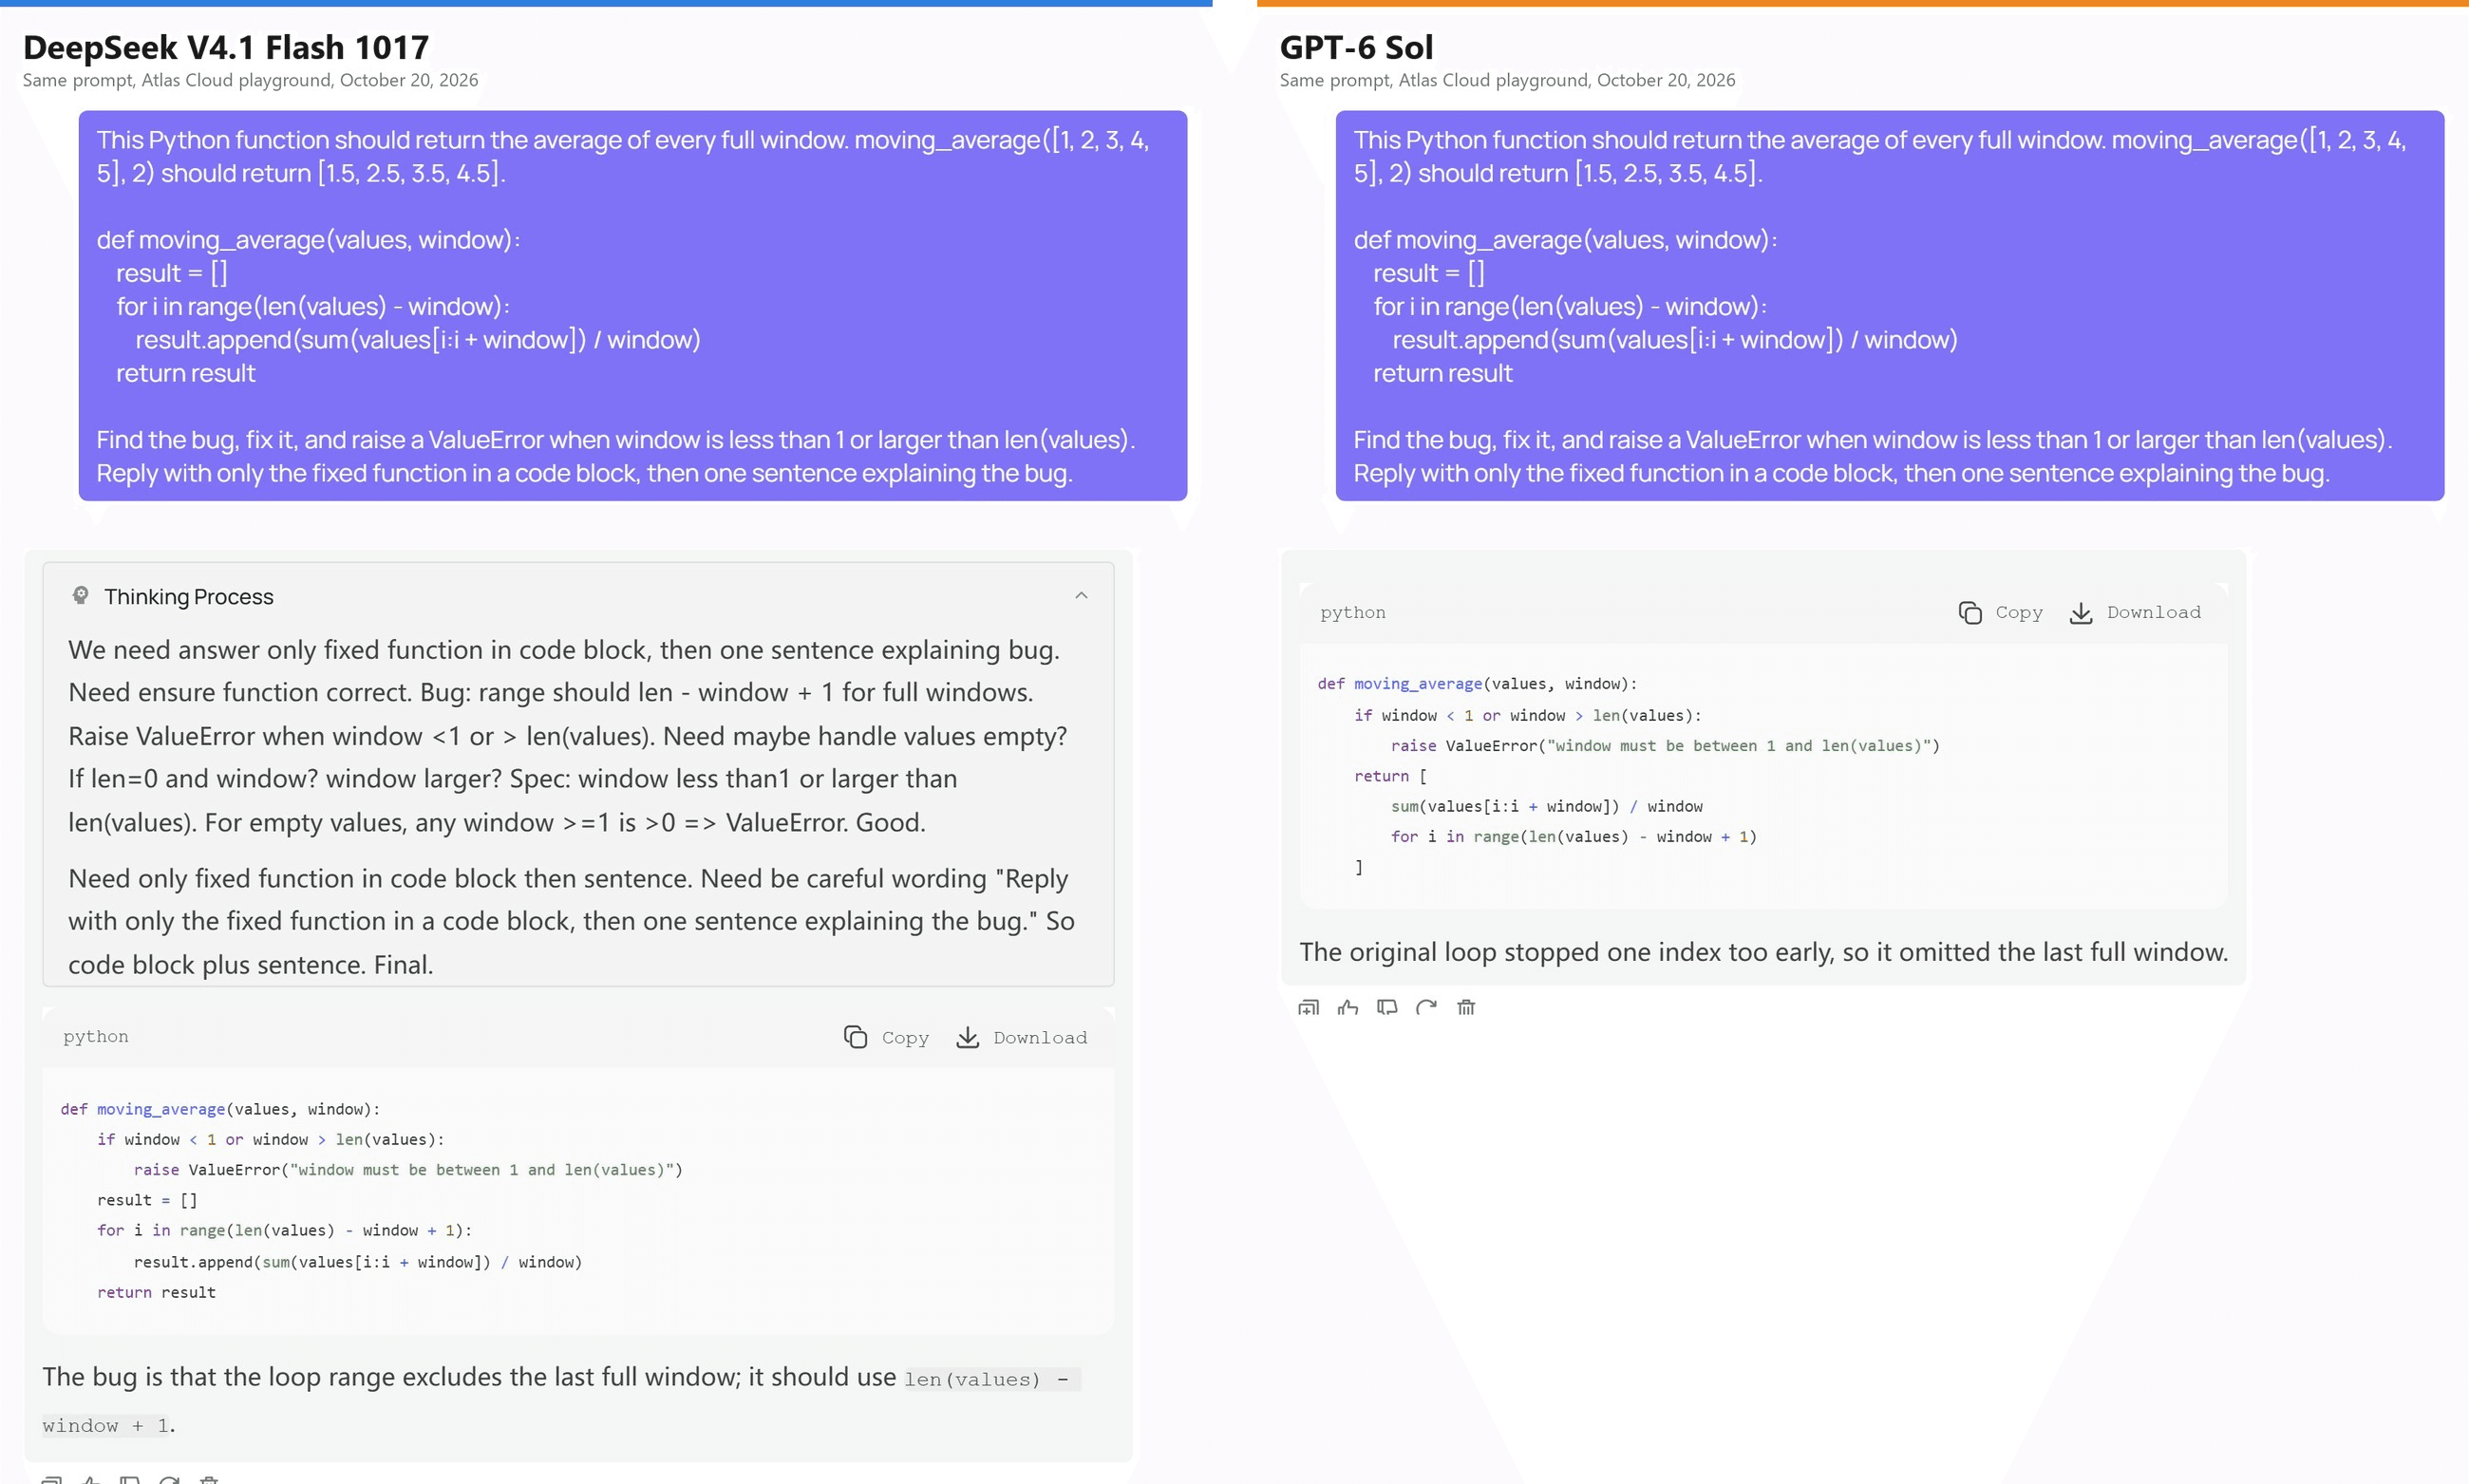
No code needed for a quick check. Sign in, open the DeepSeek V4.1 Flash 1017 playground in one tab and the GPT-6 Sol playground in another, then:
- Paste the same prompt into the message box on each page.
- Click the send arrow. DeepSeek shows a collapsible Thinking Process panel above its answer; GPT-6 Sol returns the answer directly.
Every run lands in Request History, so you can reopen both answers later without rerunning them.
Method 2: Send the Same Prompt Through the API
For a repeatable test, or to wire either model into your own app, use the API. Three steps.
Step 1: Create an API key. Open Settings in the console, go to API Keys, and click Create API Key. Keep it server-side; one key covers every model on the platform.
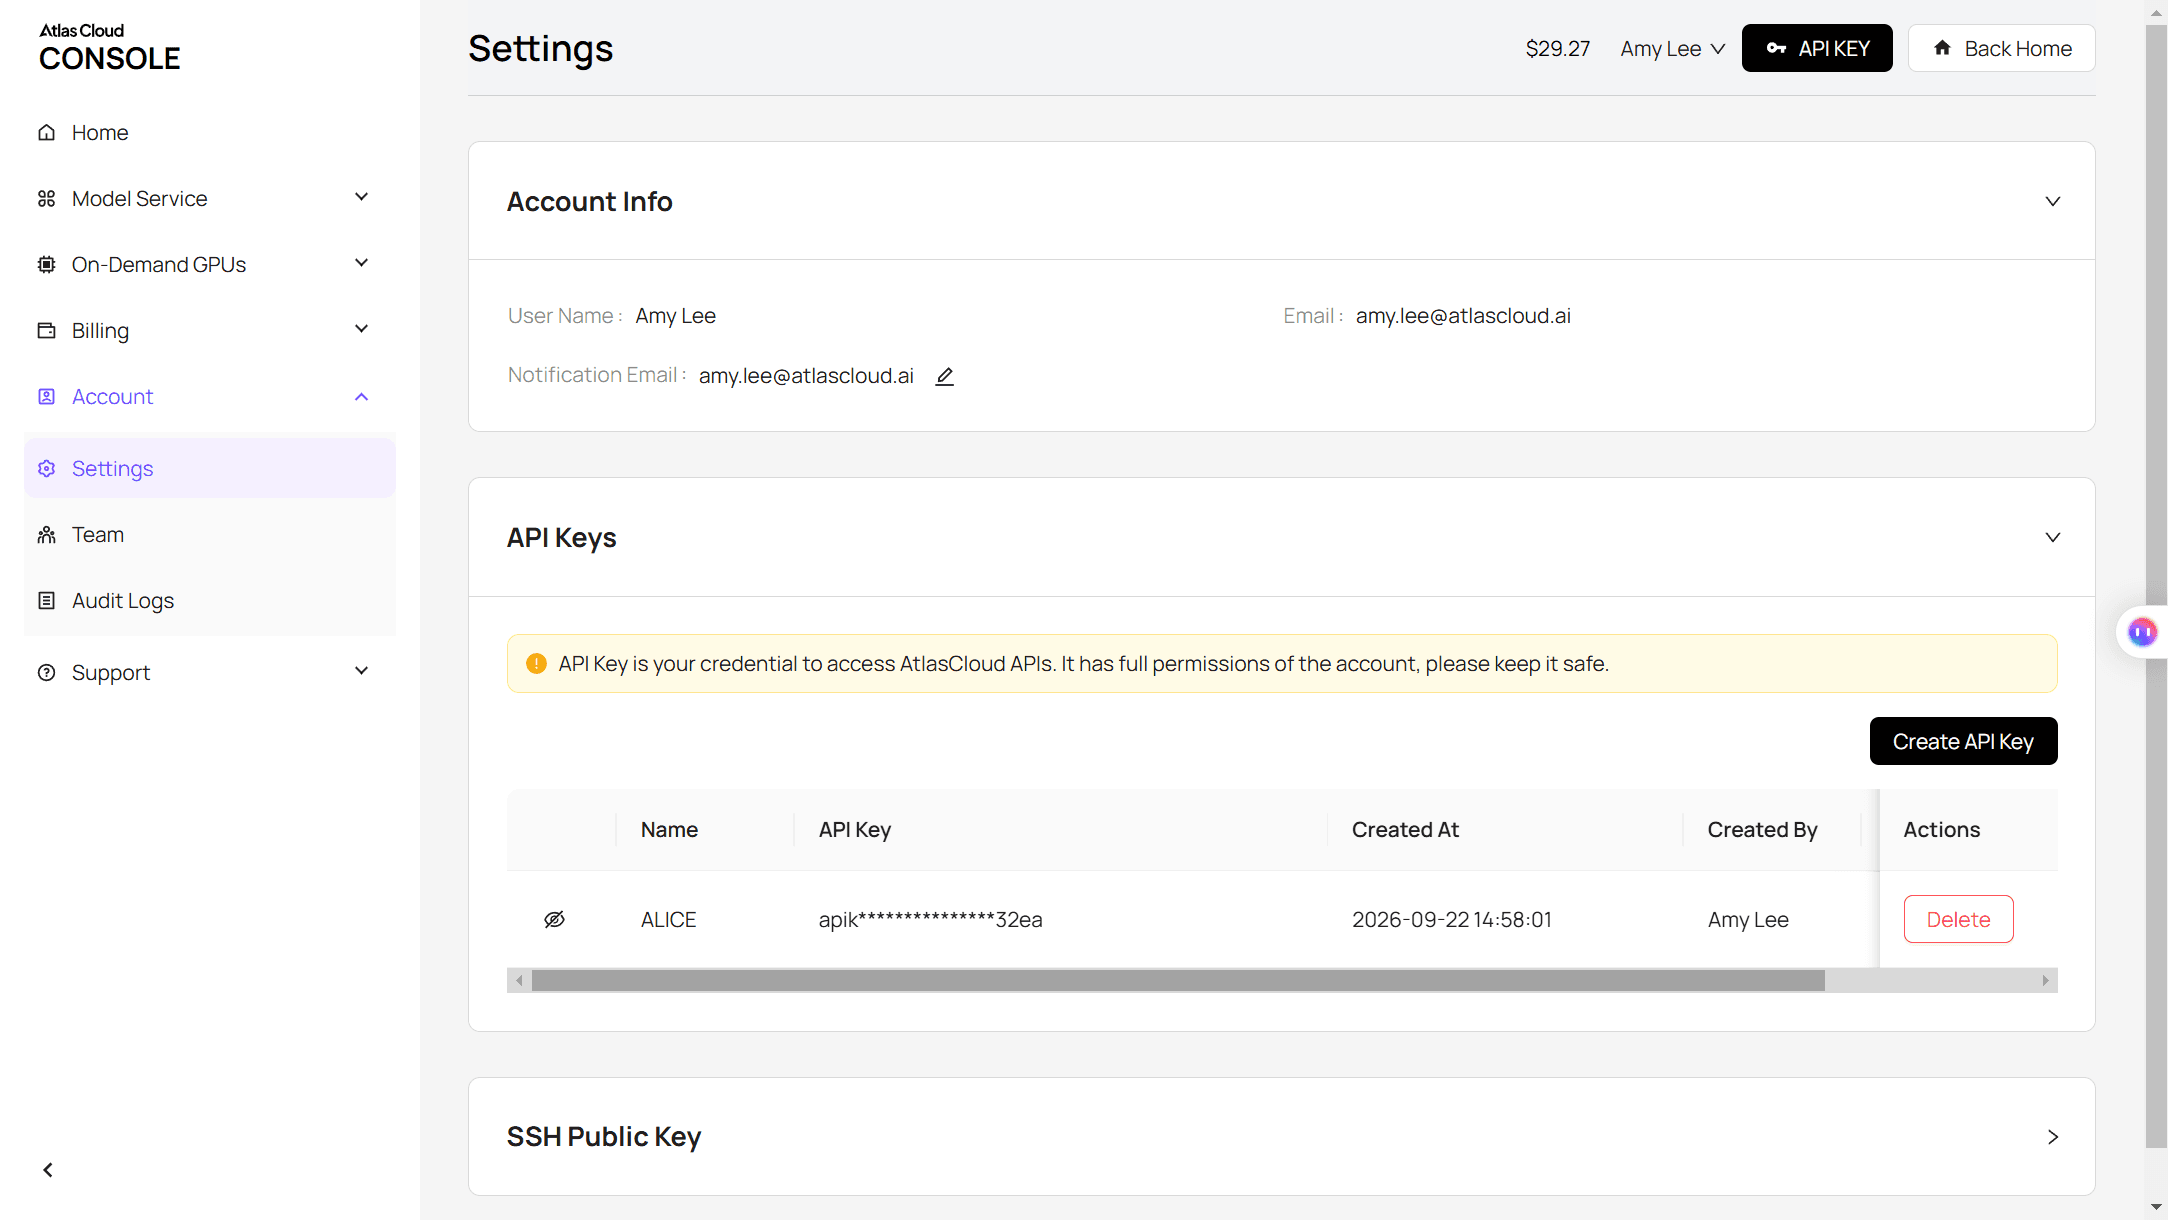
Step 2: Check the request shape. The API docs cover the chat completions format, and each model page has an API tab with a ready-made example.
Step 3: Send the request. Both models speak the OpenAI chat completions protocol, so the only thing that changes between the two calls is the model string.
plaintext1curl -X POST "https://api.atlascloud.ai/v1/chat/completions" \ 2 -H "Authorization: Bearer $ATLASCLOUD_API_KEY" \ 3 -H "Content-Type: application/json" \ 4 -d '{ 5 "model": "deepseek-ai/deepseek-v4.1-flash-1017", 6 "messages": [{"role": "user", "content": "Find the bug in this function: ..."}], 7 "max_tokens": 4000 8 }'
Swap the model value for openai/gpt-6-sol and send it again. The reply text sits at choices[0].message.content in both cases, and the usage block tells you how many tokens each model spent, which turned out to be the most interesting number in our tests.
DeepSeek vs ChatGPT Comparison: Results From 5 Identical Prompts
We picked five everyday tasks, wrote one prompt each, and sent them with default sampling and a 4,000-token cap. Scoring was pass or fail on the stated requirements, with a tie-break on how closely the answer followed instructions. The full prompts are in the box after the table.
| # | Task | DeepSeek V4.1 Flash 1017 | GPT-6 Sol | Result |
|---|---|---|---|---|
| 1 | Fix a buggy Python moving_average function and add a ValueError guard | Correct fix, correct guard, one-sentence explanation. 216 output tokens | Same fix, same guard. 131 output tokens | Tie |
| 2 | Two-train catch-up problem, explained for a 9th grader | Correct, 11:45 a.m., five steps with equations. 512 output tokens | Correct, 11:45 a.m., five shorter steps. 233 output tokens | Tie |
| 3 | Product launch email: subject under 50 characters, body 110 to 130 words, no exclamation marks | All three rules met: 34-character subject, 115-word body. 2,536 output tokens | All three rules met: 36-character subject, 119-word body. 750 output tokens | Tie |
| 4 | Turn meeting notes into JSON action items with real dates | Four items, all four dates resolved correctly, valid JSON. 782 output tokens | Four items, identical dates, valid JSON. 377 output tokens | Tie |
| 5 | Read a bar chart image and report growth and the closest gap | Correct: City Mug up 220 units, Q4 gap of 10. 465 output tokens | Same two answers. 112 output tokens | Tie |
Five ties is a real result, and a different one from what the 2025 comparisons reported. On tasks an office or student user sends every day, both current models get it right.
The gap is in token usage. The output counts above include reasoning, and DeepSeek V4.1 Flash reasons visibly before answering by default, so it used 1.6 to 4.2 times as many output tokens as GPT-6 Sol on the same prompt. The chart question had the widest ratio, 465 tokens against 112, and the email the biggest absolute spend: 2,536 tokens for a 115-word email. That shows up on API bills and in a long thinking panel in the app.
Speed was closer. On a short streamed prompt, run three times each, GPT-6 Sol reached first byte in 2.9 to 3.1 seconds and finished in 3.4 to 3.7; DeepSeek V4.1 Flash 1017 took 2.8 to 4.0 seconds to first byte and 3.9 to 5.3 to finish.
The five prompts, so you can rerun them:
plaintext11. This Python function should return the average of every full window. moving_average([1, 2, 3, 4, 5], 2) should return [1.5, 2.5, 3.5, 4.5]. [function pasted] Find the bug, fix it, and raise a ValueError when window is less than 1 or larger than len(values). Reply with only the fixed function in a code block, then one sentence explaining the bug. 2 32. A train leaves a station at 9:40 a.m. traveling at 72 km/h. A second train leaves the same station at 10:05 a.m. on a parallel track in the same direction at 90 km/h. At what time does the second train catch up with the first? Explain it step by step for a 9th grader, then give the final answer on its own line. 4 53. Write a launch email for a reusable coffee cup that keeps drinks hot for 6 hours. Audience: people who commute by train. Rules: a subject line under 50 characters, a body of 110 to 130 words, no exclamation marks, and end with one clear call to action. 6 74. Turn these meeting notes into JSON: an array called action_items, where each item has owner, task, and due_date (YYYY-MM-DD). The meeting was on Monday, November 3, 2025. Output only valid JSON. [notes pasted] 8 95. Look at this chart. Which product grew the most in units from Q1 to Q4, and by how many units? Then name the quarter where two products came closest in sales and give the gap. [chart attached]
DeepSeek vs ChatGPT for Coding
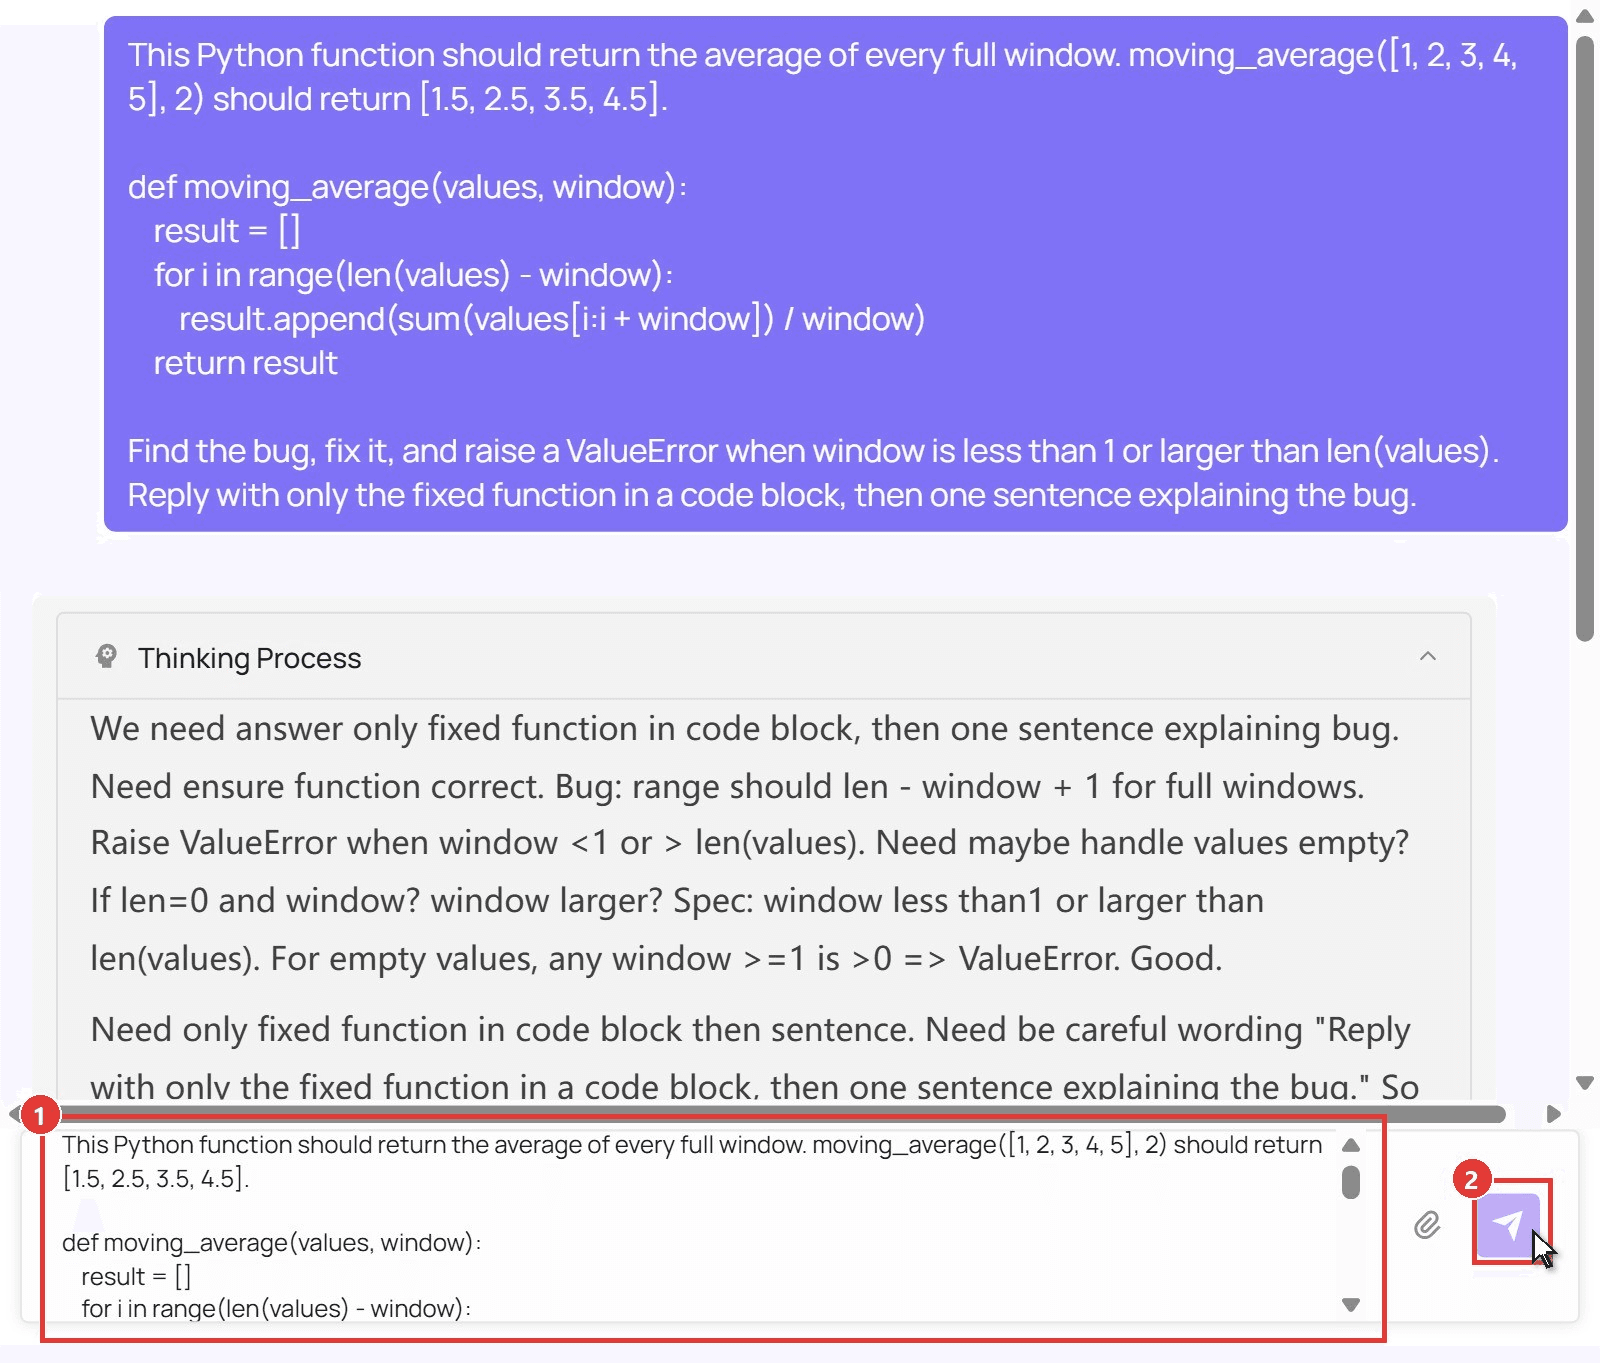
Look at the two outputs in the screenshot above. Both models spotted that the loop ran one window short and both added the guard clause with the same condition. GPT-6 Sol rewrote the body as a list comprehension; DeepSeek kept the original loop and changed only the range, the smaller diff, which is what you want from a bug fix.
One test is not a benchmark. Artificial Analysis listed GPT-6.1 Sol at 52 and DeepSeek V4.1 Flash 1017 at 45 on its Intelligence Index when we checked on October 20, 2026, with GPT-6 Luna, the free ChatGPT model, at 38; the chat-tab model GPT-6 Sol had no score that day. So the paid ChatGPT model leads on aggregate benchmarks, the free one trails DeepSeek, and on a single bug fix you will not see the difference.
Is DeepSeek Safe? Where Your Chats Go
This is the question behind a lot of "deepseek vs chatgpt" searches, and the honest answer comes from the policy pages rather than from headlines. DeepSeek's privacy policy, last updated February 10, 2026, is short and worth reading in full; the lines that matter are in the table.
| DeepSeek app | ChatGPT | |
|---|---|---|
| Where data is stored | The policy states: "we directly collect, process and store your Personal Data in People's Republic of China" | OpenAI's help center documents data controls per account; storage location is not spelled out in the consumer policy pages we reviewed |
| Training on your chats | Policy lists model training as a purpose and gives an opt-out by emailing [email protected] | An "Improve the model for everyone" toggle under Settings and Data controls turns off training on new conversations |
| Regulator actions | Italy's data protection authority blocked the service on January 30, 2025, per its own press release | None comparable on the consumer app |
The US National Institute of Standards and Technology's CAISI evaluation from September 30, 2025 found that "DeepSeek models echoed four times as many inaccurate and misleading CCP narratives as U.S. reference models did." That evaluation covered R1, R1-0528 and V3.1, not the V4 generation, so treat it as a known behavior of the earlier models rather than a verdict on today's.
The open weights change the picture for developers. Because V4.1 Flash 1017 is MIT licensed, a company can run it on its own servers or through a US-hosted API without touching DeepSeek's app. The policy above governs the app and DeepSeek's own API, not a copy of the model running elsewhere.
DeepSeek vs Claude vs ChatGPT: Where Claude Fits
Readers who search for three-way comparisons usually want to know whether Claude changes the decision. In October 2026, Anthropic's model lineup is Claude Fable 5.1, Opus 5.5, Sonnet 5.5 and Haiku 5.5, per the company's model documentation, and the Claude app has a free plan alongside Pro and Max.
| DeepSeek | ChatGPT | Claude | |
|---|---|---|---|
| Current flagship behind the app | V4.1 Flash 1017 | GPT-6 Sol (Plus and up), GPT-6 Astra (Pro reasoning) | Fable 5.1 and Opus 5.5 |
| Open weights | Yes, MIT | Not for the models behind ChatGPT; OpenAI's separate gpt-oss models are open | No |
| Free consumer plan | Entire app | Yes, with limits | Yes, with limits |
| Where it stands out in this comparison | Price per token and self-hosting | Image, voice and agent features in one app | Long-running agentic coding work, by Anthropic's own positioning |
If your work is mostly chat, writing and quick code fixes, Claude is a third option with the same shape as ChatGPT: closed weights, free tier, paid tiers. If you need the weights of the model you actually chat with, that points to DeepSeek. For a deeper look at how the current OpenAI rollout works plan by plan, see our guide to GPT-6 availability.
Which Is Better, DeepSeek or ChatGPT?
After five ties, the choice comes down to the app around the model and to policy, not to answer quality.
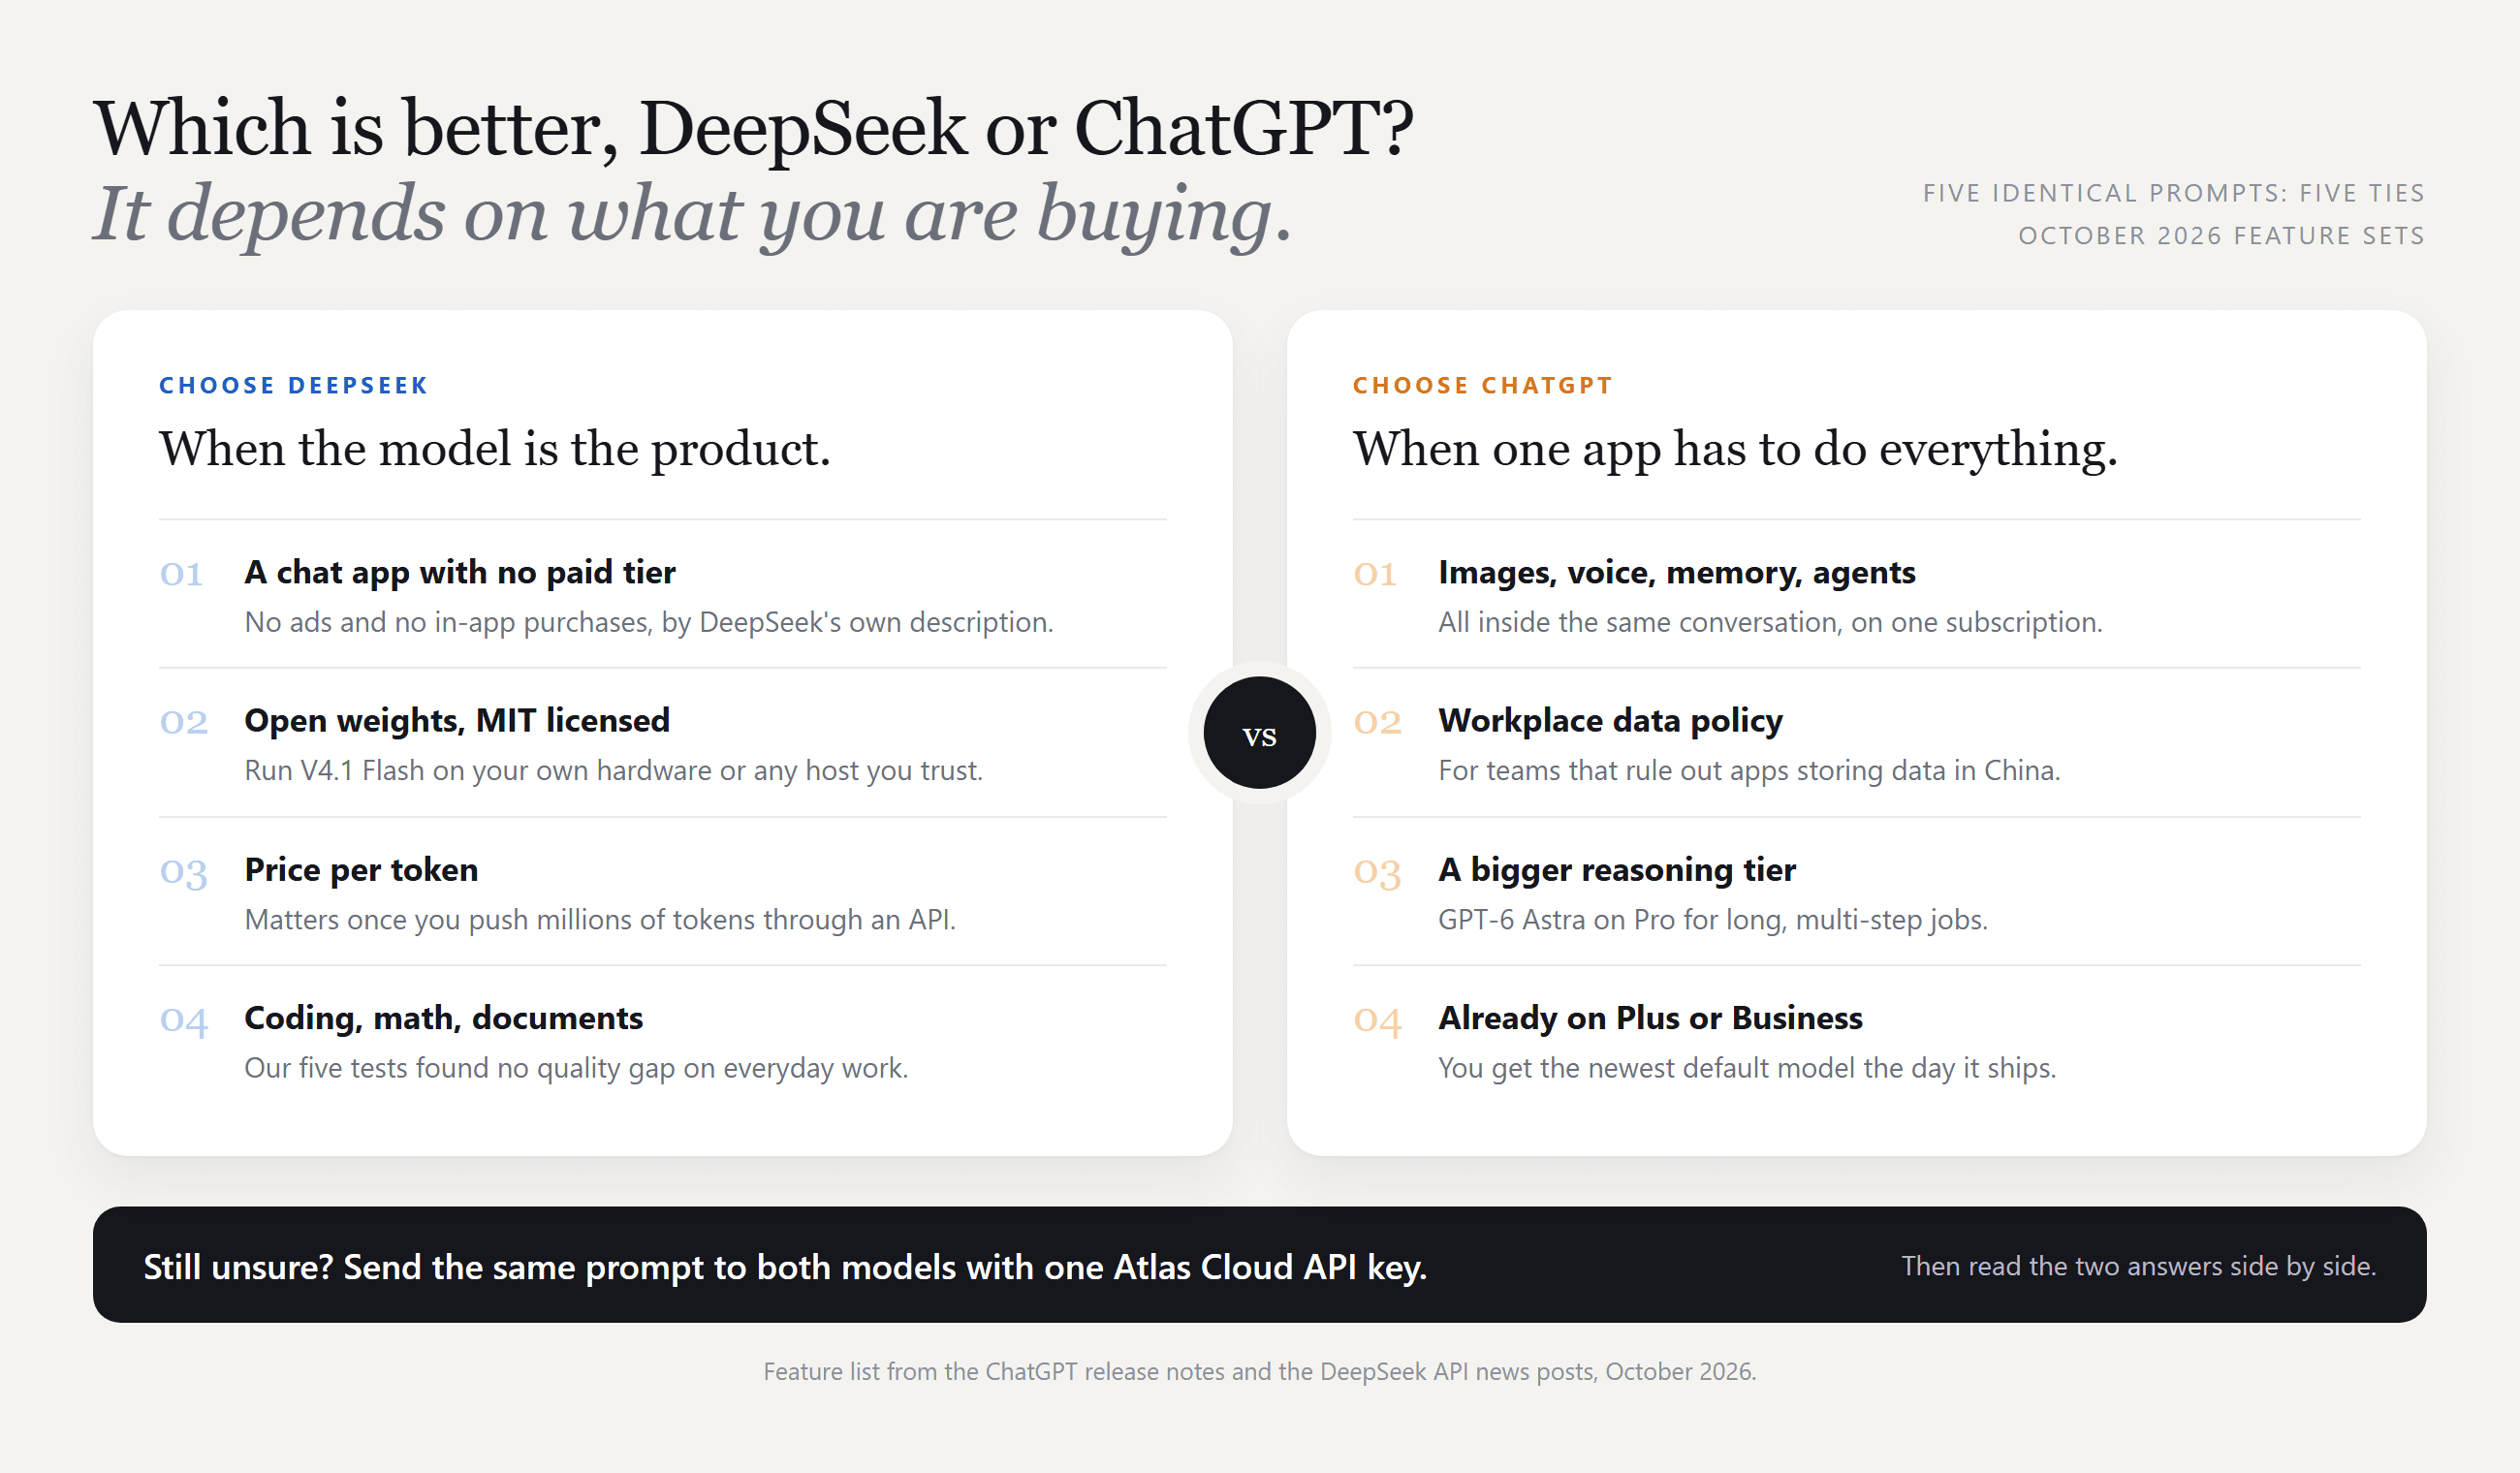
Pick DeepSeek when the model is the product for you: you want a free chat app with no upsell, you plan to self-host, or you push a lot of tokens through an API. DeepSeek's 1M-token context also opens up document jobs that we cover in our V4.1 Flash context window guide.
Pick ChatGPT when you want one app that generates images, talks back, remembers you, and runs always-on agents, or when your employer's policy rules out tools that store data in China. The paid tiers also give you GPT-6 Astra for long multi-step work, which has no counterpart in DeepSeek's app.
Developers get a third path: route both models through one gateway and switch per task. Our unified LLM API gateway article walks through that setup.
FAQ
Is DeepSeek free to use?
Yes. DeepSeek's app launch post describes the consumer app as 100% free with no ads and no in-app purchases, and the current V4.1 Flash 1017 model runs on the website and app at no charge. The API is paid per token, so a developer building on DeepSeek pays, while someone chatting in the app does not.
How much does the DeepSeek API cost compared with ChatGPT's models?
On Atlas Cloud, DeepSeek V4.1 Flash 1017 is listed at $0.30 per million input tokens and $1.20 per million output tokens. GPT-6 Sol is listed at $2 per million input and $10 per million output. Remember the reasoning overhead from our tests: DeepSeek used up to 4.2 times more output tokens on the same prompt, which narrows the real-world gap on short tasks. ChatGPT the app is priced by subscription instead: the pricing page lists Go at $8 a month, Plus at $20, and Pro from $100 with three usage tiers, the top one at $500 per the October 2026 release notes.
Is DeepSeek better than ChatGPT 5?
The question is dated now, since ChatGPT no longer runs GPT-5 by default. Against the current GPT-6 Sol, DeepSeek V4.1 Flash 1017 matched it on all five of our everyday prompts while trailing it on the Artificial Analysis index. If you last compared them in the GPT-5 era, rerun your own prompts; both sides have moved several versions.
Who owns DeepSeek?
DeepSeek is a Chinese AI company; its privacy policy names Hangzhou DeepSeek Artificial Intelligence Co. as the operator and the People's Republic of China as where user data is stored. That ownership, not model quality, is what the regulator actions above were about.
Is DeepSeek open source?
The model weights are. DeepSeek V4.1 Flash 1017 is released under an MIT license, which allows commercial use and modification, and R1 before it carried the same license. The training data and the full training code are not published, so "open weights" is the more precise term. For most teams the practical effect is the same: you can download the model and run it yourself.
Why is DeepSeek cheaper than ChatGPT?
Partly architecture and partly business model. DeepSeek's models use a Mixture-of-Experts design that activates only a fraction of the parameters per token, and the company's V3 technical report put that model's final training run at $5.576 million in rented GPU time, while noting the figure excludes prior research and ablation experiments. On the business side, DeepSeek sells API tokens and gives the app away, whereas OpenAI funds a much larger product surface through subscriptions.
Conclusion
The 2025 version of this comparison was a cheap challenger chasing a polished incumbent. In October 2026, DeepSeek V4.1 Flash 1017 and GPT-6 Sol were indistinguishable in correctness on five ordinary prompts, and what remains is tokens, features, and where your data lives.
Decide on those terms. If you want a free app or open weights, DeepSeek has both. If you want images, voice, memory and agents in one subscription, ChatGPT has them. And if you would rather test than take our word for it, the fastest way to settle DeepSeek vs ChatGPT for your own prompts is to send them to both models through one key and read the answers side by side.





