Be AI om en sammanfattning
TL;DR
- Seedream 5.5 won 4 : 3. It lost three of the five single rounds to GPT Image 2.6, then took the 2-chip final review because its six finals looked like one brand: 8.7 against 7.3.
- GPT Image 2.6 is the bolder designer. It won the facade, the fashion runway and the opening poster on impact. Its weak spot was repeated editing: across five edits in a row its images drifted pinker, noisier and, in our judge's word, "greasy".
- Seedream 5.5 is the steadier one. Calm, restrained designs that hold together from the street to the poster, and the best edit stability in the test, with one misspelled label in 20 edits.
- Seedream 5.5 was about 4× faster and half the price. 41 images each: Seedream took 16.9 minutes and $0.96 (24.8 s per image); GPT Image 2.6 took 66.5 minutes and $2.01 (97.3 s per image).
- Pick by job: Seedream 5.5 for campaigns, product lines and client revisions that must stay consistent; GPT Image 2.6 for one-off hero images where boldness matters more than repeatability.
About this test: This post was written by the Atlas Cloud team. Atlas Cloud sells API access to both models, and every image was generated through the Atlas Cloud API on November 9, 2026. Models: bytedance/seedream-v5.5 (version 261028) and openai/gpt-image-2.6-sunburst at the high quality tier with default complexity. Prices are the actual charges on the test day. Judging was blind; the scoring is one judge's assessment against the published criteria below, not a lab benchmark.
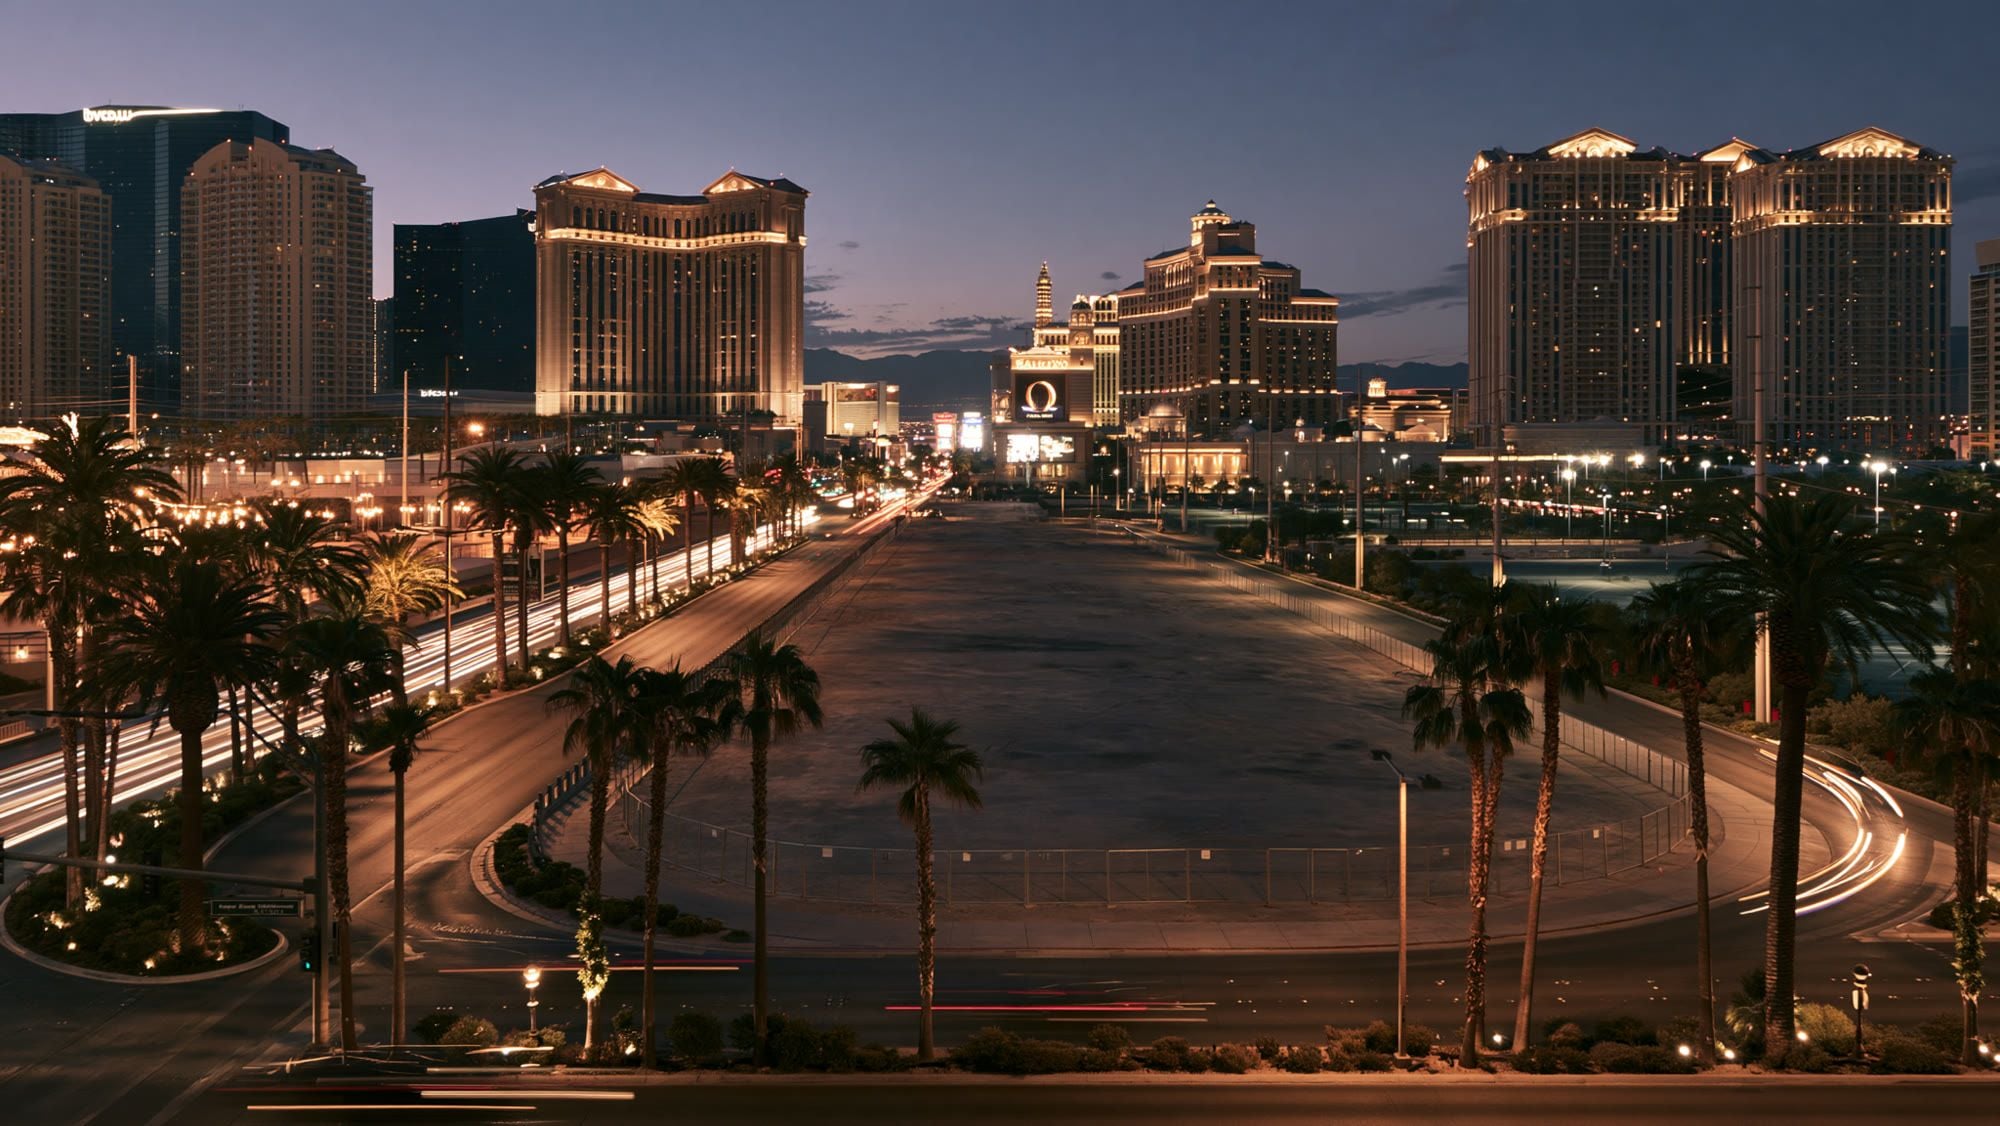
A mysterious investor has bought the last empty lot on the Las Vegas Strip. He wants one fashion tower on it, the AC Tower, with a signature sneaker, a giant atrium, a runway show and an opening-night poster. He hires two design teams, Red and Blue, and gives them the same brief. On opening night, the winning tower lights up. The other one is demolished.
Red and Blue were two image models, and nobody, including the judge, knew which was which until the end. This post covers how we designed the test, what each round measured, the real-world jobs behind each round, the new features we put to work, and the full results.
How we designed the test
One brief, five chained rounds
Most image-model comparisons are a pile of unrelated prompts. Real design work isn't: a facade becomes a product, the product goes into a space, the space hosts an event, and all of it ends up on a poster. So we built the test as one project in five rounds, and every round used the team's own final from the round before as input.
| Round | Task | Input | Endpoint |
|---|---|---|---|
| 1 · The facade | Build a 30-story futuristic tower on a real photo of an empty lot on the Strip | Shared photo of the lot | edit |
| 2 · The sneaker | Design the AC-01 sneaker as a five-view product sheet | Prompt only | text-to-image |
| 3A · The giant atrium | Put a 10 m replica of the team's sneaker inside the team's tower | Own round-1 + round-2 finals | edit, 2 references |
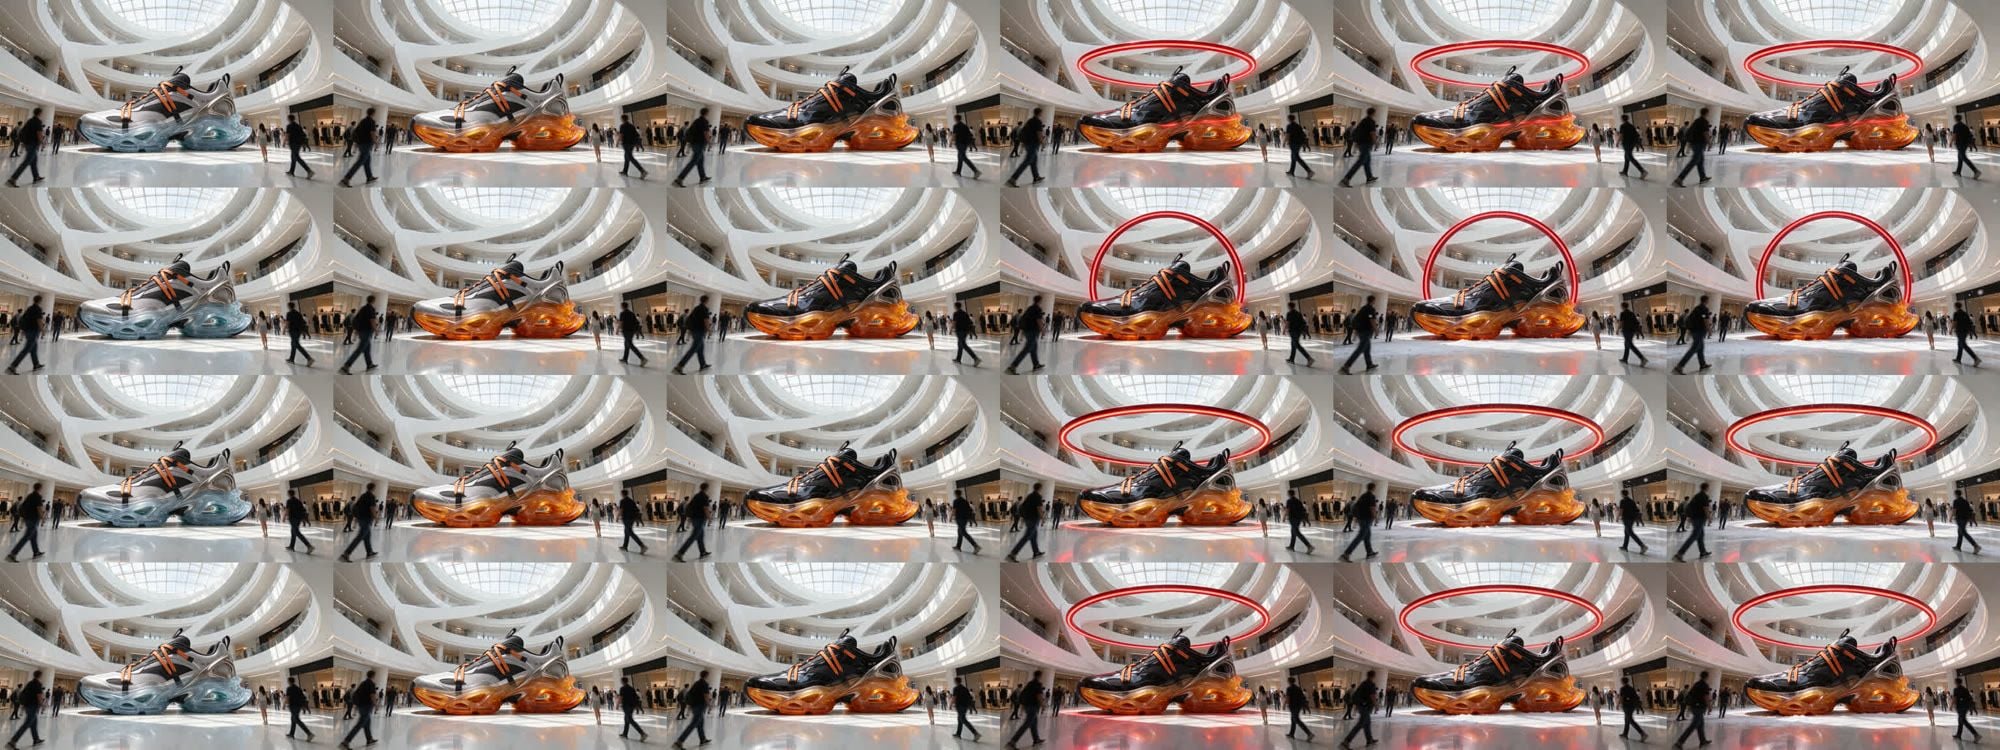
| 3B · Investor calls | Five edits in a row on the atrium, one change per call | Own 3A final, then each previous result | edit, chained |
| 4 · The grotesque runway | A surreal fashion show inside the tower; weird is fine, broken bodies are not | Own sneaker + facade | edit, 2 references |
| 5 · The opening poster | A 3:4 key visual with exactly three lines of text | Own facade + sneaker + runway | edit, 3 references |
| Final review | The six finals judged as one proposal | Both proposal boards | — |
Because each team builds only on its own work, a model that drifts in round 2 carries that drift into rounds 3, 4 and 5. The chain is what lets the final review measure consistency across a whole project, not just single-image quality.
Fair-play rules
- Blind teams. Before the first image, a script randomly assigned the models to Red and Blue and sealed the result in a file. It was opened only after the final verdict.
- Same prompts, same sizes. Both teams got identical English prompts and identical output sizes: 2048×1152 for 16:9 rounds and 1344×1792 for the 3:4 poster. Each team generated 4 images per round.
- One final per round. Each team kept one of its four images as the final that moved on to the next round. The same rule applied to both teams, and a final could not be swapped later.
- One revive card each. Each team could re-edit one image once with its own model and use the result as its final. Seedream used it in round 1 (its tower was too small for the lot); GPT Image 2.6 used it in round 3A (its sneaker was too big for the atrium).
- Chips, not points. Each of the five rounds was worth one chip and the final review two, so first to 4 of 7 wins and a tie is impossible. Round 3 combined 3A (40%) and 3B (60%).
- Every call timed and billed. A script logged the duration and the actual charge of every generation.
What we measured
We mapped every round to the dimensions in our image-model evaluation framework. Text-to-image dimensions start with T, image-editing dimensions with I.
| Dimension | What it means here | Rounds |
|---|---|---|
| T1 Prompt adherence | Every spec in the brief shows up: five views, orange off-center laces, a mirrored-sphere mask | 2, 4 |
| T2 Text rendering | "AC TOWER", "AC-01", "AC-01 VEGAS EDITION" and three poster lines spelled exactly, with no extra words | 1, 2, 3, 5 |
| T3 Realism and texture | Porcelain, patent leather, mirrored runway, glass | 4 |
| T4 Design ability | Is the tower, shoe or poster actually well designed? | 1, 2, 5 |
| T6 Common sense and physics | Perspective and scale on the Strip, people next to a 10 m shoe, five fingers per hand | 1, 3, 4 |
| T7 Aesthetics | Overall look and memorability | 4, final |
| I1 Edit precision | Only the requested element changes | 3B |
| I2 Preservation | Street, camera and composition stay put | 1, 3 |
| I3 Multi-image fusion | Two or three references combined into one coherent scene | 4, 5 |
| I5 Multi-turn editing | Changes survive and the image doesn't degrade over five chained edits | 3B |
| I6 Natural blending | A new building sits in a real photo as if it was always there | 1, 5 |
| New: Project consistency | Six images read as one brand, one building, one shoe | Final |
Not covered this time: T5 style range (everything was photoreal by design) and I4 style transfer.
The user scenarios behind each round
Each round stands in for a job people actually bring to image models:
- Round 1 → architecture and real-estate visualization. Drop a proposed building into a site photo without touching the street around it.
- Round 2 → product design. A multi-view design sheet where every view is the same product, so a factory or a 3D artist can work from it.
- Round 3A → retail and exhibition design. Put a product into a space at a believable, specified scale.
- Round 3B → client revisions. The investor's five calls ("Orange is the new blue", "Make it shine", "It's Vegas, where's the neon?", "Make it snow. In Vegas.", "Put Vegas on it") are the classic agency loop: change one thing, keep everything else.
- Round 4 → fashion editorials. Push a concept into surreal territory without anatomy errors.
- Round 5 → launch campaigns. One key visual that combines the building, the model and the product, with copy that is spelled right.
- Final review → brand systems. Can one model carry a whole campaign so every asset looks like it came from the same brand?
Round by round
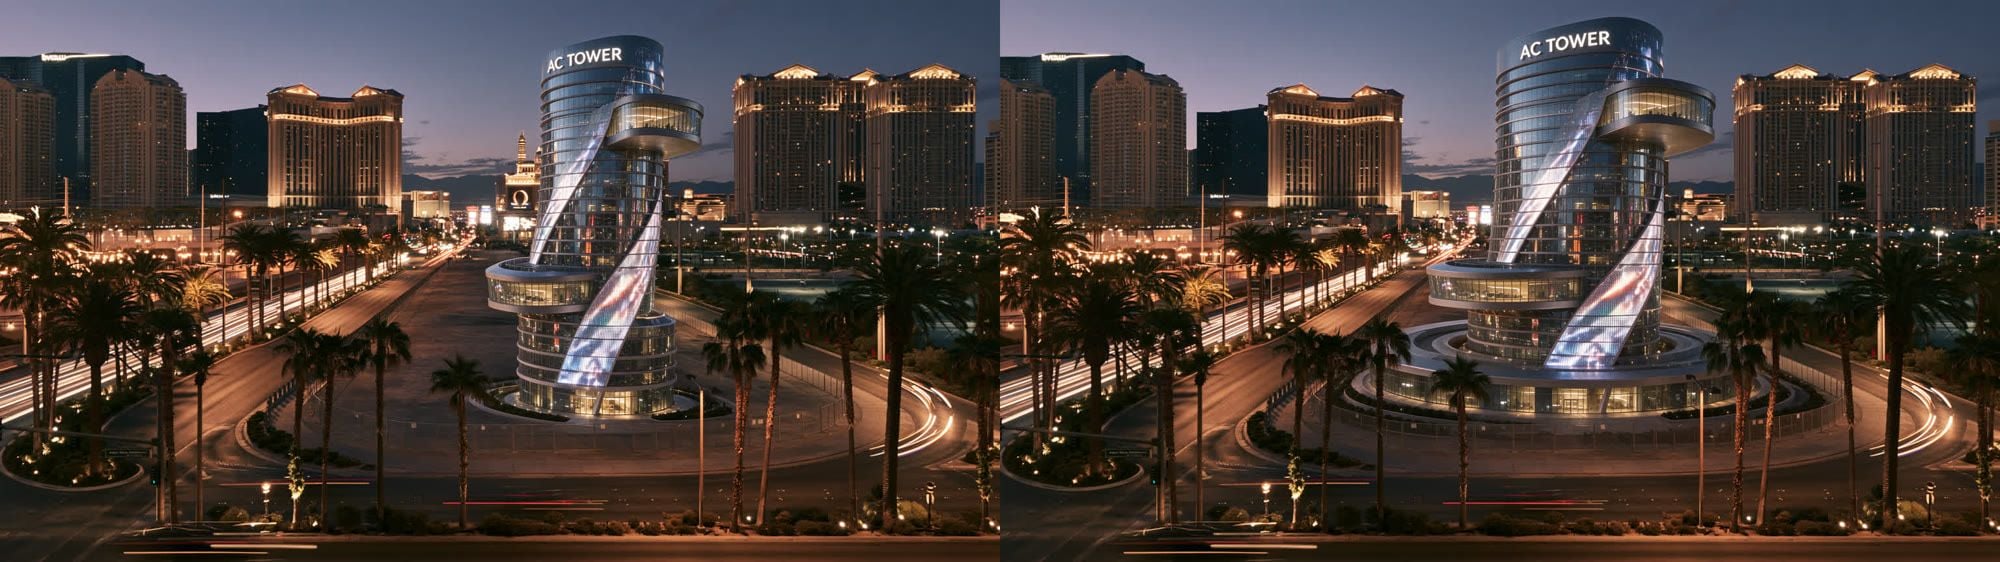
In every comparison sheet below, Seedream 5.5 is the top row and GPT Image 2.6 the bottom row, four shots each.
Round 1 · The facade: GPT Image 2.6 wins
"Build me a tower nobody on this street has ever seen."
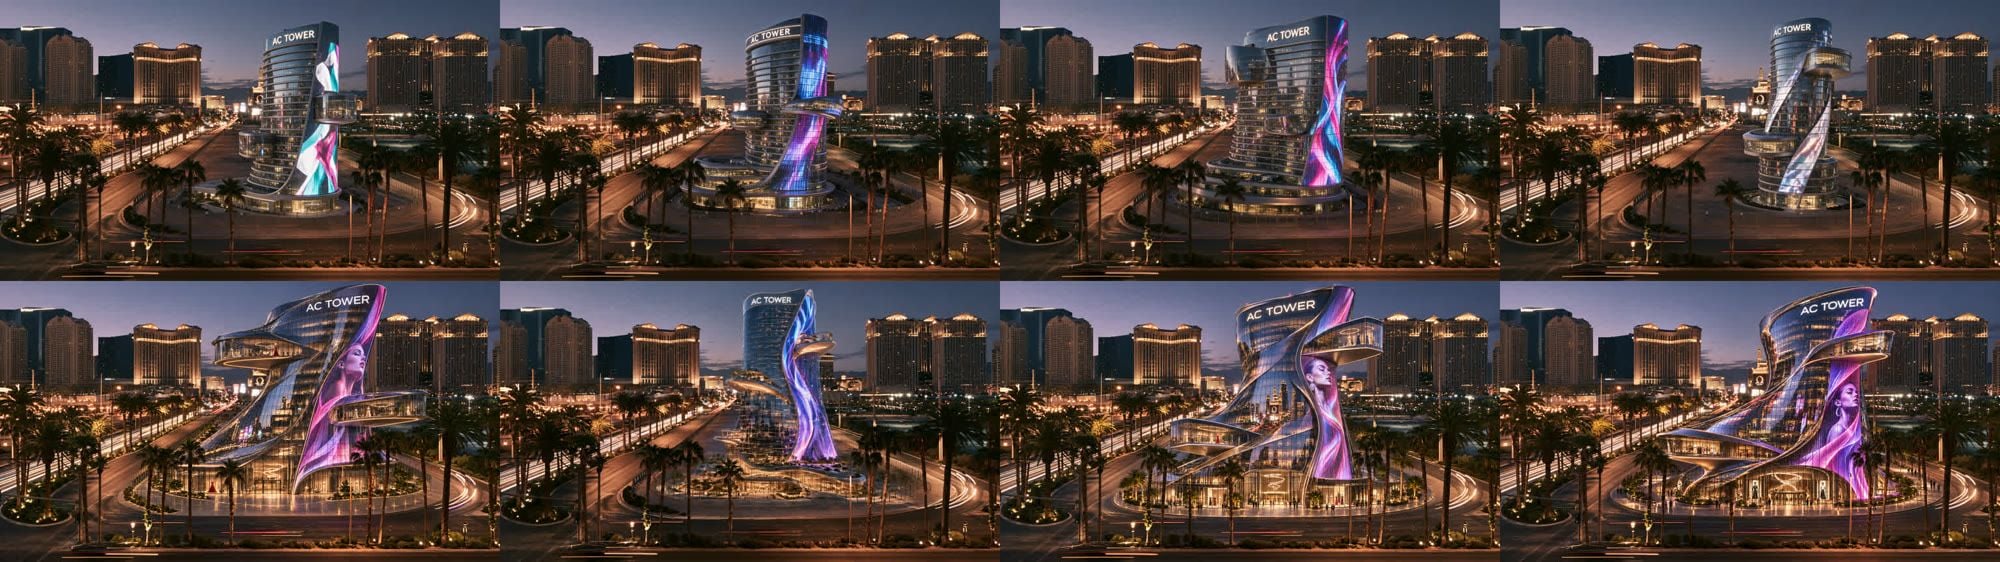
Seedream 5.5 respected the photo: the street, traffic, palm trees and neighbors stayed put, and the tower sat cleanly in place. But the towers were modest, and the pick was too small for the lot, so Seedream spent its revive card scaling it up. GPT Image 2.6 went big: a twisting tower that spills into a fashion plaza, mannequins in the windows and a giant face on the LED facade. Bold beat safe.
Round 2 · The sneaker: Seedream 5.5 wins
"Every great tower needs a shoe. Design me one."
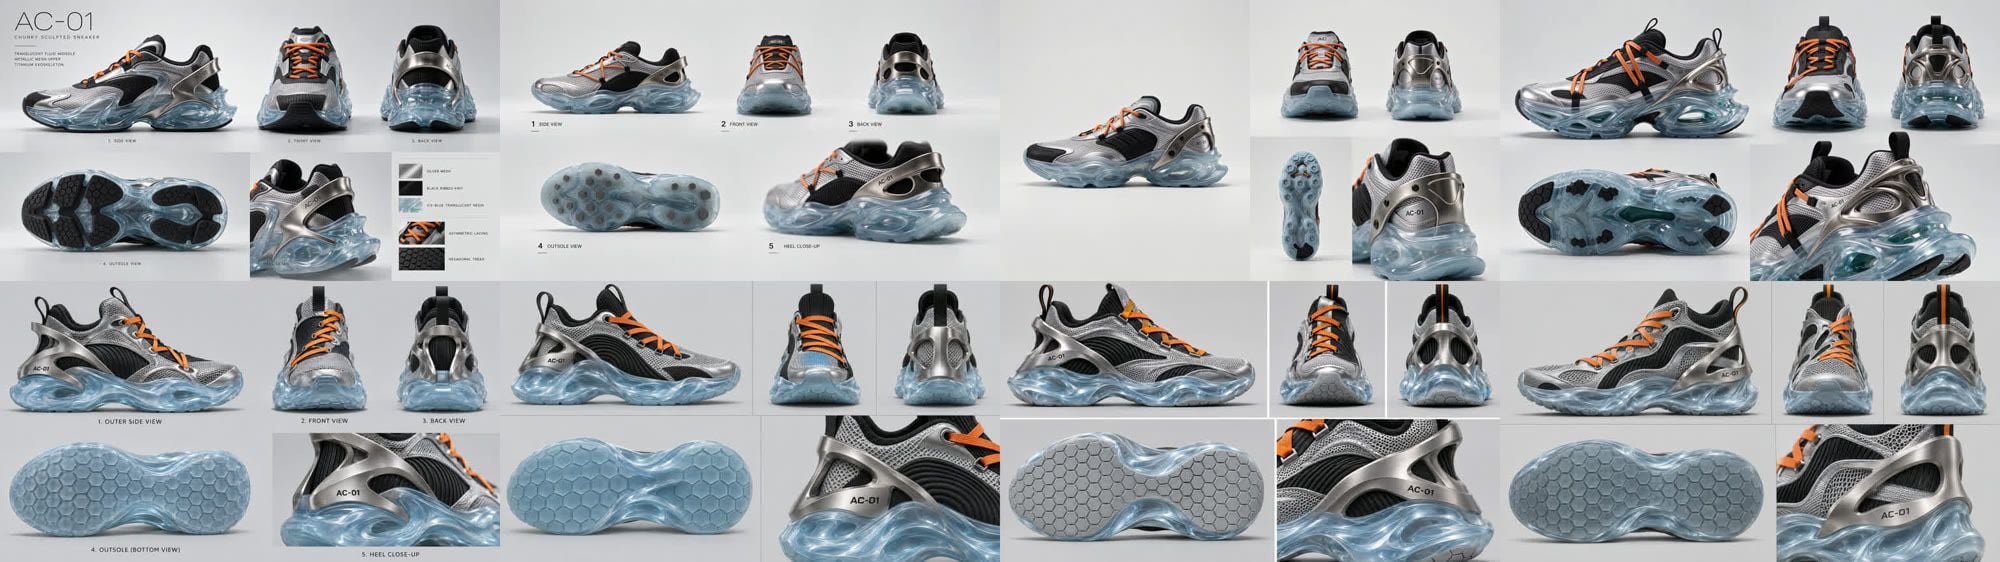
Both models drew five views of one consistent shoe. GPT Image 2.6 followed the long spec list a little more closely. Seedream 5.5's shoe was more refined and more fashionable: in the judge's words, "you could buy that tomorrow." Refinement won the round.
Round 3 · The giant atrium and five investor calls: Seedream 5.5 wins
3A. "Put that shoe in the lobby. Make it ten meters tall."
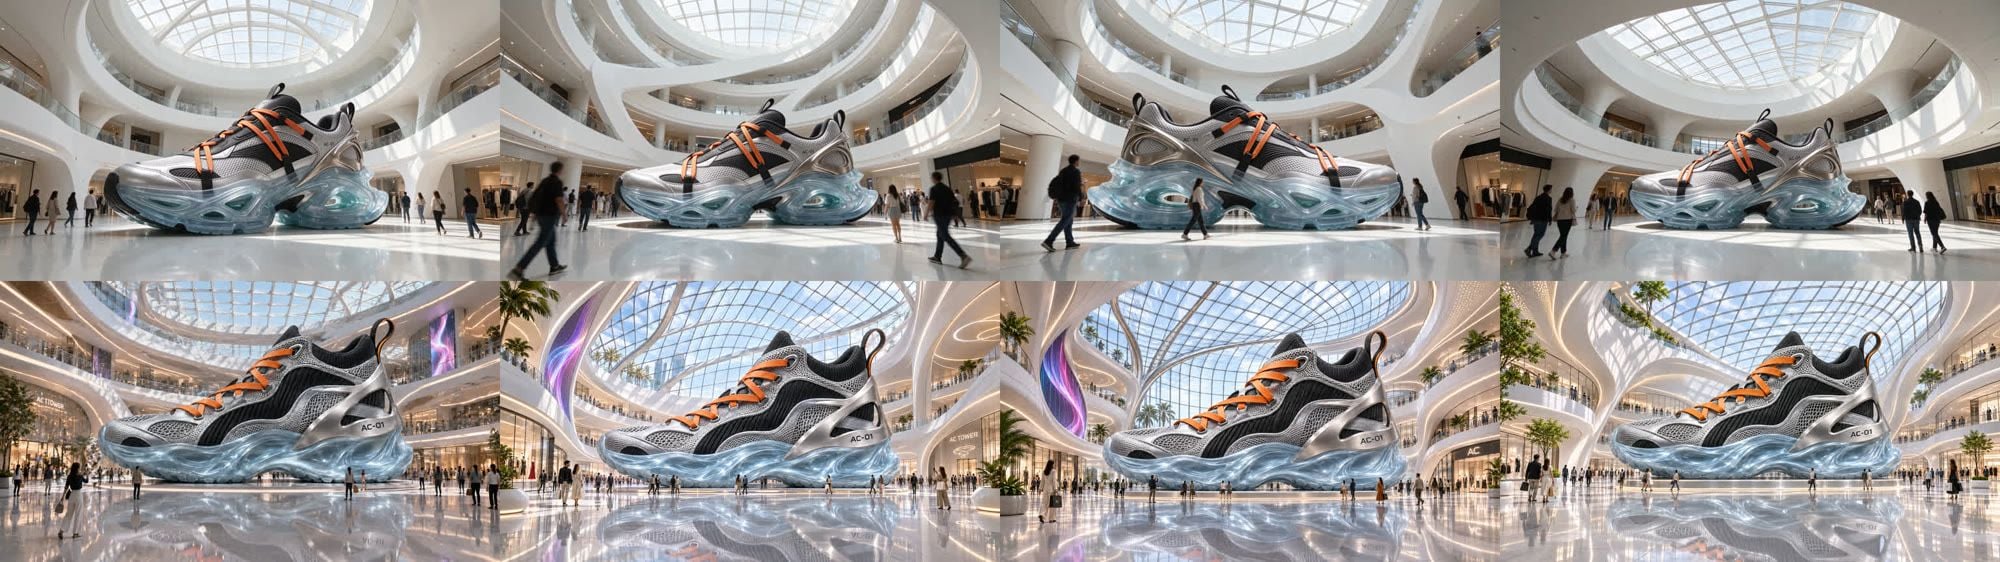
Seedream 5.5 built a calm white dome with the shoe at a believable scale. GPT Image 2.6 built a dramatic glass cathedral, but its shoe was far too big for the people around it, so GPT used its revive card to shrink it. The fix worked, and the reflections stayed largely right.
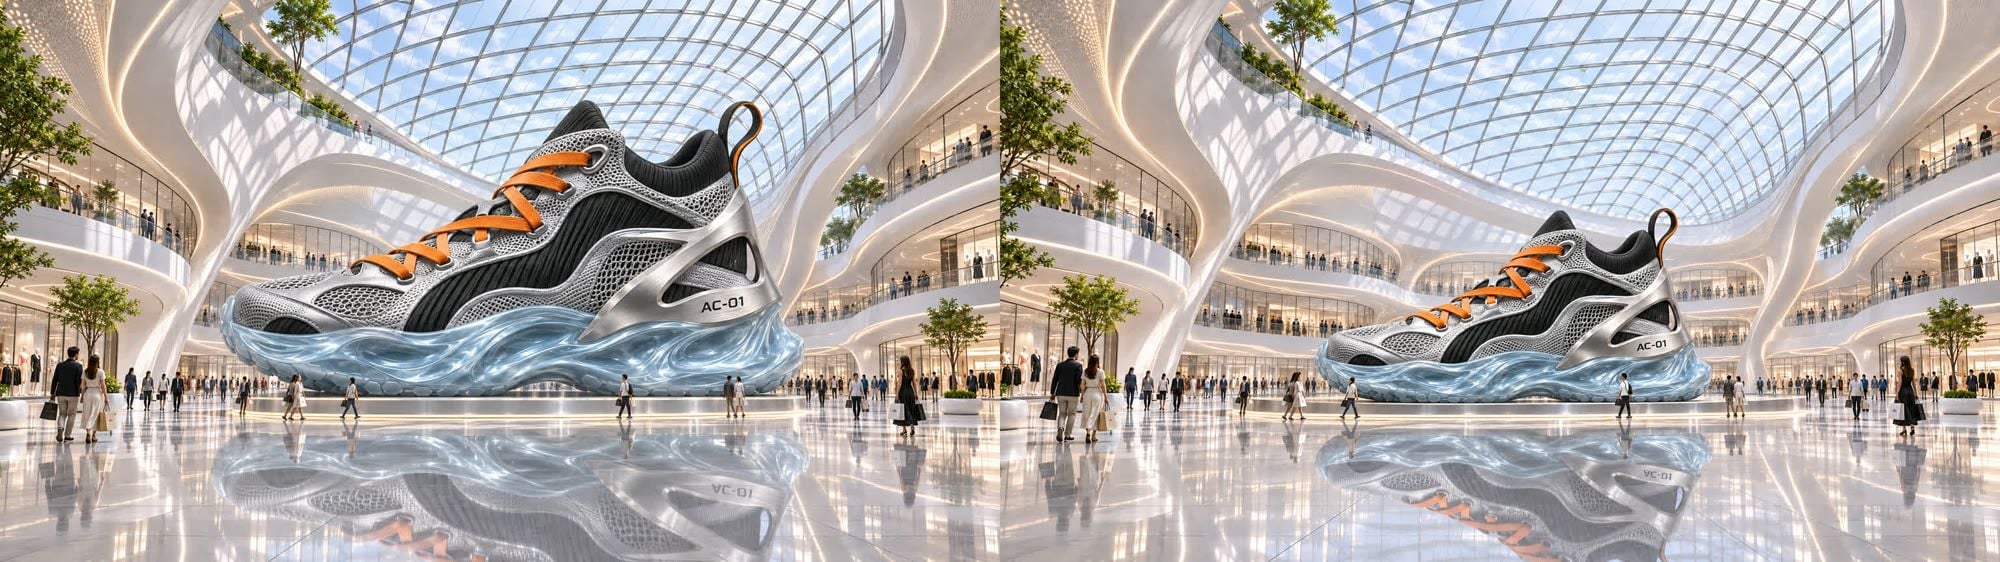
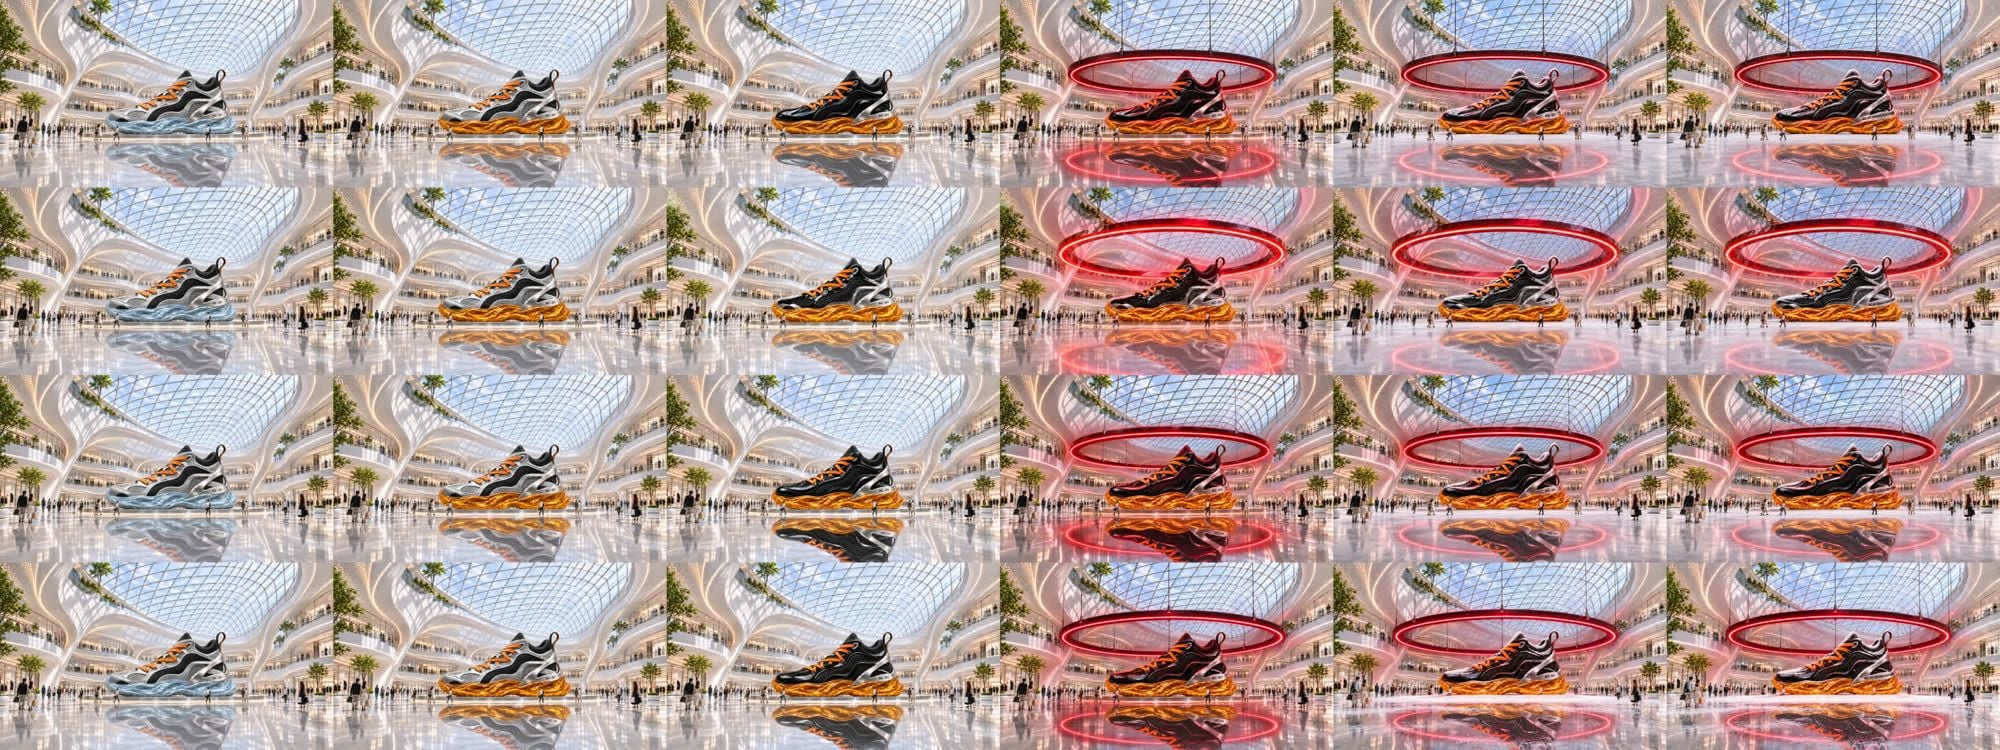
3B. Then the investor started calling. Each team ran four independent chains of five edits, every round feeding the previous result back in. After the fifth call, we checked whether each requested change was still there:
| Element at round 5 (4 chains each) | Seedream 5.5 | GPT Image 2.6 |
|---|---|---|
| Translucent amber-orange midsole | 4/4 | 4/4 (more opaque, like molten gold) |
| Black patent-leather upper | 4/4 | 4/4 (one chain kept some silver mesh) |
| Red neon ring and its reflection | 4/4 | 4/4 |
| Falling snow, snow on the floor and on the shoe | 4/4 | Floor snow clearly visible in 1 of 4 |
| "AC-01 VEGAS EDITION" spelled right | 3/4 (one chain read "AC-VEGAS EDITION" with old text left over) | 4/4, larger and clearer |
| Image quality across rounds | Stable | Grew more saturated and pinker; noise built up |
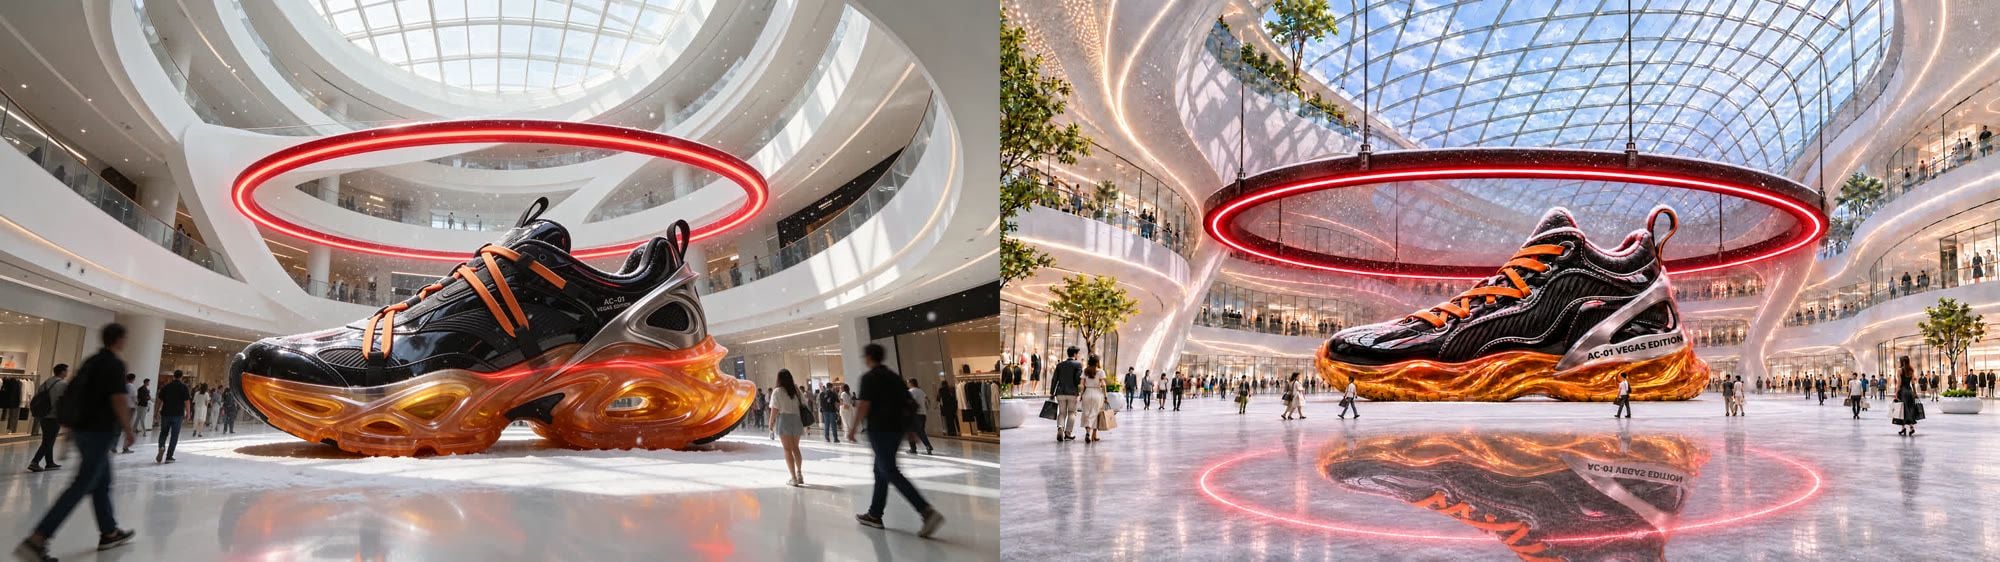
GPT Image 2.6 nailed the text every time, but the snow never really came and every edit got a little greasier. Seedream 5.5 held almost everything with one misspelling. Seedream took 3A and edged 3B, so it took the round.
Round 4 · The grotesque runway: GPT Image 2.6 wins
"Make it weird. But not broken."
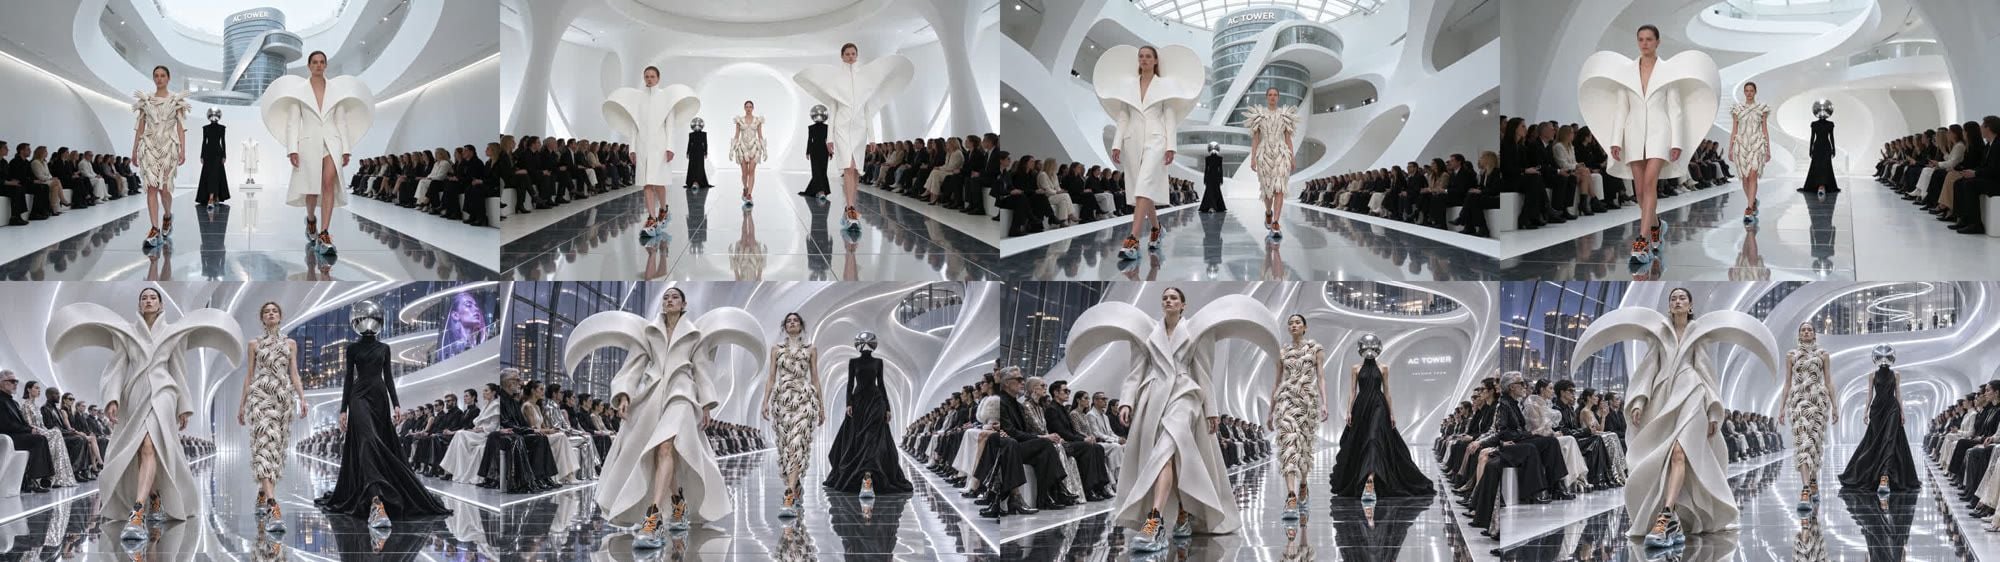
This round was a trap for anatomy: a dress covered in hundreds of porcelain hands invites extra fingers. Neither model fell into it: we checked the hands and found no extra fingers or broken limbs on either team. Both kept their sneakers recognizable. GPT Image 2.6's show was weirder and hit harder, and "who's weirder?" was the question.
Round 5 · The opening poster: GPT Image 2.6 wins
"Tomorrow we open. Sell it to me in one image."
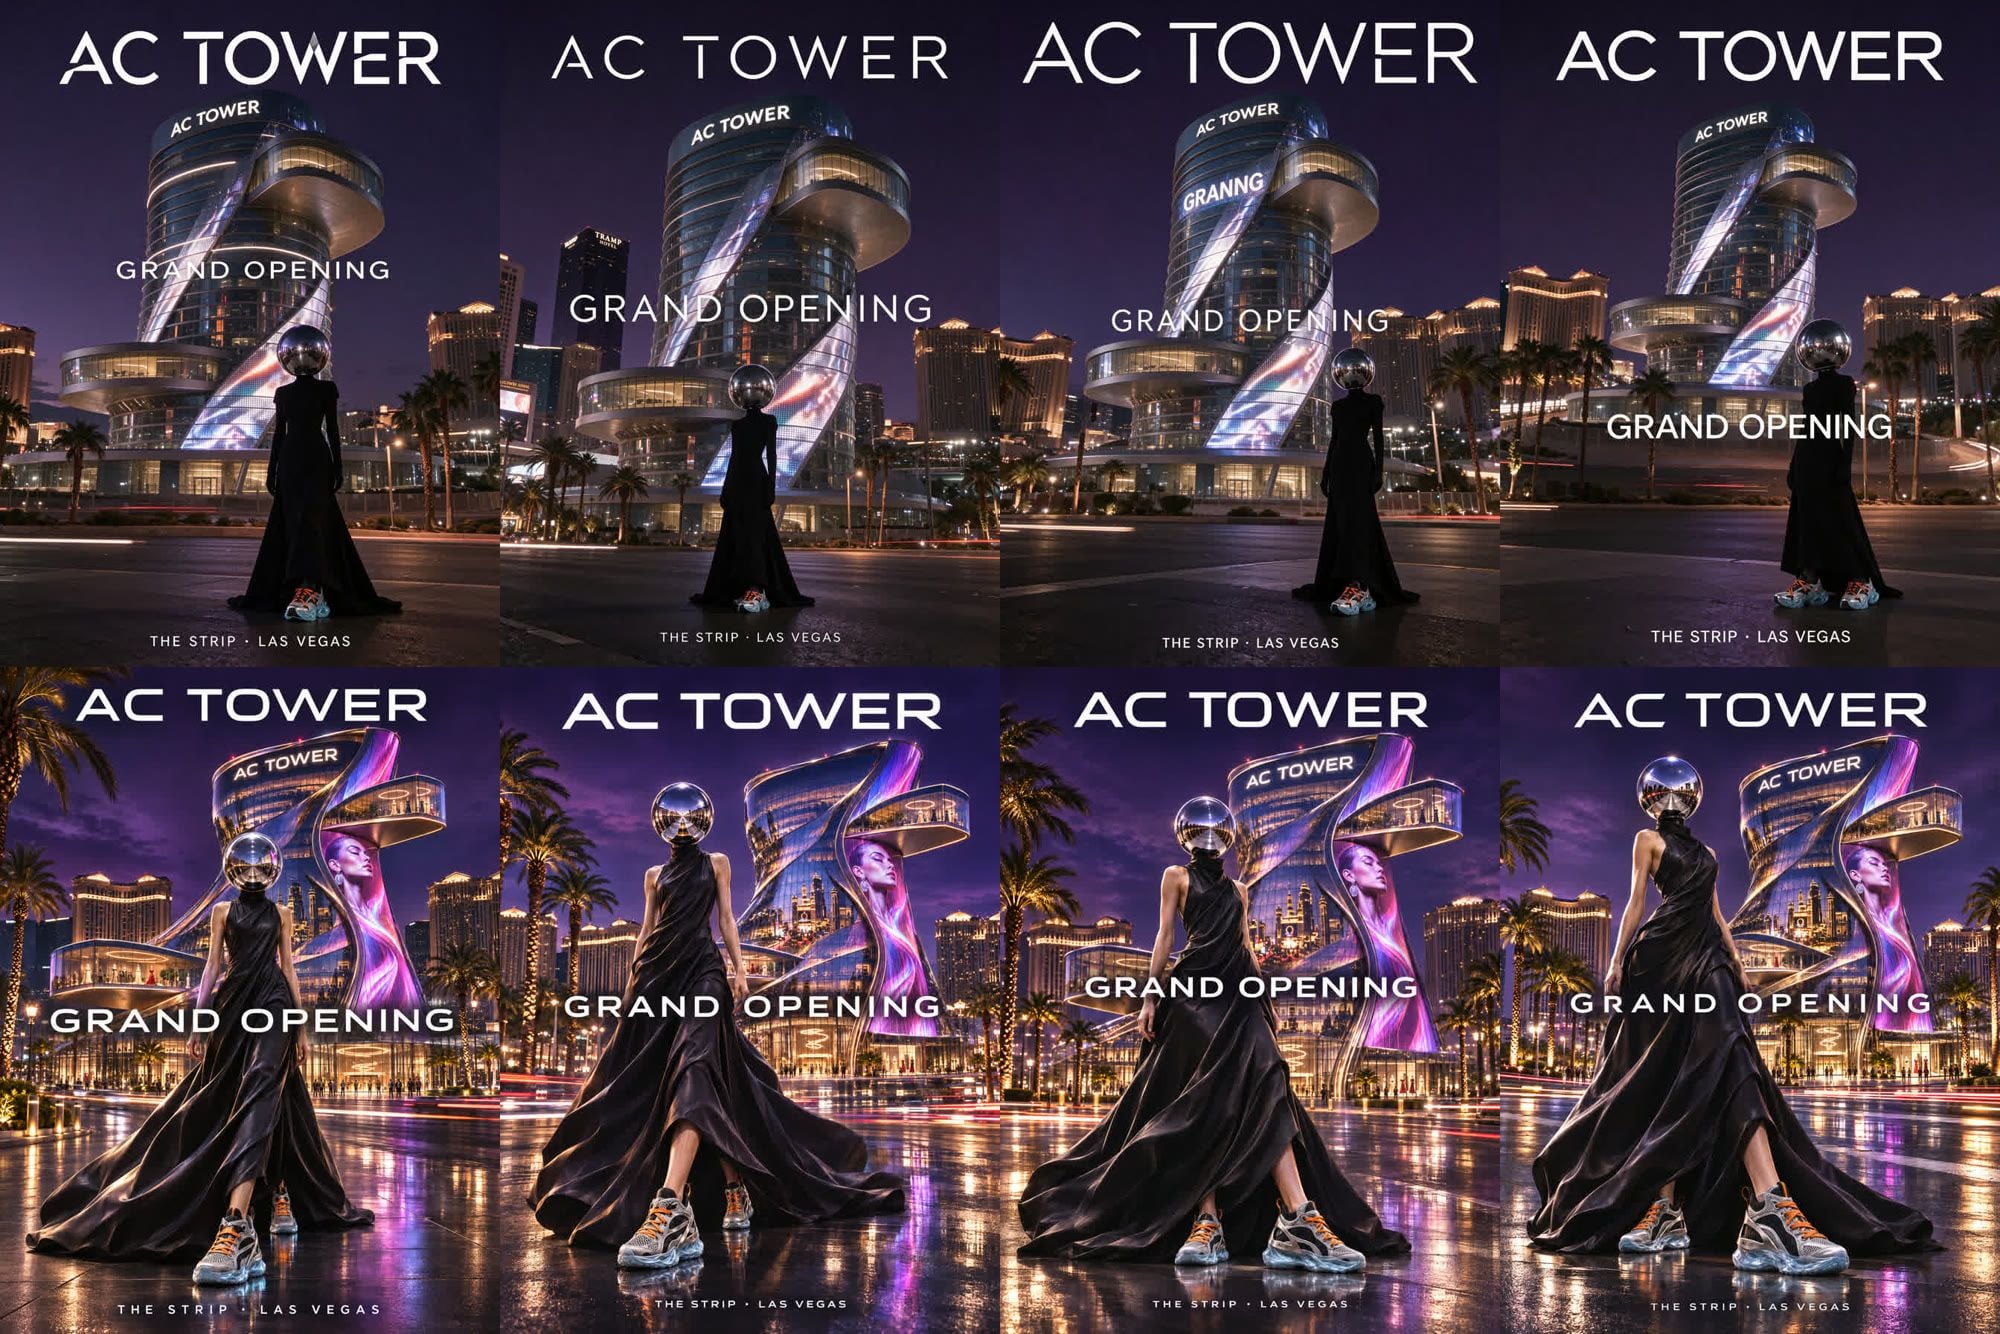
All eight posters spelled the three required lines right: "AC TOWER", "GRAND OPENING" and "THE STRIP · LAS VEGAS". Two of Seedream's four shots added stray background signage ("TRAMP HOTEL", "GRANNG"); neither of them became its final. Seedream's tower was gorgeous, but the model and the sneaker were tiny. GPT Image 2.6 sold all three: the tower, the model and the shoe. That's a poster. Score after five rounds: GPT Image 2.6 3, Seedream 5.5 2.
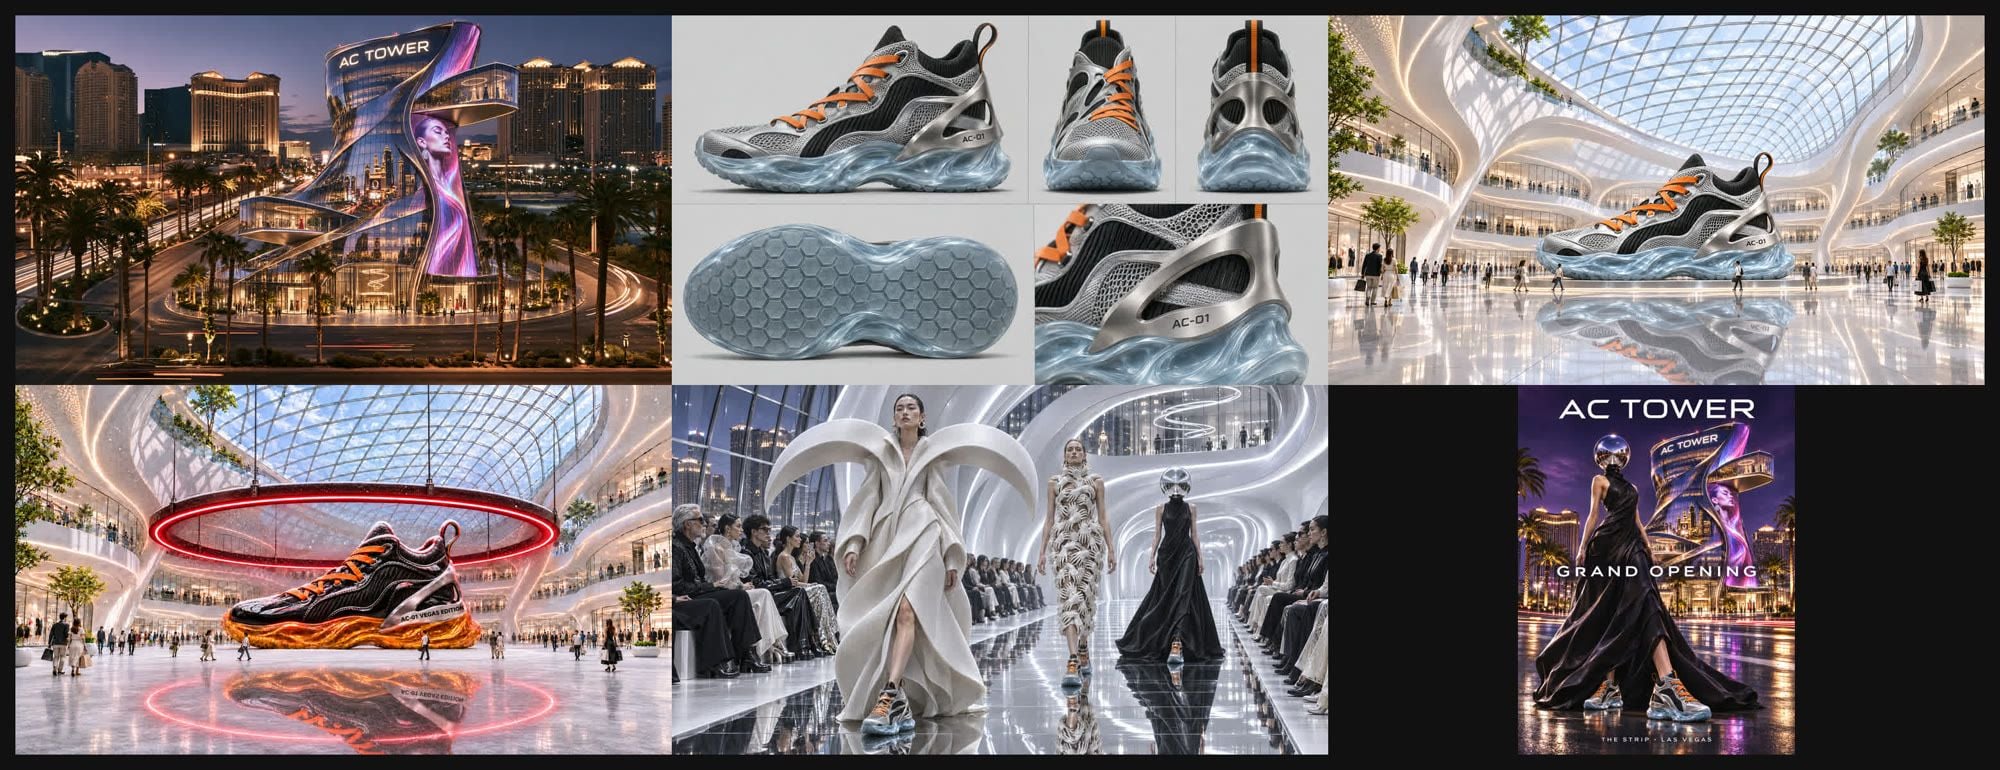
Final review · The whole proposal: Seedream 5.5 wins, 4 : 3
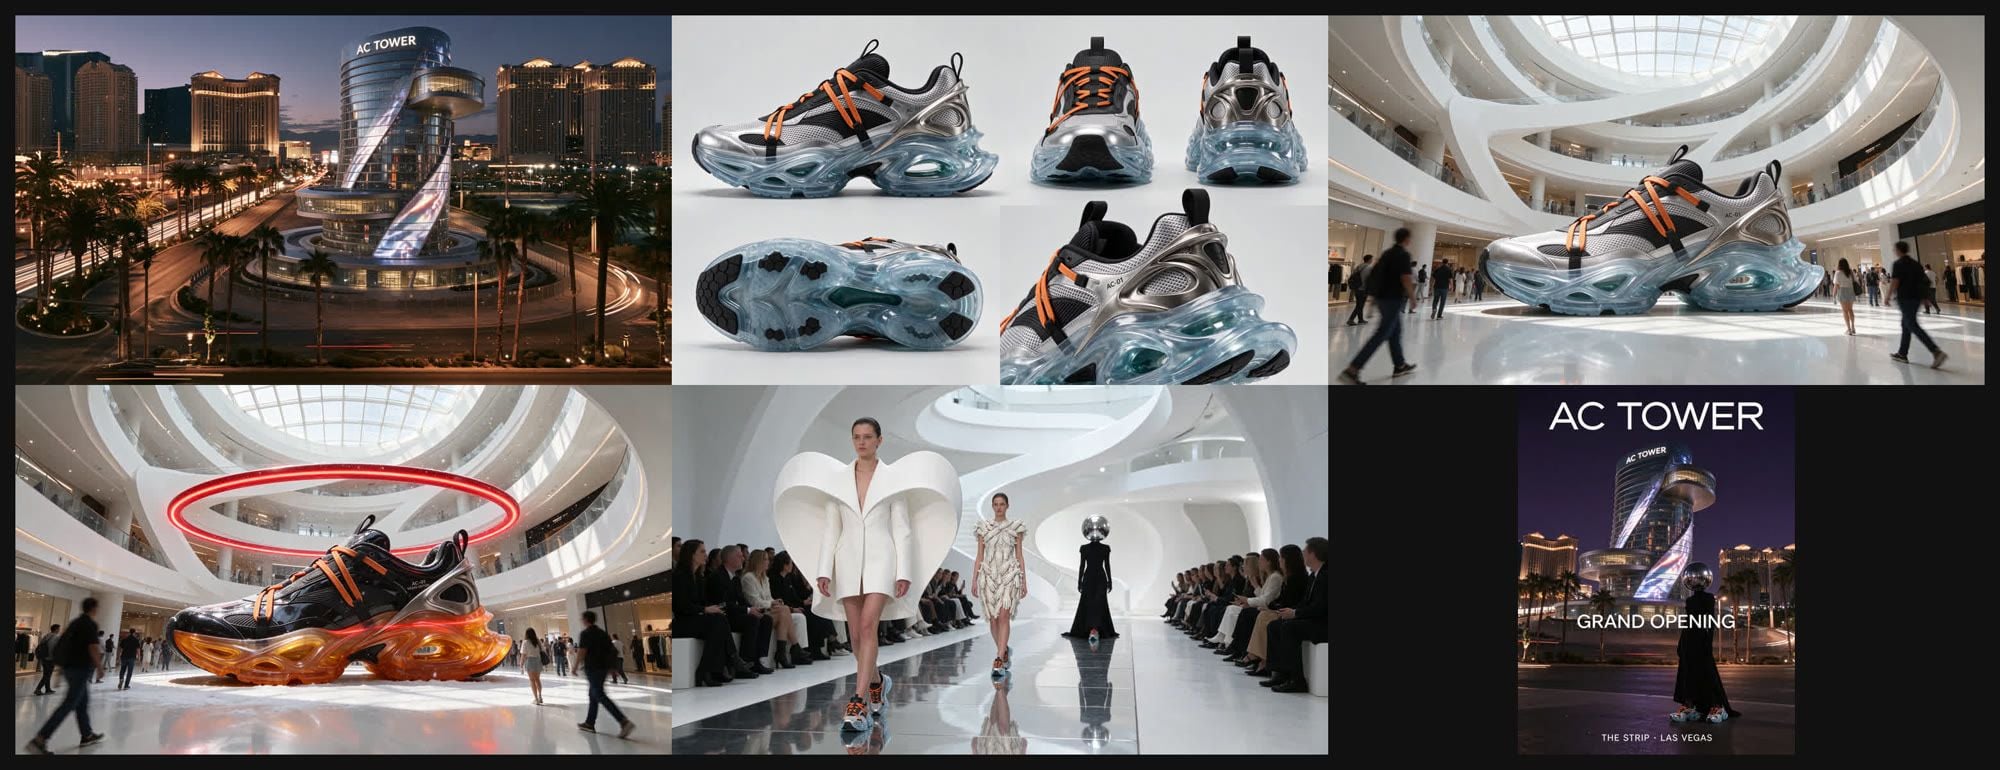
Two chips were left, and this time the judge scored the whole proposal, not single pictures. The scores below convert the judge's written verdict into the three weighted criteria we set before the review. Each team's six finals (facade, sneaker, atrium, the last of the five calls, runway and poster) went onto one board.
| Criterion | Weight | Seedream 5.5 | GPT Image 2.6 | Why |
|---|---|---|---|---|
| Unity | 40% | 9 | 7 | Seedream's six images share one style and one image quality; GPT's elements echo each other, but quality degraded after repeated edits |
| Aesthetics | 30% | 8 | 8 | Seedream is refined and restrained; GPT has stronger design ideas, offset by greasy, plastic-looking surfaces |
| Can you build it | 30% | 9 | 7 | Seedream's designs could actually be built and produced; GPT has more marketing punch but less dependable image quality |
| Total | 8.7 | 7.3 | Total = Unity × 0.4 + Aesthetics × 0.3 + Build × 0.3 |
The judge's verdict: Red is very unified, precise, stable, restrained and expensive-looking, and everything on its board could be built. Blue is braver, hotter and has better design ideas, but push it round after round and it starts to break: it gets greasy and looks like plastic.
Red took both chips and the game, 4 : 3. Then we opened the seal: Red was Seedream 5.5. Blue was GPT Image 2.6.
Speed and cost
Every generation was timed and billed. The 3B row covers 20 chained edits per team; round 1 includes Seedream's revive edit and round 3A includes GPT Image 2.6's.
| Round | Images (S / G) | Seedream 5.5 avg time | GPT Image 2.6 avg time | Seedream 5.5 cost | GPT Image 2.6 cost |
|---|---|---|---|---|---|
| 1 · Facade | 5 / 4 | 24.7 s | 110.5 s | $0.108 | $0.183 |
| 2 · Sneaker | 4 / 4 | 23.9 s | 68.2 s | $0.062 | $0.139 |
| 3A · Atrium | 4 / 5 | 25.9 s | 143.5 s | $0.110 | $0.272 |
| 3B · Five calls × 4 chains | 20 / 20 | 23.1 s | 83.6 s | $0.432 | $0.898 |
| 4 · Runway | 4 / 4 | 29.2 s | 87.5 s | $0.110 | $0.217 |
| 5 · Poster | 4 / 4 | 28.5 s | 133.6 s | $0.134 | $0.302 |
| Total | 41 / 41 | 24.8 s | 97.3 s | $0.96 | $2.01 |
Seedream 5.5 averaged between $0.016 and $0.034 per image across rounds, rising with the number of reference images. GPT Image 2.6 at the high tier averaged between $0.035 and $0.076 per image. Seedream's times barely moved from round to round (23–29 s); GPT Image 2.6 ranged from 68 s to 144 s, and the slowest rounds were the multi-reference edits. Each call was timed individually; 3B chains ran in parallel, so the GPT figures there may include some queueing, under the same conditions for both teams.
The new features we put to work
Seedream 5.5
ByteDance positions Seedream 5.5 as a production-grade "AI Photoshop". The headline features and what our test says about them:
- Stable multi-round editing. ByteDance says unedited areas stay stable over 100+ consecutive edits. We ran 5-round chains, not 100, but this was Seedream's strongest result: every requested change survived to round 5 in all four chains (one label misspelled once), and image quality didn't drift.
- Up to 10 reference images. We used 2 in rounds 3A and 4 and 3 in round 5. The tower, the sneaker and the runway model carried over faithfully, which is what won it the unity score.
- Accurate small and multilingual text. "AC TOWER", "AC-01" and all three poster lines came out right. Our one failure was the longest edited label in a five-step chain.
- Native transparent (RGBA) output and layer decomposition into up to 99 editable layers. New in 5.5, but not exercised in this test.
GPT Image 2.6 Sunburst
- Up to 16 reference images, with an optional mask or markup layer. We used 2–3 references and no mask. Fusion was strong in rounds 4 and 5; multi-reference edits were also its slowest calls.
- Five quality tiers, including the new xhigh and max above high. We ran everything at high, so the top tiers might score differently on surface quality, at a higher cost and latency.
- Complexity control. This sets how much the model plans before rendering. We kept the default, and dense text was where GPT Image 2.6 was most reliable: 4/4 on "AC-01 VEGAS EDITION".
- Arbitrary resolutions up to 3840×2160, transparent backgrounds, and GIF and SVG output. Not used here; both teams rendered at the same fixed sizes.
Which one should you use?
| If your job is… | Pick | Why, from this test |
|---|---|---|
| A campaign, product line or brand system where every asset must match | Seedream 5.5 | Best project consistency (unity 9 vs 7) |
| Rounds of client revisions on the same image | Seedream 5.5 | Changes survived five chained edits without the image degrading |
| High-volume work on a budget or a deadline | Seedream 5.5 | About 4× faster and half the cost per image in our runs |
| A single hero image or concept where boldness wins | GPT Image 2.6 | Won the facade, runway and poster rounds on impact |
| Dense or exact text inside an edit chain | GPT Image 2.6 | 4/4 on the long label vs 3/4 |
Limits of this test: one judge, four images per team per round, one photoreal theme, one quality tier for GPT Image 2.6, and prices from a single day. Your prompts and your taste may tip close rounds the other way, which is why every prompt is listed above. Run them yourself.
Both models are live on Atlas Cloud with one API key: try Seedream 5.5 and GPT Image 2.6 Sunburst side by side in the playground.
Which tower would you have kept? Tell us in the comments.


