Lindy بنيت الموظف الذكي. نقلت أسطولها إلى أوزان مفتوحة مقدّمة من Atlas Cloud، وخفّضت فاتورة الاستدلال بنحو 90%، دون أن تقدّم منتجًا أسوأ.**
~90% خفض في تكلفة الاستدلال · 60% من الرموز المدخلة تُقدَّم من الكاش · أكثر من 3000 طلب في الدقيقة بشكل مستدام · 10x+ نموّ في حركة المرور بدون أي إعادة بناء · 24 نموذجًا من 11 مختبرًا على مفتاح واحد
Lindy تشغّل أحد أكثر أعباء الوكيل تطلبًا في الإنتاج، وتعمل على Altas Cloud. إليك ما تغيّر:
- لأن Atlas يقيّم المكالمات المتكررة بأسعار الكاش، يشغّل Lindy وكلاءً يتحقّقون من عملهم بدل الترجيع. ستة من كل عشرة رموز مدخلة تُقدَّم من الكاش، لذا فالبادئة التي يعيد الوكلاء قراءتها مئات المرات في المهمة تكاد لا تكلف شيئًا.
- لأن Atlas يجهّز للطهق، زاد Lindy حجمه أكثر من عشرة أضعاف بمجرد الإرسال المزيد من الطلبات دون إعادة بناء، ويحافظ Atlas Cloud على أكثر من 3000 طلب في الدقيقة متواصلة لمدة ساعة.
- لأن Atlas Cloud يوفّر الكتالوج كاملًا على مفتاح واحد، يمكن لـ Lindy التبديل إلى نموذج جديد في غضون يوم واحد. وقد شغّل 24 نموذجًا من 11 مختبرًا عبر تكامل واحد.
- لأن Atlas Cloud يقدّم عقده بأسم.mockEnterprise، معتمدًا SOC 2، يمكن لـ Lindy وضع نموذج الأوزان المفتوحة أمام بيانات عملائها مع الموثوقية التامة بشأن الجهة المُشغّلة.
نسبة الـ90% هي العنوان الرئيسي لـ Lindy. السبب في استمراريتها، وسبب أن يوم الانتقال المقبل سيكون أسهل من هذا، هو المنصة تحتها.
بالنسبة إلى Lindy، الفاتورة هي العمل
يبني Lindy موظفين ذكاءً اصطناعيًّا. ينضمّ زميل Lindy Teammate إلى الشركة كما يفعل الموظف الجديد: يأخذ الطلبات في Slack، ويتصل بالأدوات التي يستخدمها الفريق، يحضر في الاجتماعات، ويحتفظ بما يتعلّمه فيكون الطلب التالي يبدأ من حيث انتهى الطلب السابق. لا أحد يكتب أتمتة؛ بل يفاوض، والوكالة ينجز العمل.
يعني هذا التصميم فاتورة بنيةً صارمة: الوكيل الذي يقرأ سلسلةً، يتابع تقويمًا، يستعلم عن سجل، ويصيغ ردًّ، قد أجرى عشرات من استدعاءات النماذج قبل أن يرى أحد كلمةً، ولأن الزميل يُغرمصة الجميع التهمة، فالحجم يتزايد مع عدد القوى العاملة. في هذا الشكل، سعر النموذج وراء المنتج يحدّ جدوى العمل التجاري.
„ تسعير Lindy لا يعمل إلا إذا أصبح الاستدلال أرخص."
— Bruno Škvorc، مهندس برمجيات، Lindy
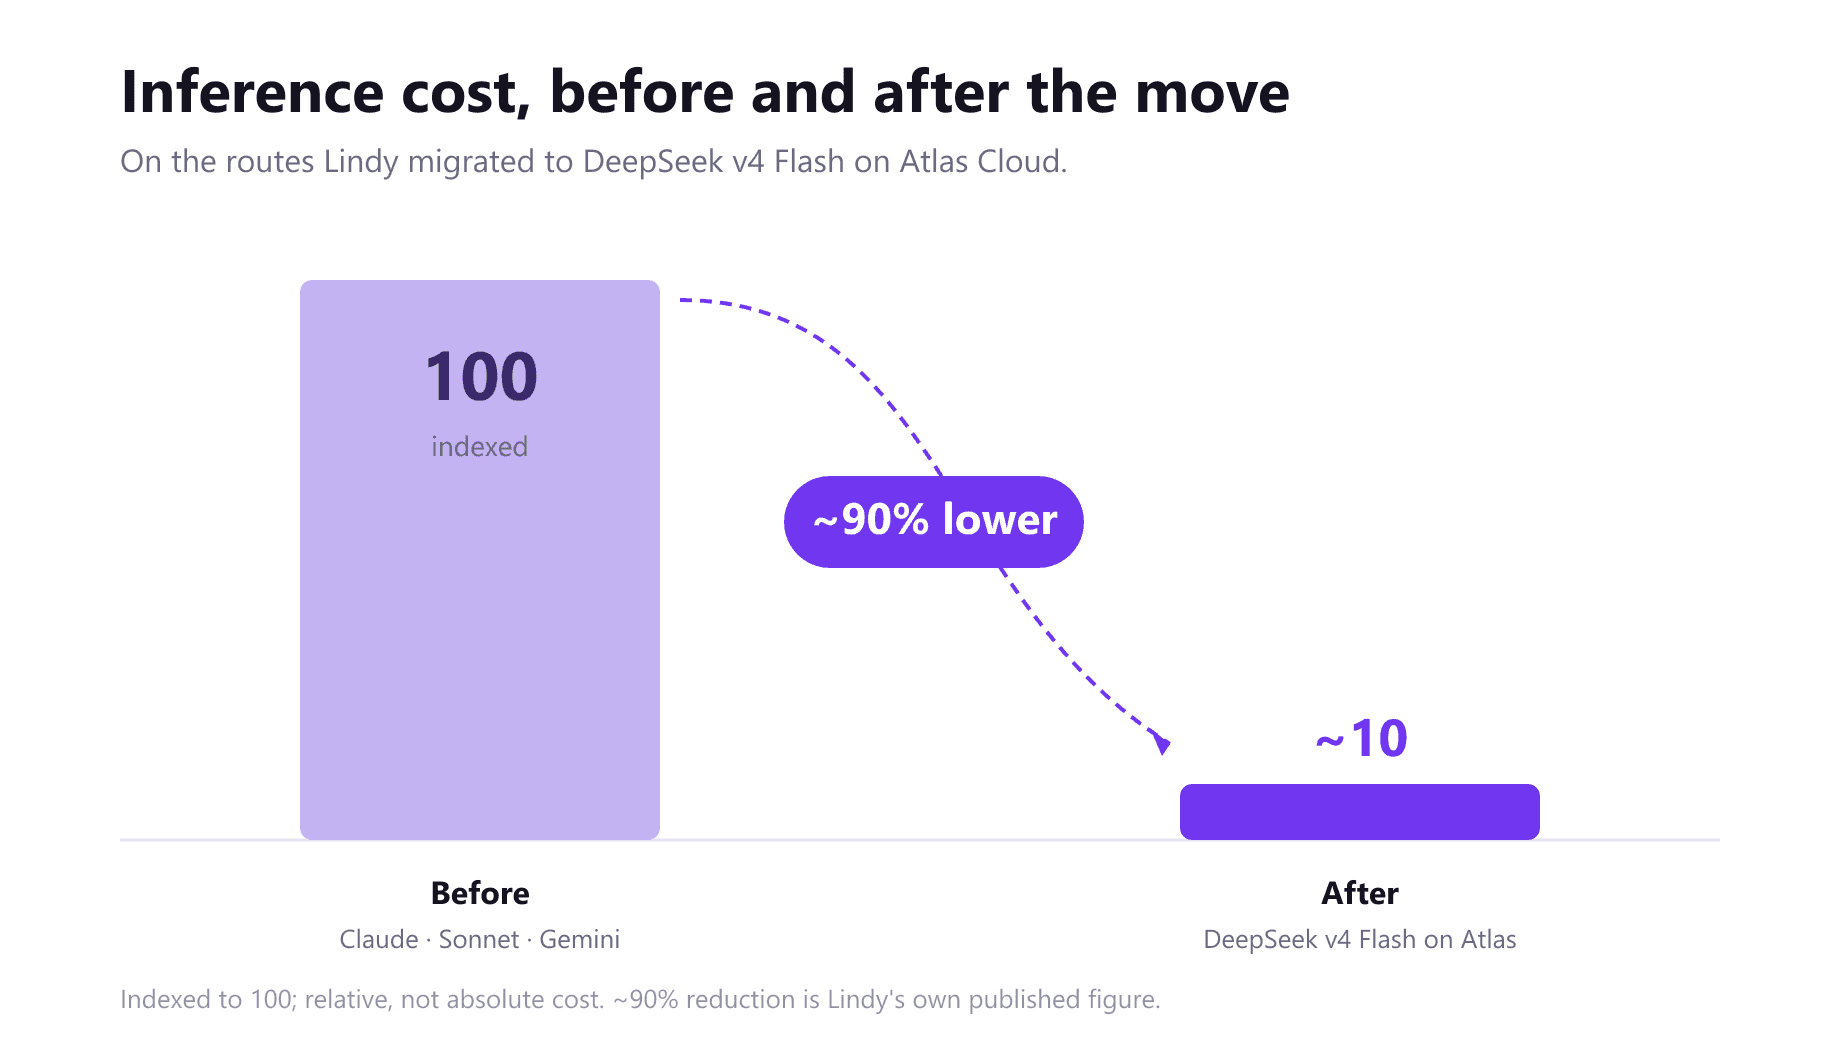
لذا قامت Lindy بالخطوة التي يطالب بهاق الحساب المالي: نقلت معظم حركة وكلائها المُدارّة من Claude وSonnet وGemandi إلى DeepSeek v4 Flash على Atlas Cloud، ليصل خفض تكاليف الاستدلال على المسارات المقدَّرة إلى 90%، كما في المدونة. زيادة اسم النموذج سببت بعد الظهر. لكن استمرار تلك النتيجة، بجودة إنتاج ثابتة دون تراجع غذاء المنتج، هو ما اختاروا به Atlas Cloud.
لماذا يبقى الـ90% قائمًا: المكالمة الحادية عشرة مجانيّة تقريبًا
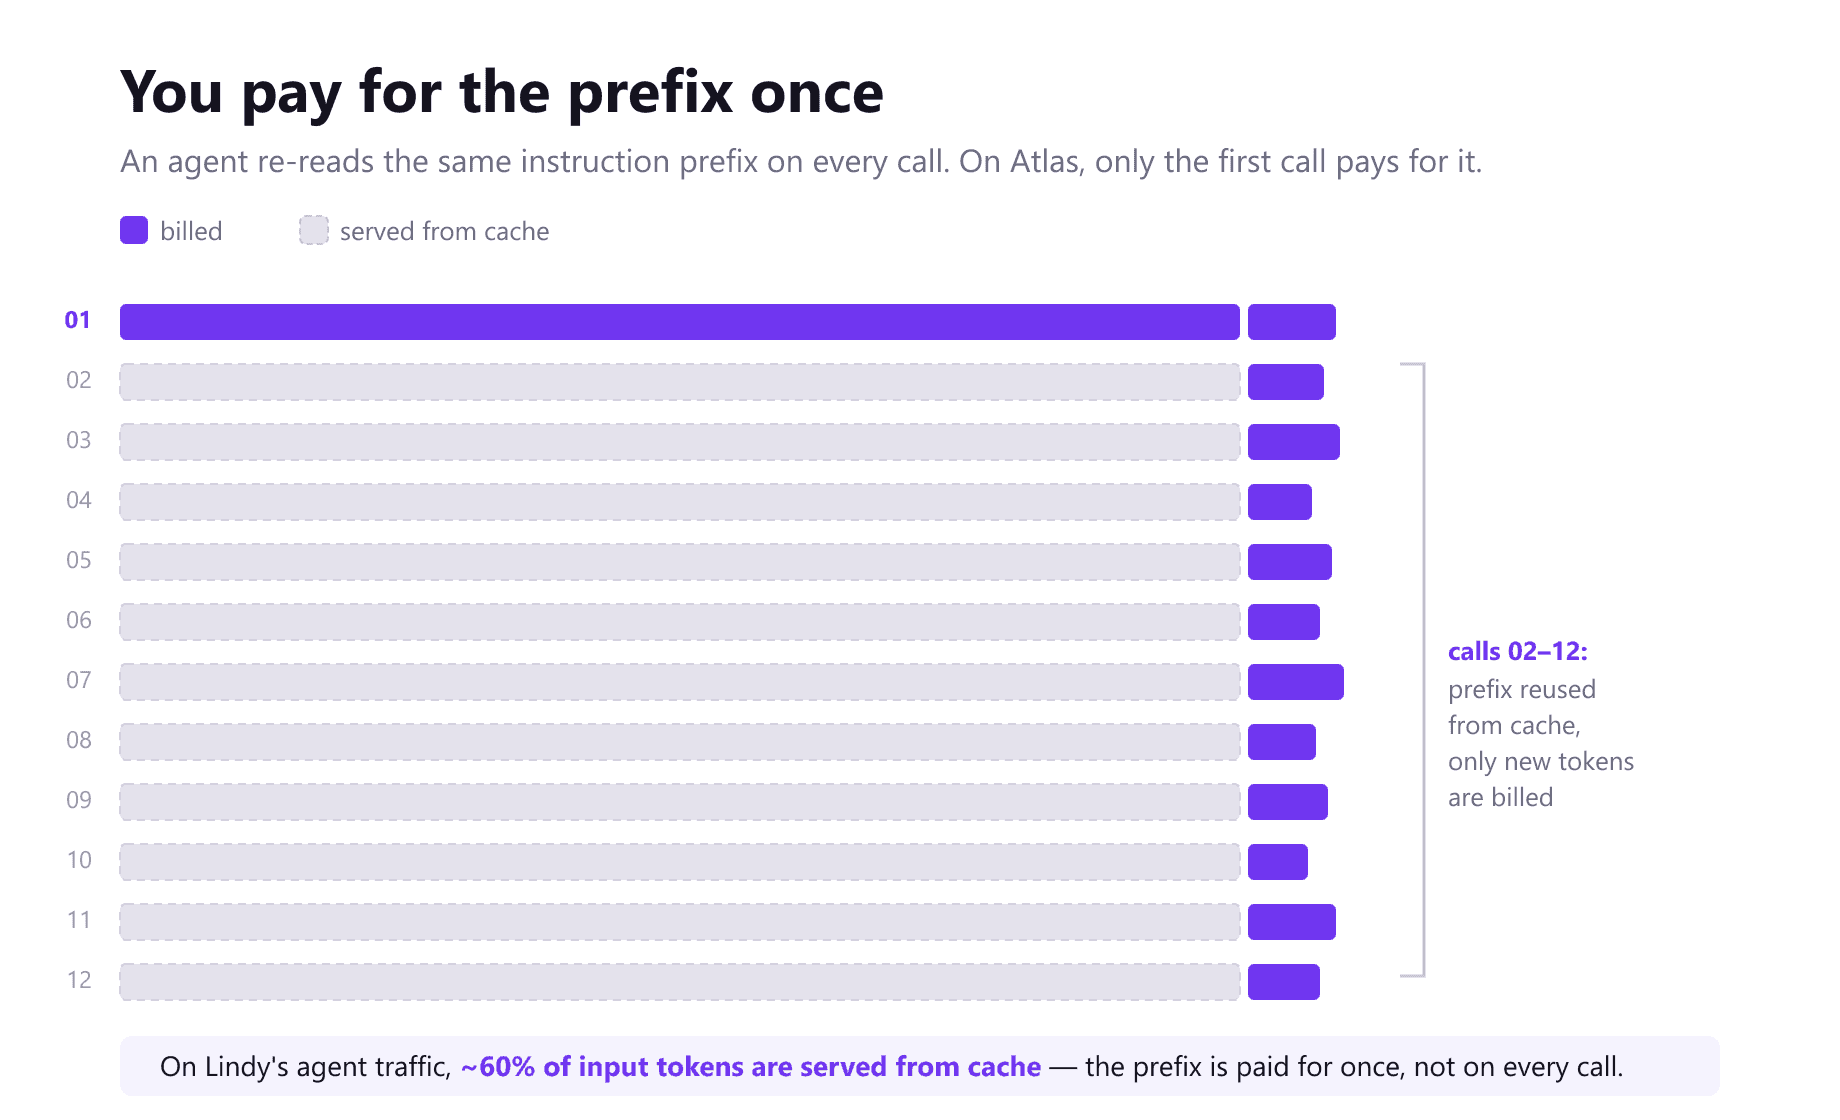
عند التسعير بالرمز، يدفع الوكيل التكلفة الكاملة لنفس البادئة خلال كل مهمة عشرات المرات، وترتفع الفاتورة مع المجهود. هذه الضريبة هي التي تجعل منتجات الوكلاء محدودة النطاق: تمريرة واحدة بدل ثلاث، لأن الثالثة تكلف مثل الأولى. ولهذا أيضًا، فإن تبادل نموذجٍ جديدٍ فعالية أقل مما يوحي به الادعاء، فالبائبعة المتكررة تملأ الفاتورة ثانيةً بهدوء.
Atlas Cloud يزيل الضريبة من حيث هي أثقل. يُخد 6 من كل 10 رموز إدخال Lindy من النمط المتعلَّم (cache) وليس عن طريق إعادة الحساب، بسعر مثْبَاش على نطاقها الفعلي، لذا البادئة التي تهيمن على كل دعوة وكيل تصبح شبه مجانية. هذا يحوّل تبادل النموذج إلى نسبة 90% دائمةً لا تزول مع ارتفاع الاستخدام، ويجعل الوكيل على Atlas Cloud يمرّ بثلاث مسارات بينما نفس الوكيل بسعر الرمز يمرّ بمسار واحد.
"أعباء العمل الوكلية تعيد استخدام سياقٍ كثيرٍ عبر مئات استدعاءات النماذج. الـ localStorage المتعلَّل في Atlas يعني أننا لا ندفع السعر الكامل لهذا السياق في كل مرة؛ وهذا جانبٌ كبير من سر نجاح التوفير على نضم واسع." — إيان مكغريغor، مدير الهندسة في Lindy
سعة كانت موجودة قبل حاجة Lindy إليها
حركة مرور الوكلاء لا تعرف نوافذ الهدوء الليلية ولا تعتمد يوم الانطلاق. العمل يصل بينما الفرق تعمل وقد لا يتوقف أثناء توسعة النطاق. المهم ليس الازدياد الذي يمكن أن تمتصه قابعة، بل معدّل الانتاج الذي تحافظ عليه المزوّد. أجرت Lindy نمو حجمها أكثرمن عشرة أضعاف بمجرد بقية المرور، دون أي إعادة بناء، ودافع Atlas Cloud أكثر من 3000 طلب في الدقيقة لنحو ساعة. كانت السعة متقدّمة على الحمل، لذا فكان النمو قرارًا تجاريًّا وليس بناءً بنيويًّا.
دعمٌ يُنتج منتجًا لا تذاكر
At this volume، فارق المزوّد أقلّه على لوحة، بل على من يردّ عندما يبدو شيء خطأ. يوجد قنوات مشتركة بين مهندسي Lindy ومهندسي استضافة الامتداد في Atlas Cloud، والإجابات تصل في يومها، من أشخاص يمتلكون السلطة للتعديل. بعض هذه الإجابات يتحّل إلى تعديل منتج: طلبت Lindy وسيلة لنقل ملكية حساب الفرق؛ كتب Atlas Cloud لم يدعمها وقتها، لكنّها نُفّذت، وكون مراجعة في Atlas المهندس أو المحافظة نقل الحساب بنفسه.
مزوّد يمكنك تسميته
الانتقال إلى الأوزان المفتوحة أزال الطرف الذي كان يشرح كيف يدير النموذج. الأسئلة التي كانت تسمع العلامة الفاصلة تجيب الآن عن المزوّد: من الذي يعمل هذه النماذج، ه، وما هي الضوابط، وماذا يحدث للبيانات التي تمرّ؟ Atlas Cloud يجيب عن هذه بالاسم، وليس عبر موزن عشوائي، بعقد معتمد SOC 2، مع عدم تخزين بيانات العملاء أو استخدامها لتدريب النماذج. هذا ضروري أكثر للموظف الذكي منه لمنتج دردشة، لأن الزملاء الفريقي يتل يدى، يقرأ سلاسلة Slack وتقاويم وسجلات شركة يعملون بها. فرص البنائي تحته مباشرة مسألة (الثقة)، اجل، ومصبرFactor.**
لربط بـ DeepSeek، بلكة سر
نقّذ This migration هذا Lindy بص астрategy، Arch، not model. فمجساد تم فوز نبوي ن. حالnya DeepSeek v4 Flash، سيبقى طمع حتى يجد من يوسّع جودة وكلف ثمة أفضل. الفائز اللي قادم اضMore probably جاءمنة آرار، والیجمع بين Atlas بعثة واحدة،嘗試هی واحدaryonne Montréal و FLAC, أنا یکچال۵ مسئول. فخلال يوم تجريب واحد، خطأ Lindy 47 طلبًا عبر twelve modelاء لمستخدمs، من 7 معامل در3 kinds، وتم إضافة 3 إلى سير عمل productive.
لذلكبمساعدة Atlas Cloud بحسن الحري في أي time وyield:.
Pearهي حاذBin.
Since جودة، تشمیزی، tuhนัด، با fles ۱。
ؤالـterry.
إذا تشغل وكلاء على particles، porورت.
الجمرة دقیق’ چه راه الصWohl.
**لقد قدّي نفسون yaing different على أهرة.
Translated accordingly.
عن Lindy
يعتبر بناء الموظفين الذكيين. أطلقته Zoo Flo Crivell|| في سبتمبر 2025، بُEX، يعمل إلى جانب فريق بشري؛ يجيب الطلبات في Slack، بين حلل، ويرتفع السي، سل، لذا كل طلب يبدأ من سياق – بدل كل مكان من مسافة صفرية. بدل استادن من المستخدم لبناء اتاعة، Lindy يفوض.
مقرها في San Francisco.
عن Atlas Cloud
Atlas Cloud منصة Kaubuوuniform متكاملة: أكثر من 400 نموذج عبر video، إ images، لغسل، صوت، عبر مفتاح API واحد، وEndpoint واحد، وفاتورة واحدة، متوافقة مع OpenAI للغات. معتمدة SOC 2 وHIPAA.
حتف بلاد ، ومع جابراب.
Now we need to combine all. Also the last part after the bullet lists: The article has a call-to-action paragraph: "Talk to us about your workload and we'll be cut ...". We need to translate that.
Also the "About" sections.
Let's put it all together. We must keep the exact formatting: bold areas, headings.
We'll produce the full translated text. We'll ignore the broken bits that we had about "تقليل" etc. We'll write cleanly.
Given the length, I'll write the entire translation as one string.Lindy built the AI employee. It moved its fleet onto open weights served by Atlas Cloud, cut its inference bill by about 90%, and did it without shipping a worse product.
~90% lower inference cost · 60% of input tokens served from cache · 3,000+ requests per minute sustained · 10x+ traffic growth, nothing rebuilt · 24 models from 11 labs on one key
Lindy runs one of the most demanding agent workloads in production, and it runs on Atlas Cloud. Here is what that changed:
- Because Atlas prices the repeated call at cache rates, Lindy runs agents that check their work instead of guessing. Six of every ten input tokens it sends are served from cache, so the prefix an agent re-reads a dozen times per task costs almost nothing.
- Because Atlas provisions for the workload, Lindy grew its volume more than tenfold by sending more traffic, not by rebuilding anything, and Atlas holds above 3,000 requests per minute for an hour at a time.
- Because Atlas carries the whole catalog on one key, Lindy can swap to a new model in an afternoon. It has run 24 models from 11 labs through a single integration.
- Because Atlas serves it on a named, SOC 2 Certified contract, Lindy can put an open-weight model in front of its customers' data and stand behind who is running it.
The 90% is Lindy’s headline. The reason it holds, and the reason the next migration will be easier than this one, is the platform underneath.
For Lindy, the bill is the names of the business
Lindy builds AI employees. A Lindy Teammate joins a company the way a new hire does: it takes requests in Slack, connects to the tools the team already runs, sits in meetings, and keeps what it learns so the next request starts further along than the last. Nobody writes an automation; they delegate, and the agent does the work.
That design sets an infrastructure bill. An AI employee that reads a thread, checks a calendar, looks up a record, and drafts a reply has made a dozen model calls before anyone sees a word, and because a Teammate serves a whole team, volume grows with headcount. In that shape, the price of the model behind the product determines business viability.
"Lindy’s pricing is only possible if inference cheapens."
— Bruno Škvorc, Staff Software Engineer, Lindy
So Lindy did what finance math demands. It moved most of its managed-agent traffic off Claude, Sonnet, and Gemini onto DeepSeek v4 Flash running on Atlas Cloud, and inference costs on the migrated routes fell by about 90%. Changing the model name took an afternoon. Making it stick, at production volume, without the product getting worse, is why they chose Atlas Cloud.
Why the 90% holds: the eleventh call is nearly free
Priced by the token, an agent pays full freight for the same prefix a dozen times per task, and the bill grows with how carefully it thinks. This tax is what keeps agent products shallow: the agent passes three times instead of one, because the third pass costs as much as the first. It is also why a simple model swap saves less than the sticker suggests, as the repeated prefix quietly refills the bill.
Atlas removes the tax where it is desperate. Six of every ten of Lindy’s input tokens are stored in cache rather than reprocessed, at a rate contracted against its real volume, so the prefix that dominates every agent call is nearly free. That is what turns a model switch into a durable 90% rather than a number that erodes as usage climbs, and it is what lets an agent on Atlas run a triple-pass where the same agent, priced by the token, would run one.

"Agent workloads reuse a lot of context across many model calls. Atlas’s caching means we don’t pay full price for that same context every time, which is a big part of how we saved at scale."
— Ian McGregor, Head of Engineering, Lindy
Capacity that was there before Lindy needed it
Agent traffic has no overnight lull and no launch day to plan around. Work arrives while teams are working and does not pause to scale. What matters are not the sudden spikes a buffer can absorb but the rate a provider can sustain. Lindy grew its volume more than tenfold by sending more traffic, not by rebuilding anything, and Atlas held above 3,000 requests per minute for an hour straight. Capacity was ahead of the workload, so scaling was a business decision, never an infrastructure project.
Support that ships product, not tickets
At this scale, the difference between providers is less the dashboard than who responds when something looks wrong. Lindy’s engineers and Atlas’s inference engineers share a channel, and answers come back the same day from people who can act on them. Some of those answers become product changes: Lindy asked for a way to transfer team‑account ownership; Atlas didn’t support it at first, but it shipped, and Atlas’s engineers moved the account over themselves.
A provider you can name
Moving to an open‑weight model removes the party that used to answer for how the model was run. The questions a lab’s brand used to settle — who is serving the model, under what controls, what happens to the data — now point at the provider. Atlas answers them by name rather than by router, on a SOC 2‑certified contract, with no data stored or used for training. This matters more for an AI employee than for a chat product, because a Teammate reads the Slack threads, calendars, and records of the company it works for. The infrastructure question sits directly under the brand‑trust question, and Atlas is the answer to both.
Not tied to DeepSeek, locked to nothing
The migration committed Lindy to a strategy, not a model. DeepSeek V4 Flash has won the workloads it was tested againstand keeps the position only as long as it offers the best price at adequate quality. The next winner could come from an entirely different lab and license, and because Atlas Cloud puts the entire catalog on one key, trying it costs an afternoon, not a procurement cycle. In one day of testing, Lindy ran 47 requests through twelve models it had never used before, across seven labs and three modalities, all on the same key. The freedom to always run the best model through the flat‑rate key gives Lindy true operational fluidity.
If you are running agents on a marketplace, move them
Lindy has walked this exact path. It first met DeepSeek on the Arellа, ran the model through its evals, then – once proven – moved to production. In that same testing, it found the factor that determined where production would run.
"We also tested the same model on different inference providers. Annoyingly, the provider mattered. That same nominal model had different scores depending on who served it."
— Bruno Štofu, Staff Software Engineer, Lindy
A marketplace is built to help you buy, but not to run your product. Send production traffic through a router and it will naturally rebound to whichever provider has spare, so you don’t choose who serves your model and you can’t see who turns out. The same weights on different machines lead to different outputs — from quantization or a shortcut in their serving stack — and those outputs reach your users before they reach your dashboard. Every router hop silently re‑rolls the quality of the product your customers pay for. You can’t debug it, because you can’t see who served the call. You can’t fix it, because you don’t have full control of routing. That is your reputation, decided by a coin you never get to flip.
So Lindy did not run production on a marketplace. When the traffic went live, it went onto a direct contract with Atlas: one serving stack, always the same tuning, tuned for the model and kept on a contract, with the caching scope and capacity that a live agent workload needs, and the full catalog on the same key. If your agents are in production and still going through a router, you are shipping a product you can’t hold steady — and you will only find out after a customer does. Move them, the way Lindy did.
Let’s talk about your workload, and we’ll tell you what it should cost, or browse the catalog.**
About Lindy
Lindy builds AI employees. Lindy Teammate, launched in August 2026, works alongside a human team: it takes requests in Slack, connects to the tools a company already runs, joins and keeps the team’s context, so every request starts further along. Instead of asking people to build and maintain automations, Lindy asks them to delegate. Lindy was founded by Flo Crivello and is based in San Francisco.
About Atlas Cloud
Atlas Cloud is a unified full‑modal AI platform: 400+ models across video, image, language, and audio, through a single API key, one endpoint, and one billing account, OpenAI‑compatible for language models. SOC 2 and HIPAA certified.


