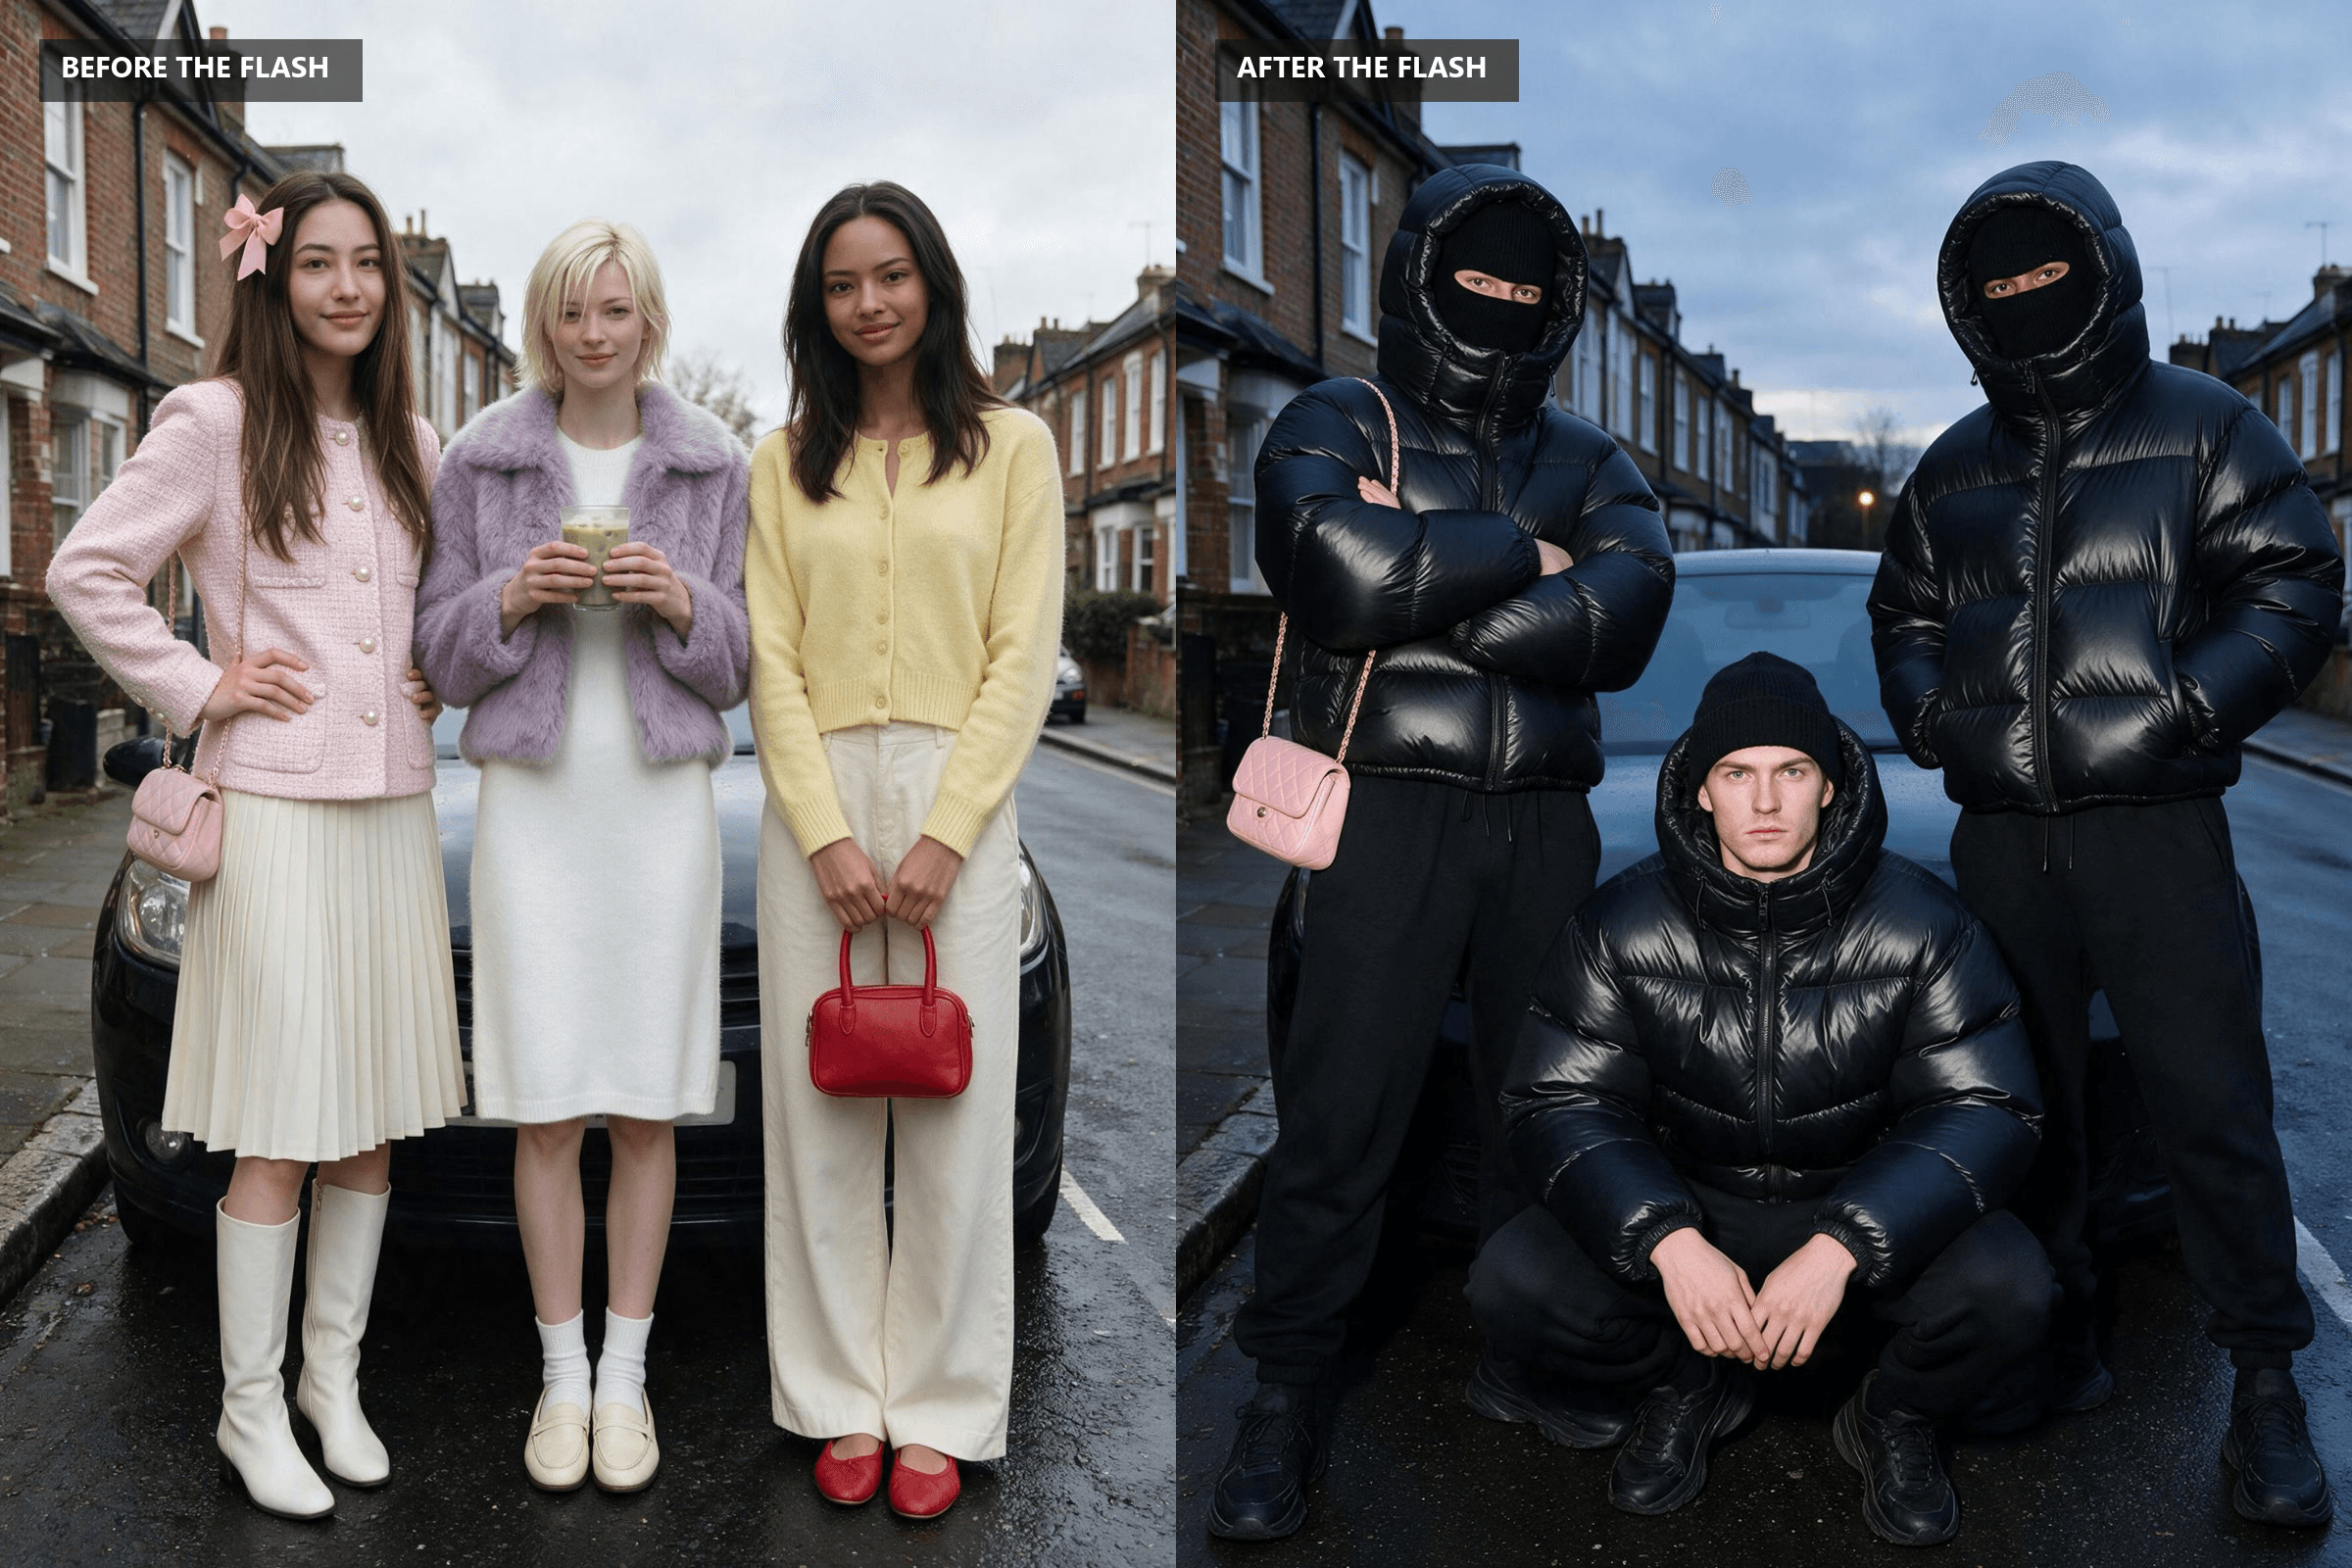
三个穿着柔和色系针织衫的朋友在一辆停着的车前摆姿势。某人的手机闪光灯亮起。白光散去后,同样的三个位置站着三个戴着黑色巴拉克拉瓦头套、身穿亮面羽绒服的小伙子,其中一人仍背着那只粉色手提包。
这就是mandem in disguise(伪装后的曼德姆)趋势,自九月底以来一直在TikTok上刷屏。以下是这个名称的由来、AI片段背后的模板,以及我们如何从一张合影中在10秒内重建闪光效果。
核心要点
- Mandem in disguise是一个TikTok闪光揭示趋势:一群女孩变成戴着黑色羽绒服的蒙面小伙子。
- 这个名称来自Skepta 2009年grime歌曲《Disguise》中的一句歌词,我们打开的大多数片段都用它做背景音乐。
- 我们找到的该声音最大的上传版本支持54.4K个视频,其标题歌词大约在3秒处结束。
- 三个CapCut AI模板支撑AI版本;群组闪光模板在11月6日有2,047次使用。
- 在Atlas Cloud视频生成器中两帧加上定时提示词即可重建整个闪光效果。
什么是Mandem in Disguise趋势?
它是一个揭示式玩笑。某样东西看起来像一回事,结果却是mandem,是那些小伙子,穿着他们的制服:黑色针织巴拉克拉瓦头套、拉链拉到下巴的黑色羽绒服、黑色运动裤。
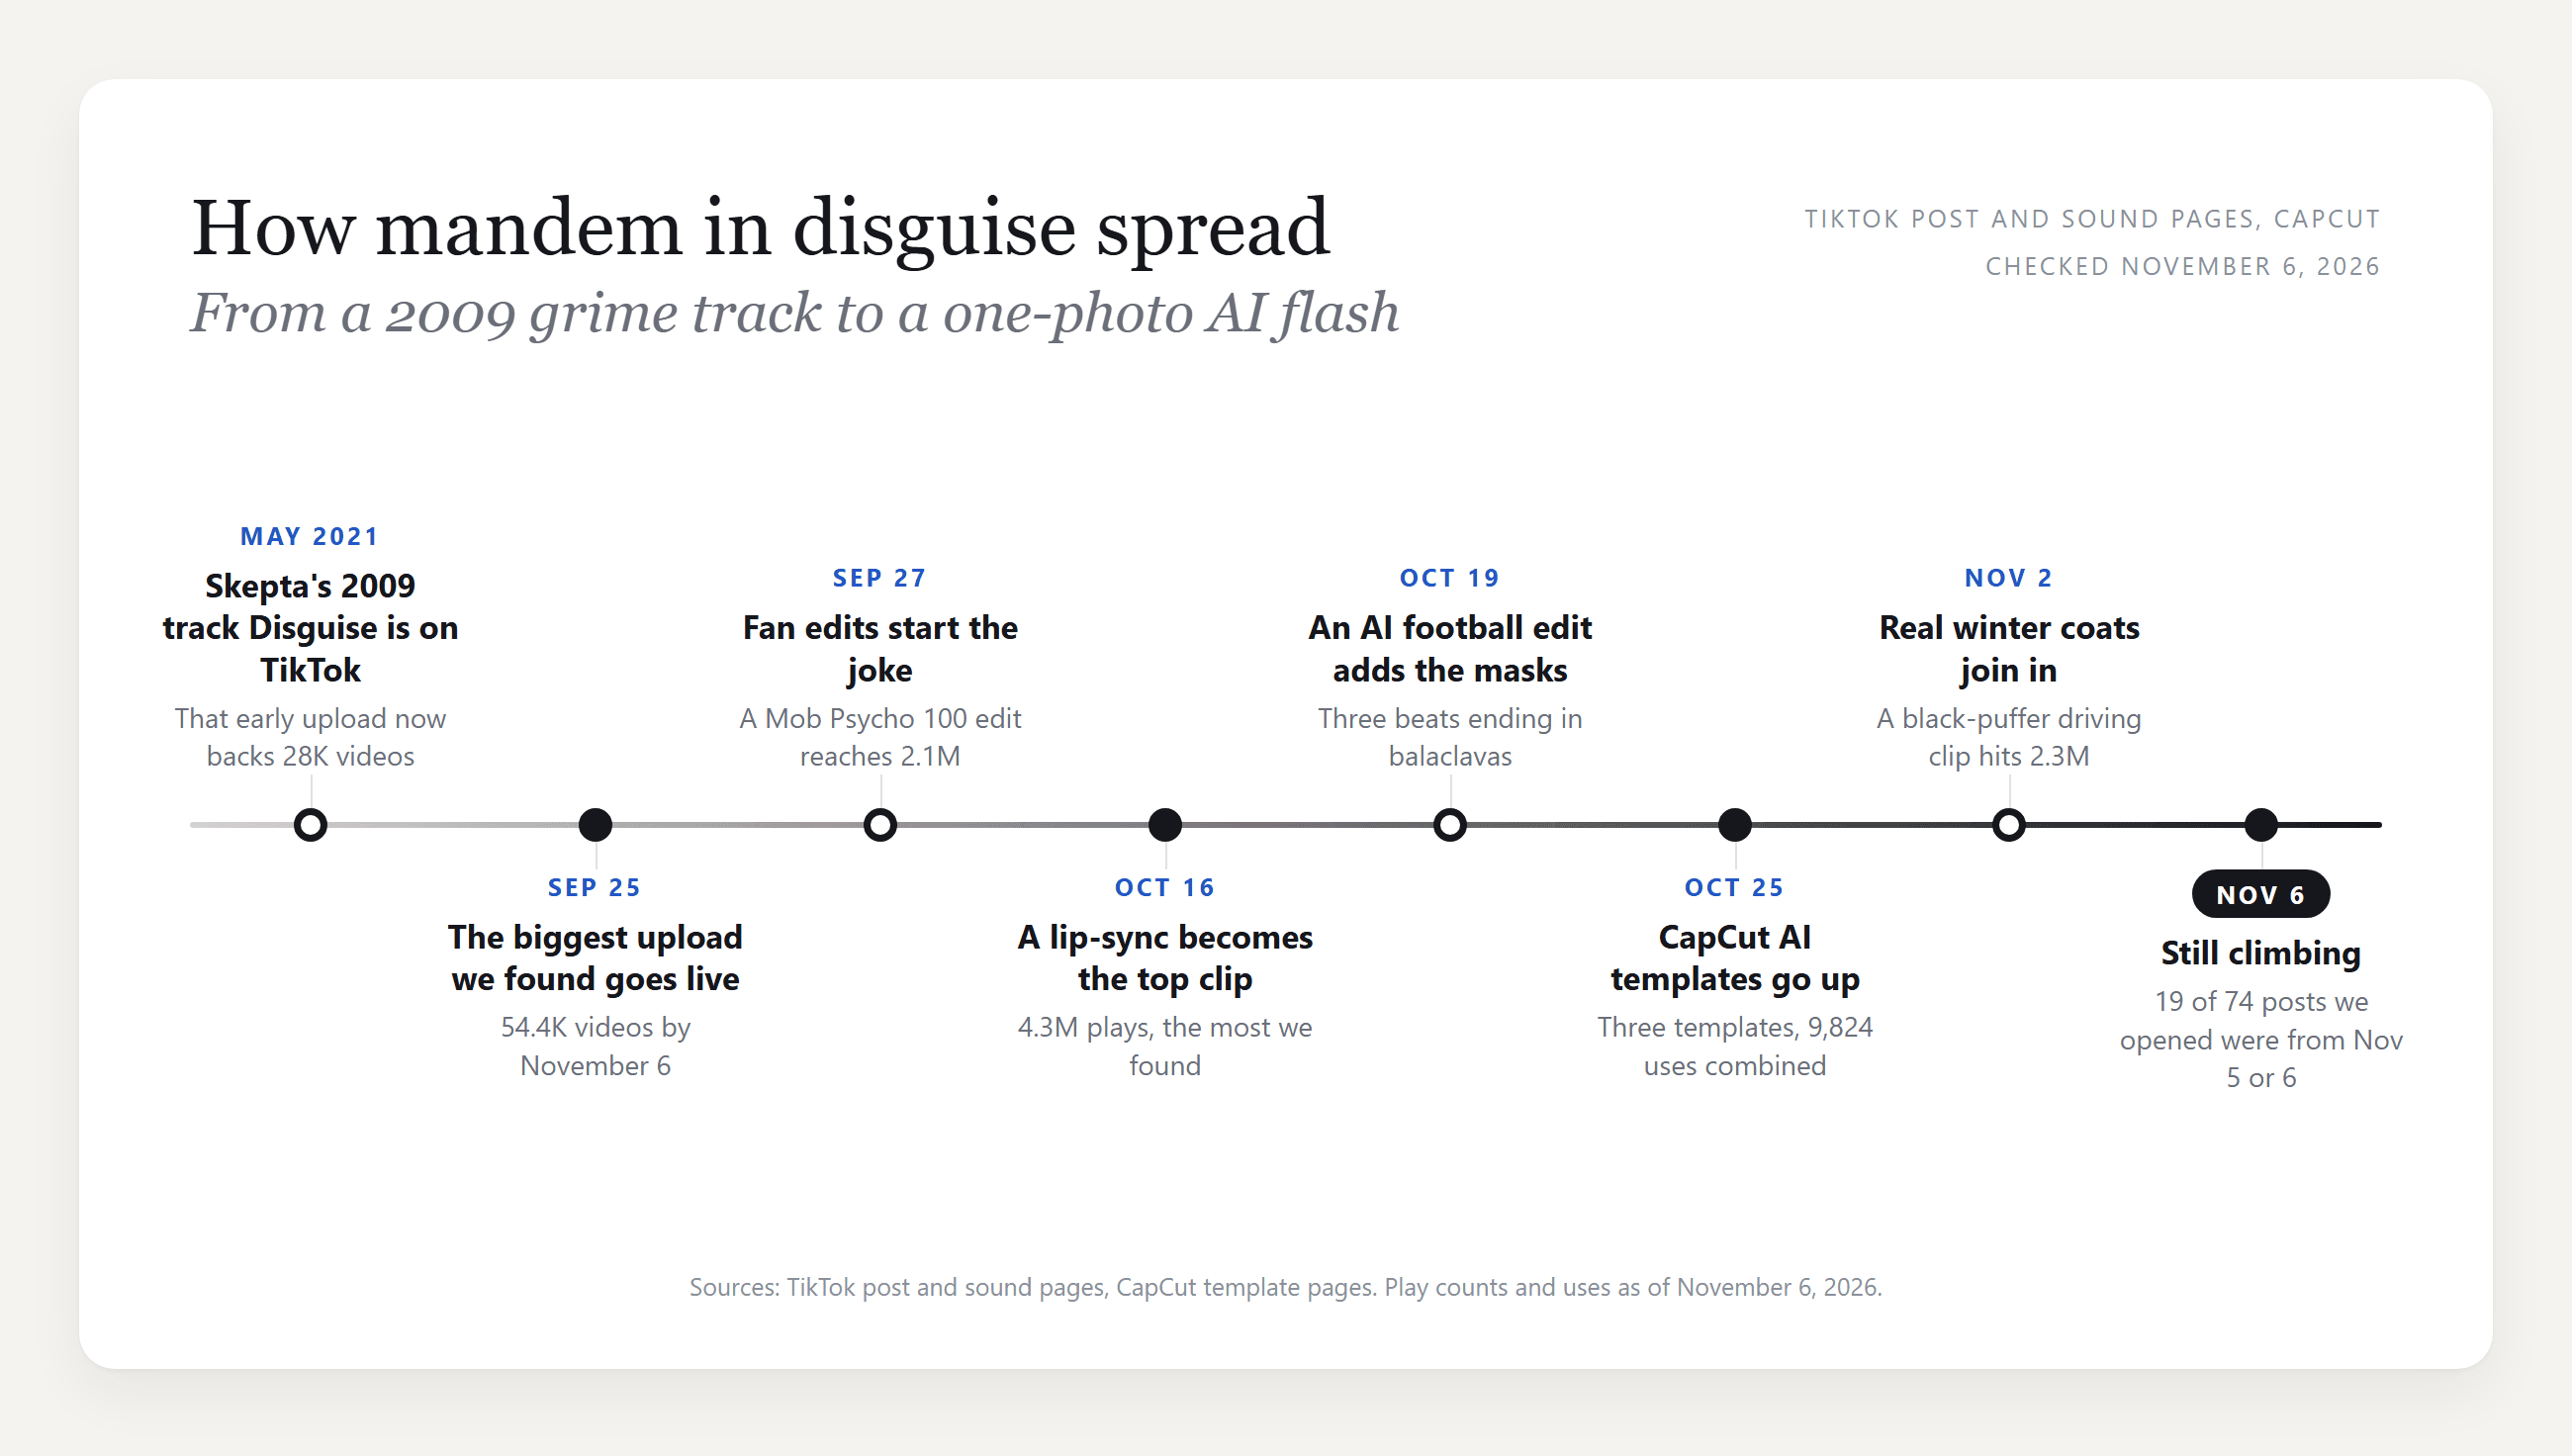
我们找到的最早的大型视觉版本是粉丝剪辑。9月27日发布的一条《灵能百分百》剪辑有210万播放量,随后动漫、F1和K-pop账号纷纷跟进。从十月下旬开始,真人加入其中,用万圣节服装、校服cosplay,以及把兜帽拉起来的黑色冬季羽绒服。
AI版本源自足球。一条剪辑于10月19日发布,展示三名曼联球员变成AI生成的女性,然后是她们本身,再然后戴着巴拉克拉瓦头套,每个词一个节拍。它有77.3万播放量,六天后CapCut AI模板出现。
Mandem in Disguise歌曲及其3秒钩子
音乐是Skepta的《Disguise》,与JME和Jammer共同录制,于2009年发行。片段使用的是标题歌词。
| 细节 | 我们在2026年11月6日发现的内容 |
|---|---|
| 我们找到的最大TikTok上传 | 一条标题为"originalljud"的原创音频,约于2026年9月25日发布,支持54.4K个视频 |
| 一个较早的上传 | 2021年5月同一首歌的原创音频,支持2.8万个视频 |
| 标题歌词结束的位置 | 在最大上传版本中约3.2秒处 |
| 这对你的剪辑意味着什么 | 从零开始播放音频,将闪光放在3秒处 |
我们通过将那个上传版本跑过语音转文字模型来给歌词计时。这句歌词开启片段,最后一个词刚好越过3秒标记,也就是我们闪光所在的位置。
如何从一张合影制作Mandem in Disguise AI视频
你需要一张明亮的分组照和同一场景的"之后"帧。不需要巴拉克拉瓦头套。
Atlas Cloud运行Seedance 2.5,它接收第一帧和最后一帧,并生成两者之间的运动。第二个槽位正是让闪光落在你想要的精确阵容上的关键。以下是我们制作的mandem in disguise AI视频:
在三秒钟里,女孩们做着细微而平常的事情:一个整理头发上的蝴蝶结,一个啜饮冰抹茶。闪光在3.3秒达到峰值,到3.7秒消失。随后街道变成冷蓝色的黄昏,左边的那个小伙子羽绒服上仍背着粉色链条包,前面蹲着的那个人低着头一秒钟,然后才抬起眼。
方法1:在Atlas Cloud视频生成器中制作闪光揭示
从"之后"帧开始。我们在图像编辑选项卡中用Seedream v5.0 Pro制作了它,对分组照进行了两轮处理。第一轮设定服装、姿势和黄昏光线:
plaintext1Edit this photo into the "after" shot of the same moment, taken from the exact same camera position with the same framing, the same street and the same car. Everyone stays in the same spot and the same size in the frame. Lighting: the street is now darker and blue-grey like early evening, and the group is lit by a harsh direct on-camera flash, with bright highlights on the glossy jackets. Each person wears a black knitted balaclava with a single narrow eye slit, the hood of an oversized glossy black puffer jacket pulled up over it and zipped to the chin, baggy black joggers and chunky black trainers. New poses: the left one stands wide with arms crossed and chin raised, the centre one squats low in front with forearms on the knees, the right one leans back on the car with both hands in the jacket pockets. Remove the drinks and the red bag; the pink chain bag stays on the left one's shoulder as the only colour in the frame. No logos, no text. Exactly three people.
第二轮,对结果进行处理,将这群人变成mandem:
plaintext1Edit this photo. Keep the framing, the light, the poses and the clothes exactly as they are: shiny quilted black puffer jackets (not hoodies) with the hoods up, black joggers and black trainers. Change only who is wearing them: three young men, each the twin brother of the person who stood in the same spot, with the same skin tone and eye colour, and clearly male builds. The centre one has his balaclava rolled up into a black beanie so his face shows. No logos, no text. Exactly three people.
然后登录,打开AI视频生成器,按步骤操作:
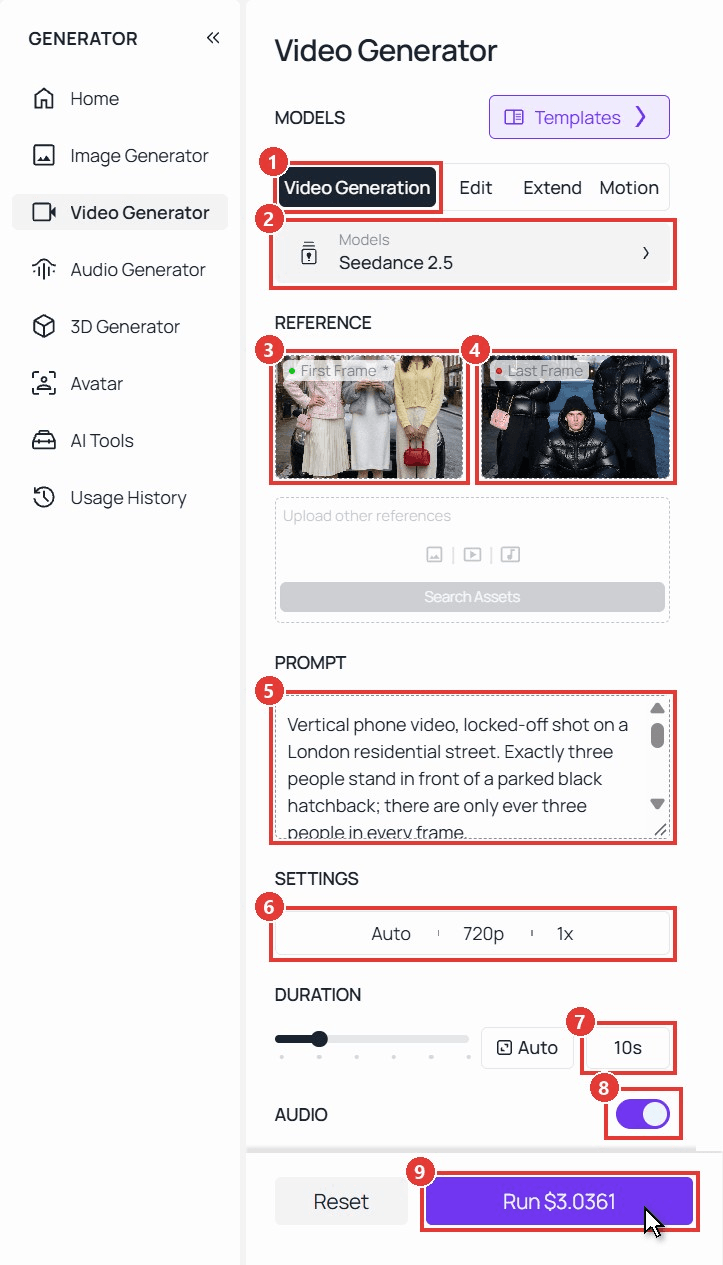
- 打开视频生成选项卡。
- 在模型下保留Seedance 2.5。
- 将分组照上传为第一帧。
- 将"之后"帧上传为最后一帧。
- 粘贴下面的提示词,前半部分用你自己的服装。
- 在设置下,选720p作测试或1080p作最终版。宽高比跟随你的照片。
- 在时长框中输入10。
- 保持音频开启。
- 点击运行。
plaintext1Vertical phone video, locked-off shot on a London residential street. Exactly three people stand in front of a parked black hatchback; there are only ever three people in every frame. 20-3s: soft overcast daylight. Three young women pose in their bright girly outfits: the left one in a pastel-pink bouclé jacket and cream pleated skirt with a pink chain bag, the centre one in a lilac faux-fur coat holding an iced matcha latte, the right one in a butter-yellow cardigan holding a small red bag. Small natural movements: the left one tucks her hair behind her ear, the centre one takes a sip, the right one sways and smiles. 3At 3s: a bright white camera flash goes off and fills the whole frame with white for about a third of a second. 43.4-10s: as the flash fades, the street is darker and blue-grey and lit by a harsh direct flash, and the three girls are gone: in their places are three young men in oversized shiny black puffer jackets with the hoods up, baggy black joggers and chunky black trainers. The left one wears a black balaclava, arms crossed, the pink chain bag still on his shoulder; the centre one squats low in front, his balaclava rolled up into a black beanie showing his pale stubbled face; the right one, also in a balaclava, leans back on the car's bonnet with his hands in his jacket pockets. Almost no movement: the centre one slowly tilts his head, the left one gives one slow nod, all three stare straight into the lens, then hold the exact final frame. 5No camera movement after the flash, no cuts, no text, no logos, no extra people. 6Sound: quiet street ambience, a sharp camera-flash pop at 3s, then a heavy bass drop and a low UK drill-style beat.
方法2:通过API发送Mandem in Disguise帧
要为每个群聊都做一个版本,或者给应用添加一个闪光按钮?API接收同样的两帧和提示词。
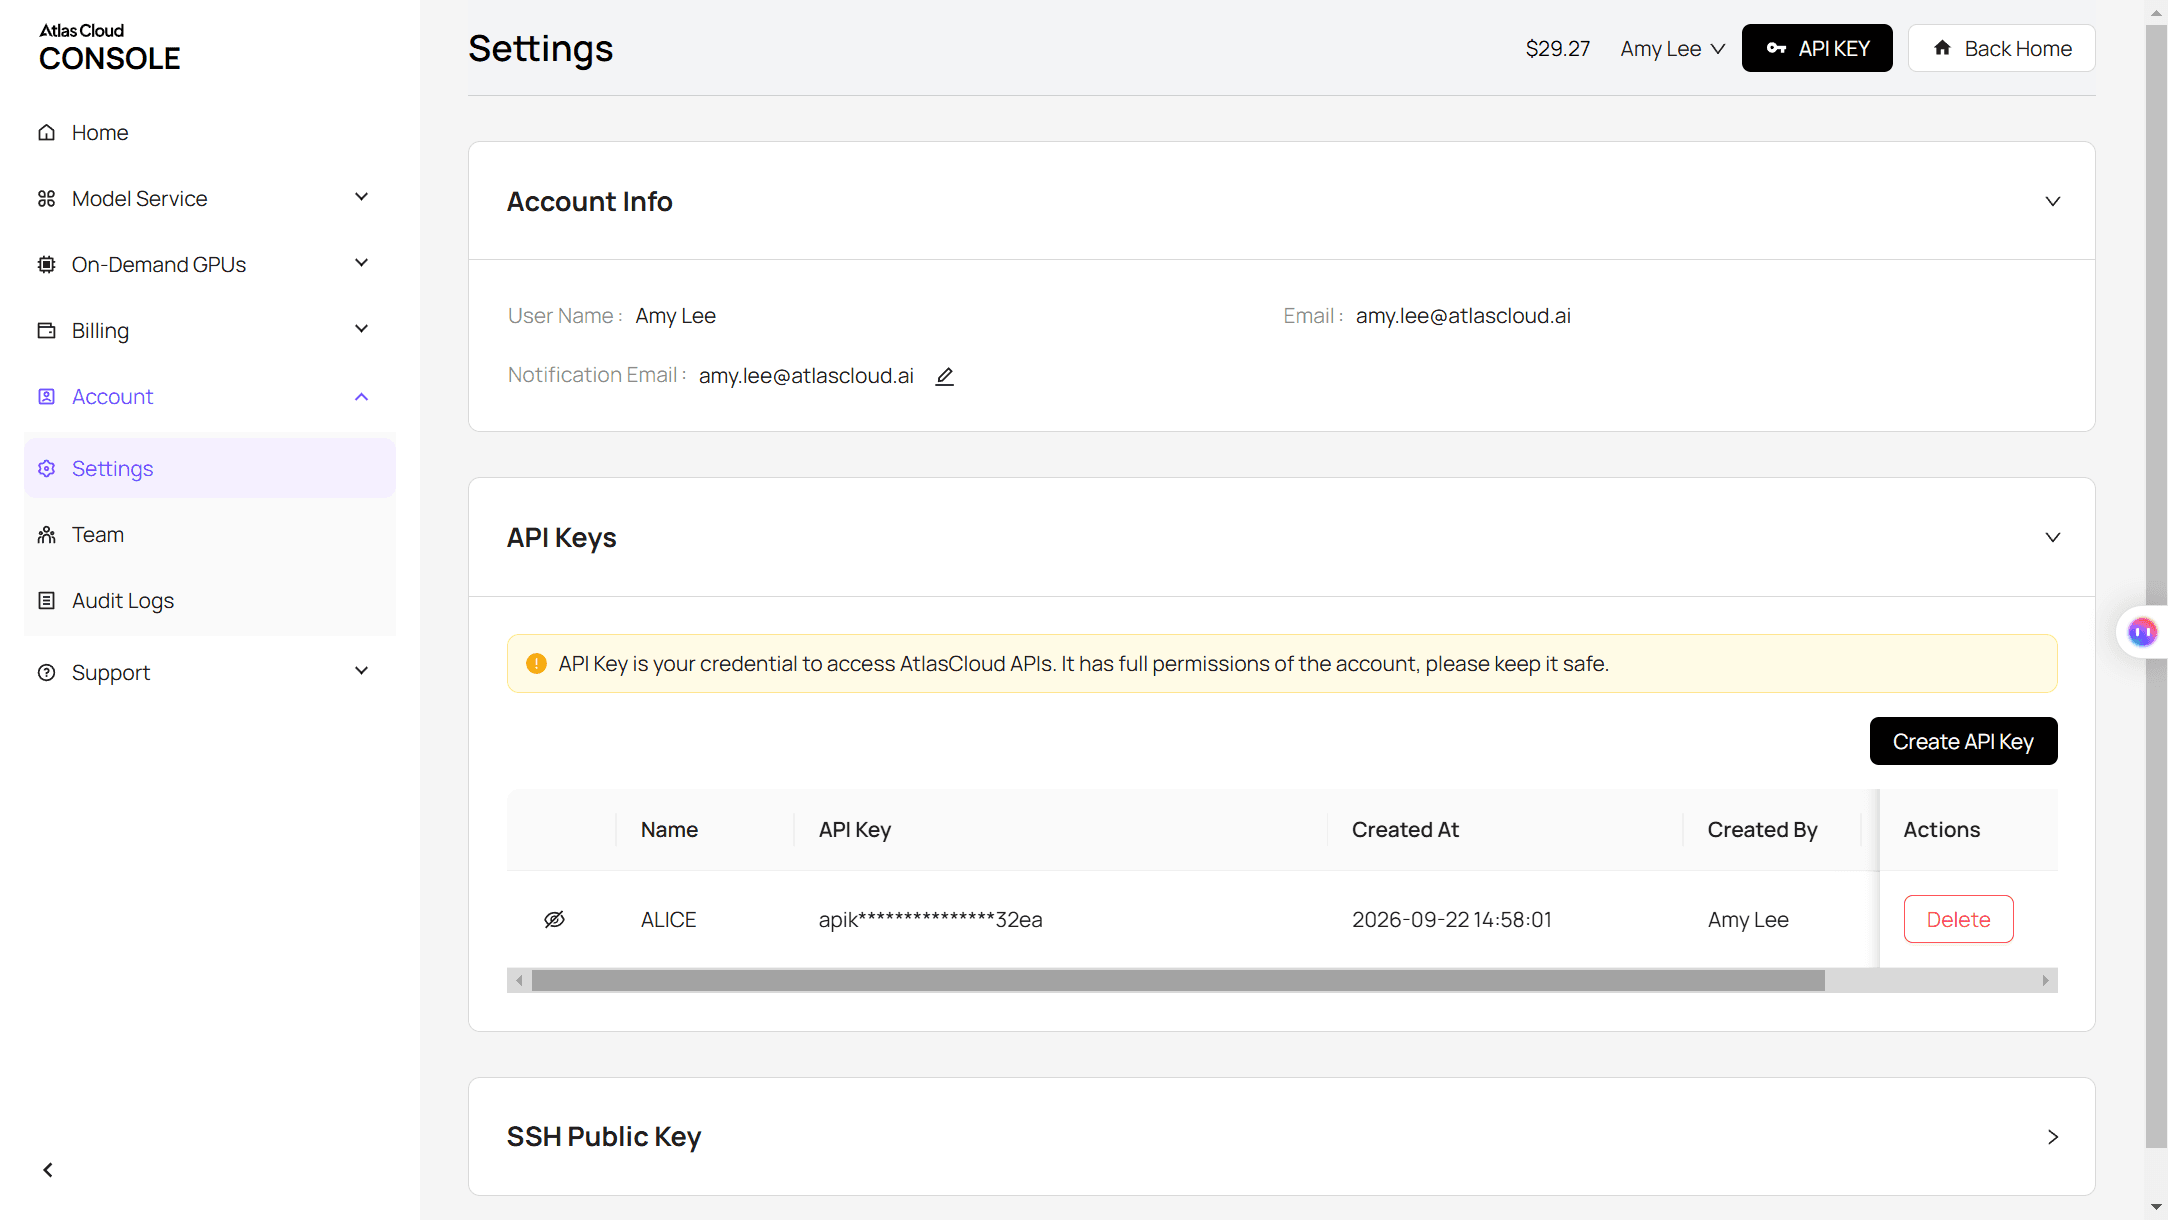
步骤1:创建API密钥。 在控制台中,打开设置并在API密钥下创建一个密钥。一个密钥适用于所有模型。
步骤2:检查请求格式。 Atlas Cloud文档涵盖身份验证和视频端点。
步骤3:发送请求并轮询。 分组照放入image,"之后"帧放入last_image:
plaintext1curl -X POST https://api.atlascloud.ai/api/v1/model/generateVideo \ 2 -H "Authorization: Bearer $ATLASCLOUD_API_KEY" \ 3 -H "Content-Type: application/json" \ 4 -d '{ 5 "model": "bytedance/seedance-2.5/image-to-video", 6 "prompt": "<paste the Method 1 video prompt here>", 7 "image": "https://your-cdn.com/group-photo.jpg", 8 "last_image": "https://your-cdn.com/after-frame.jpg", 9 "duration": 10, 10 "resolution": "720p", 11 "generate_audio": true 12 }'
轮询返回的预测ID,直到状态显示completed,然后从outputs数组中下载片段:
plaintext1curl https://api.atlascloud.ai/api/v1/model/prediction/<prediction_id> \ 2 -H "Authorization: Bearer $ATLASCLOUD_API_KEY"
端点和密钥在Atlas Cloud上的每个视频模型中保持不变。要尝试另一个,只需更改模型字符串。
各个Mandem in Disguise CapCut模板分别做什么?
我们打开了来自TikTok上mandem in disguise话题页面的74个帖子,并阅读了每个帖子附带的链接。六个链接到一个CapCut模板,其中五个是"如何做mandem in disguise"教程账号。以下是截至2026年11月6日这些模板制作的内容:
| 模板名称 | 使用次数 | 制作内容 |
|---|---|---|
| photo trend | 2,047 | 一张女孩的分组照,两次白色闪光,然后同样的阵容被戴着巴拉克拉瓦头套、穿黑色羽绒服的小伙子填满 |
| Nansen in disguise | 1,525 | 一张女性全身照,剪切到戴着巴拉克拉瓦头套、穿黑色运动服、背斜挎包的蒙面人物 |
| Ai photo | 6,252 | 一张戴着巴拉克拉瓦头套、穿黑色羽绒服和黑色运动裤的蒙面人物的AI静态图,没有视频 |
| mandem in disguise | 7 | 带歌词的彩色文字卡片,没有AI |
群组模板和足球剪辑在笑点上一致:女孩们变成小伙子回来,而不是同样的女孩戴着面具。这个转换正是我们第二轮存在的原因。74个帖子中没有使用为这一趋势制作的TikTok特效;附加的特效都是通用的,如绿幕和面部滤镜。
单人闪光揭示的Mandem in Disguise提示词
一个人也可以。我们从一张全身街拍开始:短发铂金色波波头、条纹露脐上衣、灰色宽松牛仔裤和铆钉腰带,靠在一辆深色汽车上,拿着粉色手机。
同样的工作流,这次8秒。她滑动屏幕并微笑,闪光在3.25秒达到峰值,当它褪去时,路人仍在车后走过,而一个蒙面人物在胸口高度举着粉色手机。两个提示词中,四个细节承担了大部分分量:
| 提示词细节 | 它控制的内容 |
|---|---|
| "At 3s: a bright white camera flash" | 隐藏替换,并与音频中的标题歌词对齐 |
| 闪光后的"lit by a harsh direct on-camera flash" | 更冷、更暗的观感,让后半部分读起来像一个新时刻 |
| 保留一件有色物品,粉色包或粉色手机 | 告诉观众这是同一个地方、同一群人,并博得笑声 |
| "the twin brother of the person who stood in the same spot" | 在女孩变成小伙子时防止肤色和眼睛颜色漂移 |
如果想要不带服装的性别转换,我们的性别转换滤镜指南有详细讲解。如果你喜欢戴兜帽的造型,但想要一只手遮住镜头而不是闪光,试试骷髅帽趋势。
常见问题
mandem是什么意思?
Mandem是英式俚语,指一群亲密的男性朋友。柯林斯词典将其追溯到本世纪,并溯源至"man"加上"them"的牙买加发音。在这个趋势中,"in disguise"(伪装)就是笑点:你最初看到的那群人不是你闪光后得到的那群人。
如何不用AI做mandem in disguise趋势?
从同一位置拍两个镜头:一个穿你平常的服装,一个穿黑色羽绒服、拉起兜帽,并用巴拉克拉瓦头套或围脖遮住脸。在音频的标题歌词处剪切,大约在3秒。手机闪光或一只手遮住镜头可以隐藏剪切。
TikTok上有mandem in disguise滤镜吗?
我们没有找到为这一趋势制作的滤镜。AI版本来自CapCut模板或像上面这样的视频模型,真人版本则是拍摄的。
AI视频会带有Skepta的音乐吗?
不会。开启音频后,Seedance 2.5根据提示词中的声音描述生成自己的音频;我们的要求了闪光声和低音下坠。发布时,将那条音轨静音,并在TikTok应用中从第一秒开始添加趋势音乐,这样标题歌词会在闪光击中时结束。
在Atlas Cloud上制作一个mandem in disguise AI视频要花多少钱?
一个10秒的Seedance 2.5片段,含第一帧、最后一帧和音频,720p为3.04美元,1080p为5.98美元,此为2026年11月6日所示。两者目前都在3.80美元和7.47美元标价基础上打8折。"之后"帧每张2K图像编辑增加0.072美元,所以两轮共约14美分。
结语
Mandem in disguise是三秒的铺垫和一帧的笑点。歌曲提供歌词,闪光隐藏切换,巴拉克拉瓦头套和黑色羽绒服完成其余部分。走红的模板在一个点上达成一致:女孩们必须变成小伙子回来。
如果你想要自己的版本,拍一张明亮的分组照,用两轮处理制作"之后"帧,然后给Seedance 2.5两端并在3秒处加上闪光。在后半部分保留一件粉色物品,mandem in disguise揭示就成功了。


