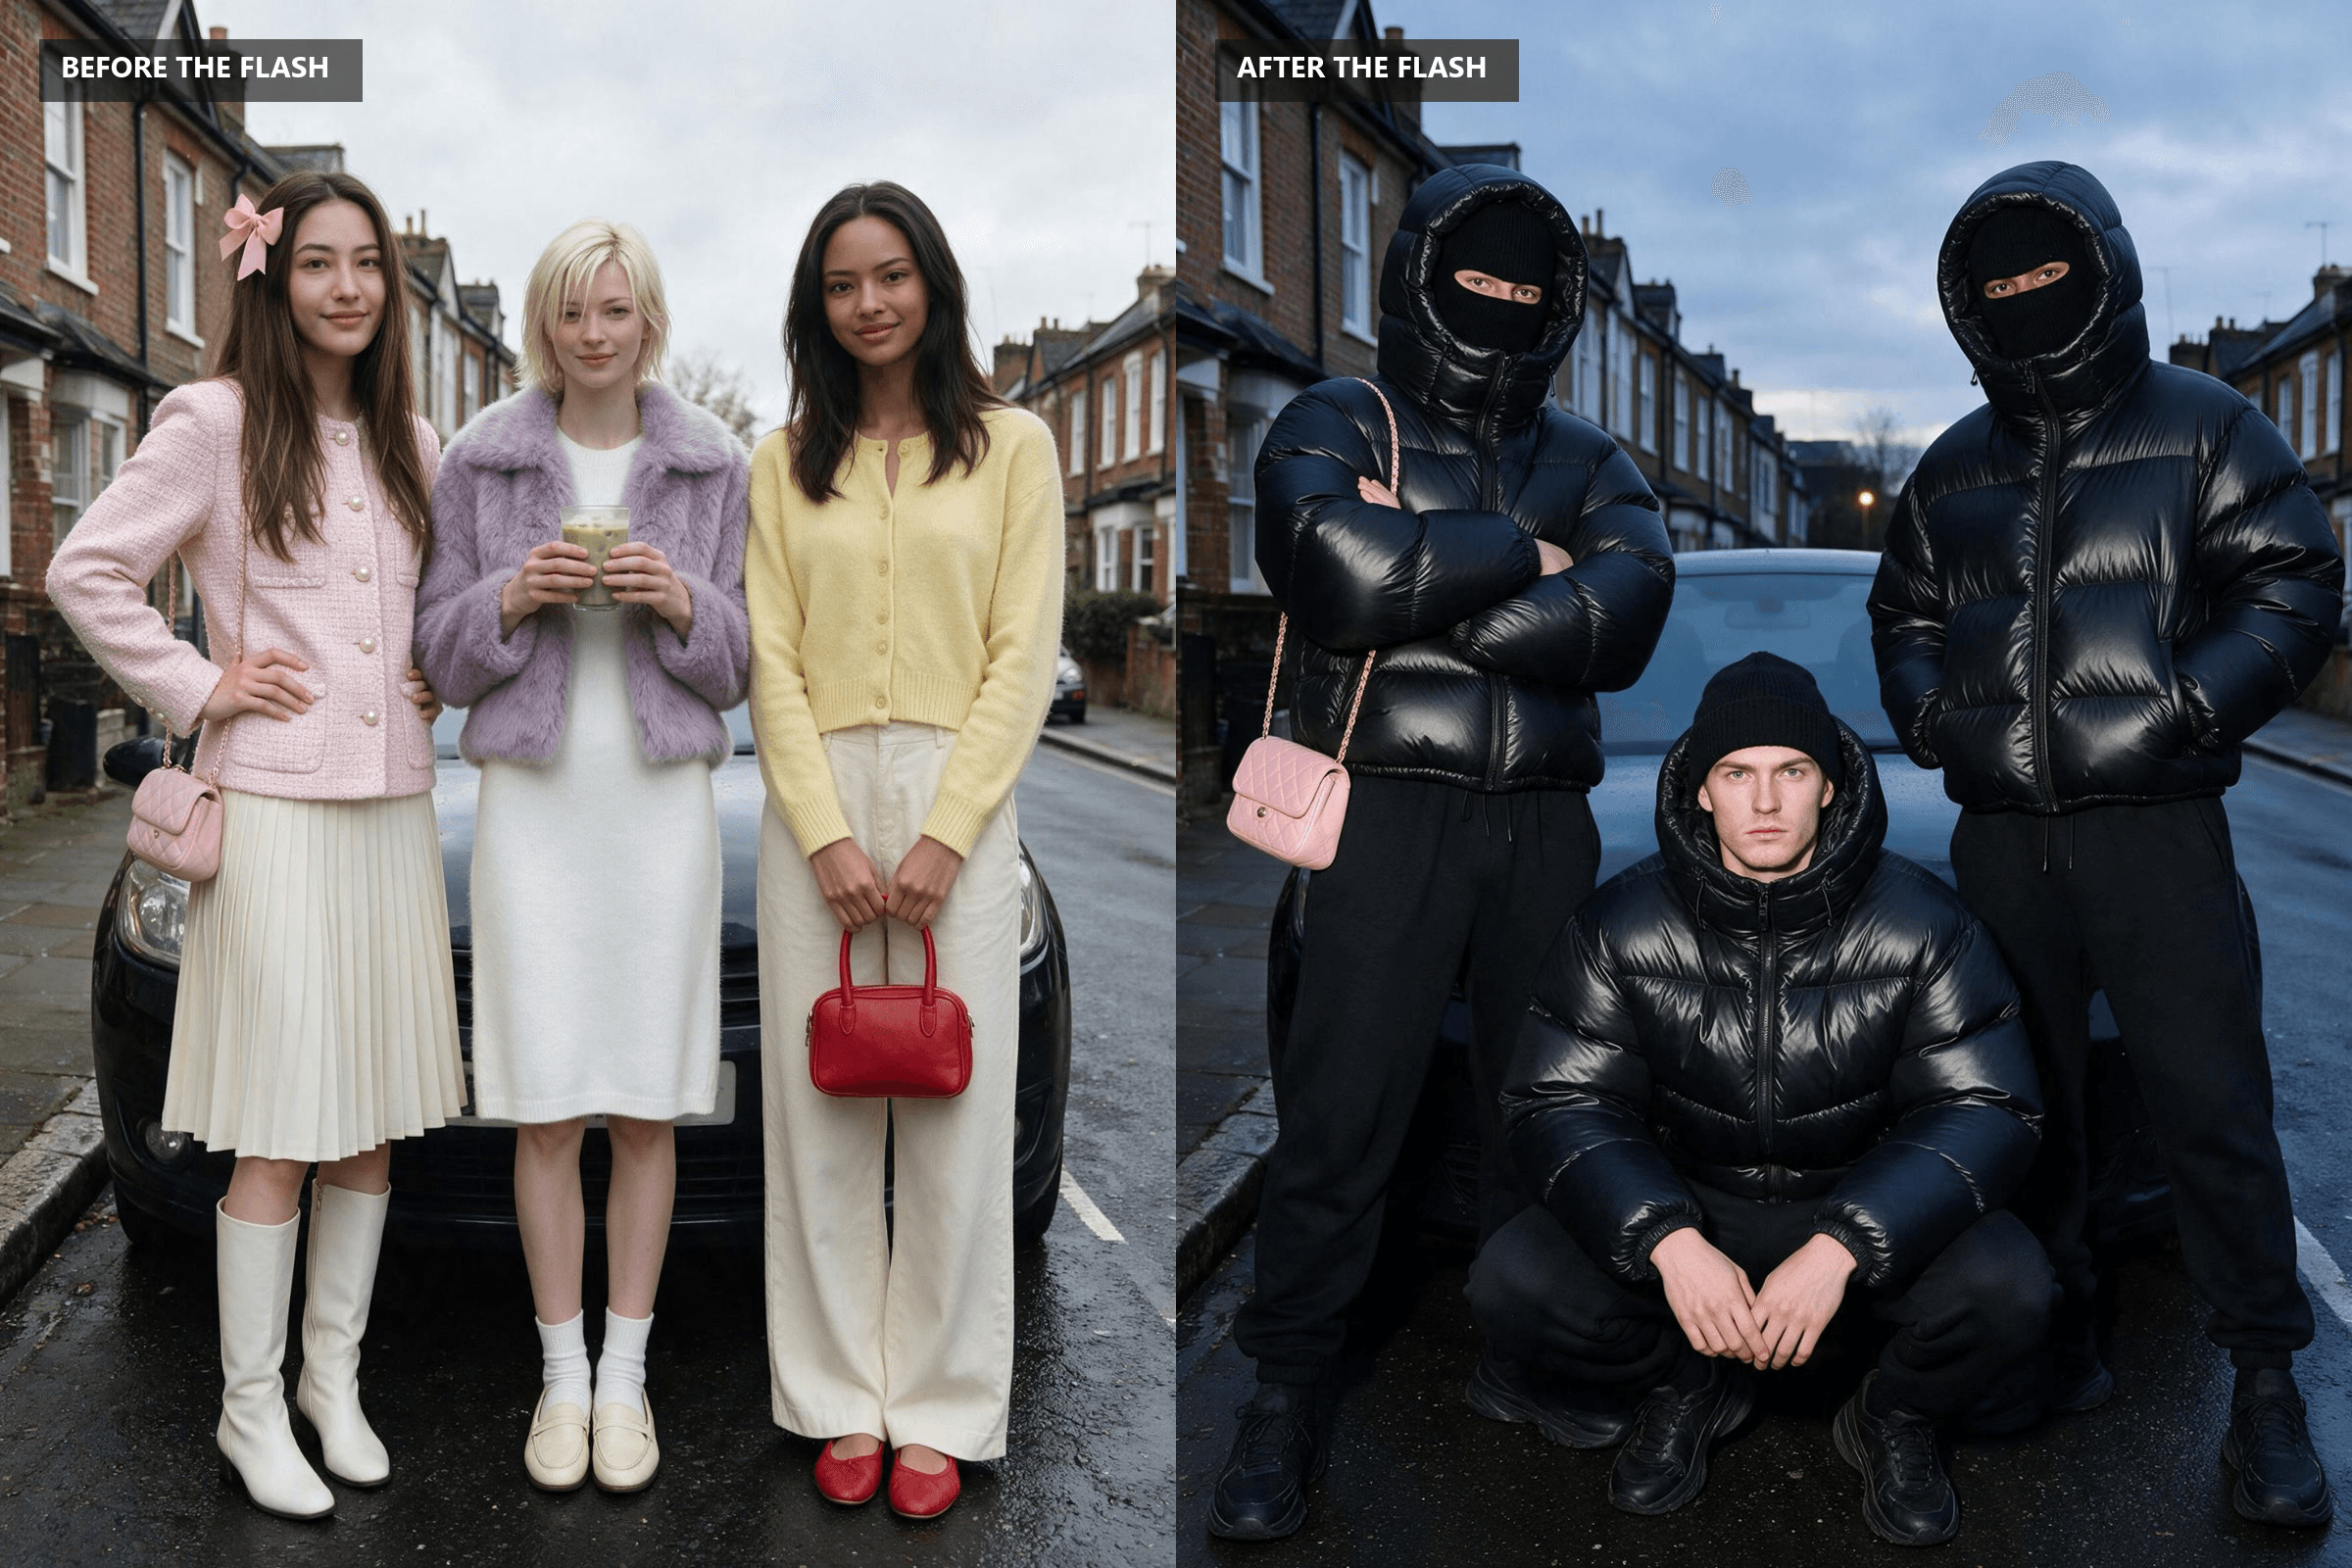
Three friends in pastel knits pose in front of a parked car. Someone's phone flash goes off. When the white clears, the same three spots hold three lads in black balaclavas and shiny puffer jackets, and one of them is still wearing the pink handbag.
That is the mandem in disguise trend, and it has been filling TikTok since late September. Here is where the name comes from, which templates sit behind the AI clips, and how we rebuilt the flash in 10 seconds from one group photo.
Key Takeaways
- Mandem in disguise is a TikTok flash reveal: a group of girls becomes masked lads in black puffers.
- The name comes from a line in Skepta's 2009 grime track Disguise, which plays under most clips we opened.
- The biggest upload of the sound we found backs 54.4K videos, and its title line ends about 3 seconds in.
- Three CapCut AI templates back the AI versions;thegroup flash one had 2,047 uses on November 6.
- Two frames and a timed prompt in the Atlas Cloud video generator rebuild the whole flash.
What Is the Mandem in Disguise Trend?
It is a reveal joke. Something looks like one thing, then turns out to be the mandem, the lads, in their uniform: black knitted balaclava, black puffer zipped to the chin, black joggers.
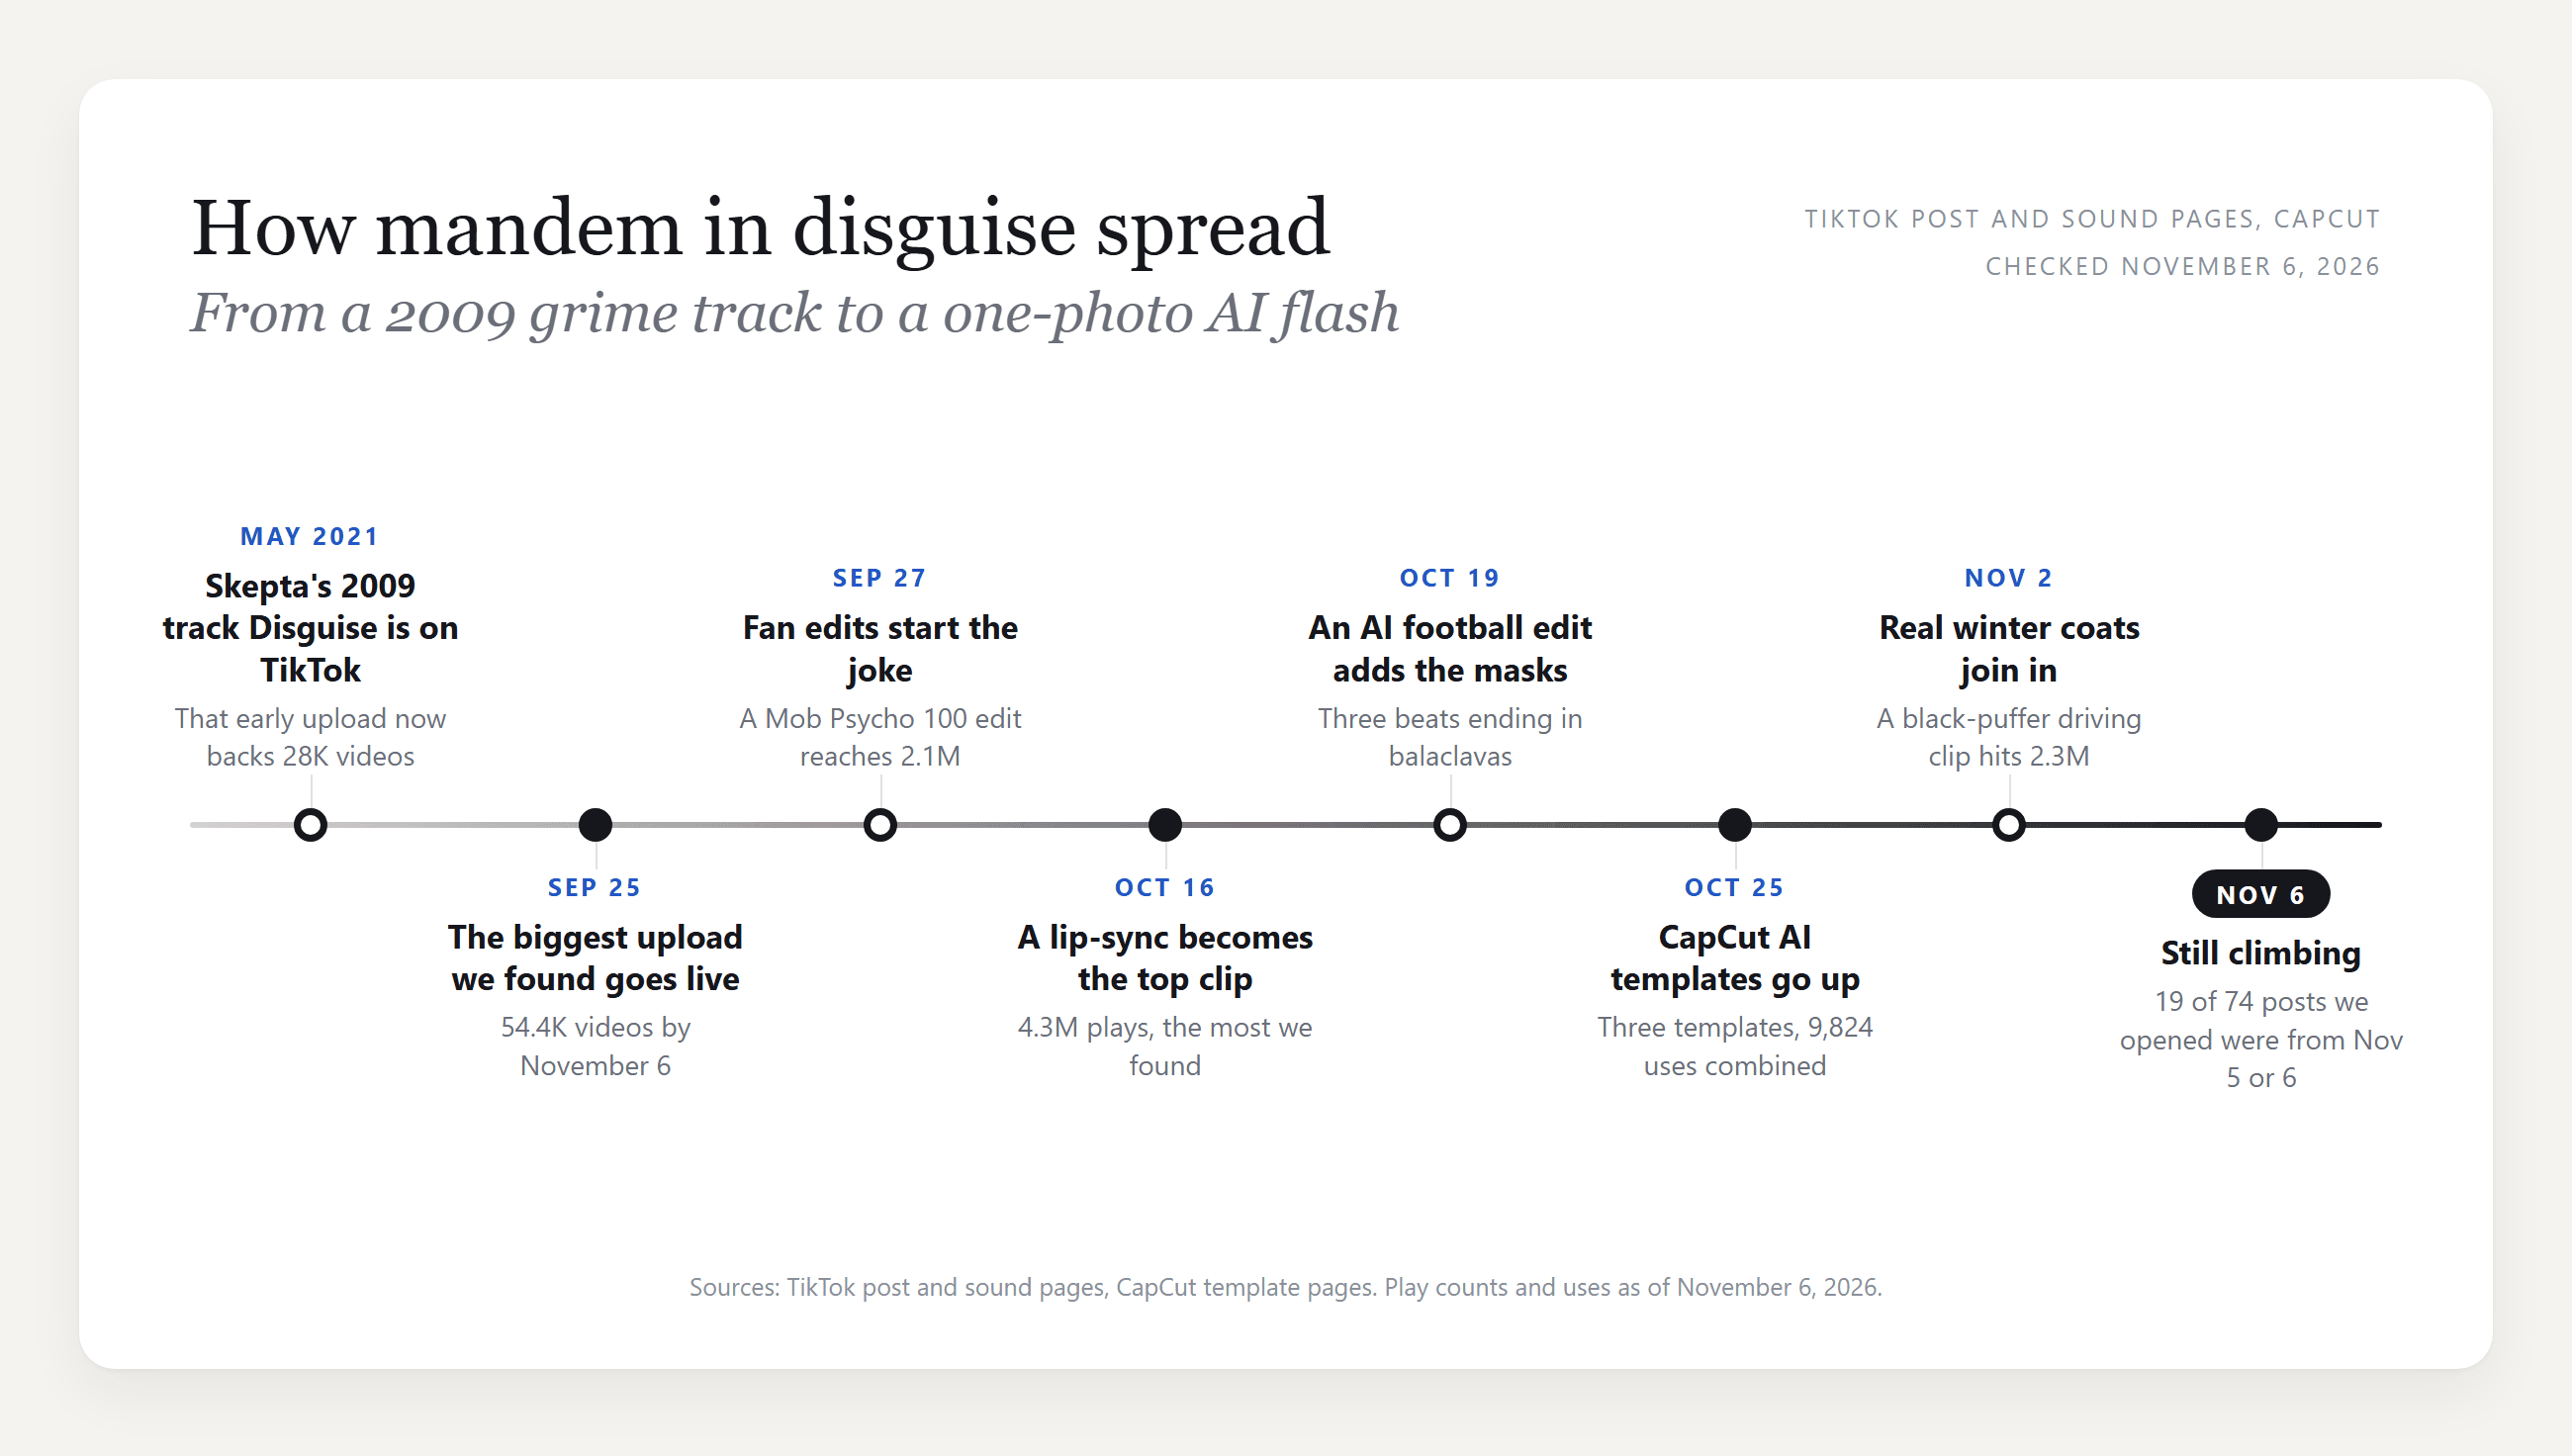
The earliest big visual versions we found were fan edits. A Mob Psycho 100 edit posted on September 27 has 2.1 million plays, and anime, Formula 1 and K-pop accounts followed. From late October, real people joined in with Halloween costumes, school-uniform cosplay, and black winter puffers worn with the hood up.
The AI version came out of football. One edit posted on October 19 shows three Manchester United players as AI-made women, then as themselves, then in balaclavas, one beat per word. It has 773K plays, and CapCut AI templates appeared six days later.
The Mandem in Disguise Song and Its 3-Second Hook
The sound is Skepta's "Disguise", recorded with JME and Jammer and released in 2009. Clips use the title line.
| Detail | What we found on November 6, 2026 |
|---|---|
| Biggest TikTok upload we found | An original sound titled "originalljud", posted around September 25, 2026, under 54.4K videos |
| An older upload | A May 2021 original sound of the same track, under 28K videos |
| Where the title line ends | About 3.2 seconds into the biggest upload |
| What that means for your edit | Start the sound at zero and put the flash at 3 seconds |
We timed the words by running that upload through a speech-to-text model. The line opens the clip and lands its last word just after the 3-second mark, which is where our flash sits.
How to Make a Mandem in Disguise AI Video From One Group Photo
You need one bright group photo and an "after" frame of the same scene. No balaclavas required.
Atlas Cloud runs Seedance 2.5, which takes a first frame and a last frame and writes the motion between them. That second slot is what makes the flash land on the exact lineup you want. Here is the mandem in disguise AI video we made:
For three seconds the girls do small, normal things: one fixes the bow in her hair, one sips an iced matcha. The flash peaks at 3.3 seconds and is gone by 3.7. Then the street is a cold blue dusk, the lad on the left still has the pink chain bag over his puffer, and the one squatting in front keeps his head down for a second before he looks up.
Method 1: Make the Flash Reveal in the Atlas Cloud Video Generator
Start with the "after" frame. We made ours in the Image Edit tab with Seedream v5.0 Pro, in two passes on the group photo. Pass one sets the outfits, the poses and the dusk light:
plaintext1Edit this photo into the "after" shot of the same moment, taken from the exact same camera position with the same framing, the same street and the same car. Everyone stays in the same spot and the same size in the frame. Lighting: the street is now darker and blue-grey like early evening, and the group is lit by a harsh direct on-camera flash, with bright highlights on the glossy jackets. Each person wears a black knitted balaclava with a single narrow eye slit, the hood of an oversized glossy black puffer jacket pulled up over it and zipped to the chin, baggy black joggers and chunky black trainers. New poses: the left one stands wide with arms crossed and chin raised, the centre one squats low in front with forearms on the knees, the right one leans back on the car with both hands in the jacket pockets. Remove the drinks and the red bag; the pink chain bag stays on the left one's shoulder as the only colour in the frame. No logos, no text. Exactly three people.
Pass two, on the result, turns the group into the mandem:
plaintext1Edit this photo. Keep the framing, the light, the poses and the clothes exactly as they are: shiny quilted black puffer jackets (not hoodies) with the hoods up, black joggers and black trainers. Change only who is wearing them: three young men, each the twin brother of the person who stood in the same spot, with the same skin tone and eye colour, and clearly male builds. The centre one has his balaclava rolled up into a black beanie so his face shows. No logos, no text. Exactly three people.
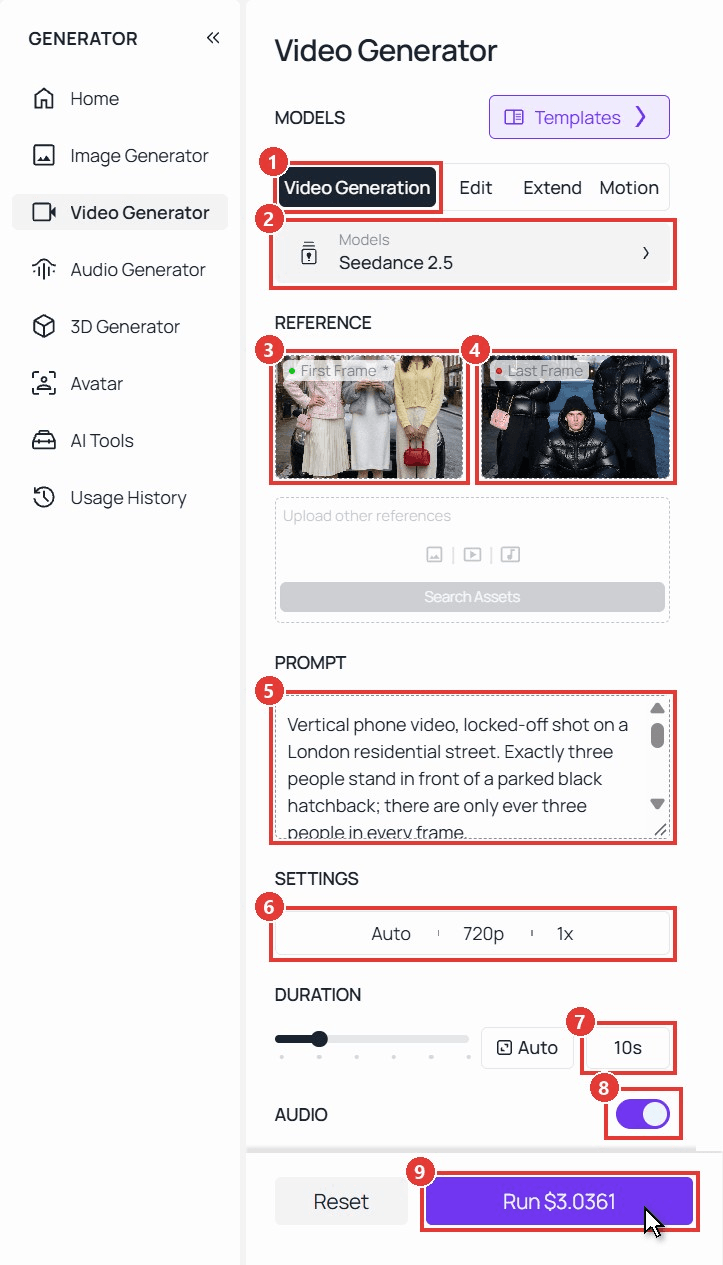
Then sign in, open the AI video generator, and follow the numbers:
- Open the Video Generation tab.
- Keep Seedance 2.5 under Models.
- Upload the group photo as the First Frame.
- Upload the "after" frame as the Last Frame.
- Paste the prompt below, with your own outfits in the first half.
- Under Settings, pick 720p for a test or 1080p for the final. The aspect ratio follows your photo.
- Type 10 in the Duration box.
- Keep Audio on.
- Click Run.
plaintext1Vertical phone video, locked-off shot on a London residential street. Exactly three people stand in front of a parked black hatchback; there are only ever three people in every frame. 20-3s: soft overcast daylight. Three young women pose in their bright girly outfits: the left one in a pastel-pink bouclé jacket and cream pleated skirt with a pink chain bag, the centre one in a lilac faux-fur coat holding an iced matcha latte, the right one in a butter-yellow cardigan holding a small red bag. Small natural movements: the left one tucks her hair behind her ear, the centre one takes a sip, the right one sways and smiles. 3At 3s: a bright white camera flash goes off and fills the whole frame with white for about a third of a second. 43.4-10s: as the flash fades, the street is darker and blue-grey and lit by a harsh direct flash, and the three girls are gone: in their places are three young men in oversized shiny black puffer jackets with the hoods up, baggy black joggers and chunky black trainers. The left one wears a black balaclava, arms crossed, the pink chain bag still on his shoulder; the centre one squats low in front, his balaclava rolled up into a black beanie showing his pale stubbled face; the right one, also in a balaclava, leans back on the car's bonnet with his hands in his jacket pockets. Almost no movement: the centre one slowly tilts his head, the left one gives one slow nod, all three stare straight into the lens, then hold the exact final frame. 5No camera movement after the flash, no cuts, no text, no logos, no extra people. 6Sound: quiet street ambience, a sharp camera-flash pop at 3s, then a heavy bass drop and a low UK drill-style beat.
Method 2: Send the Mandem in Disguise Frames Through the API
Making a version for every group chat, or adding a flash button to an app? The API takes the same two frames and prompt.
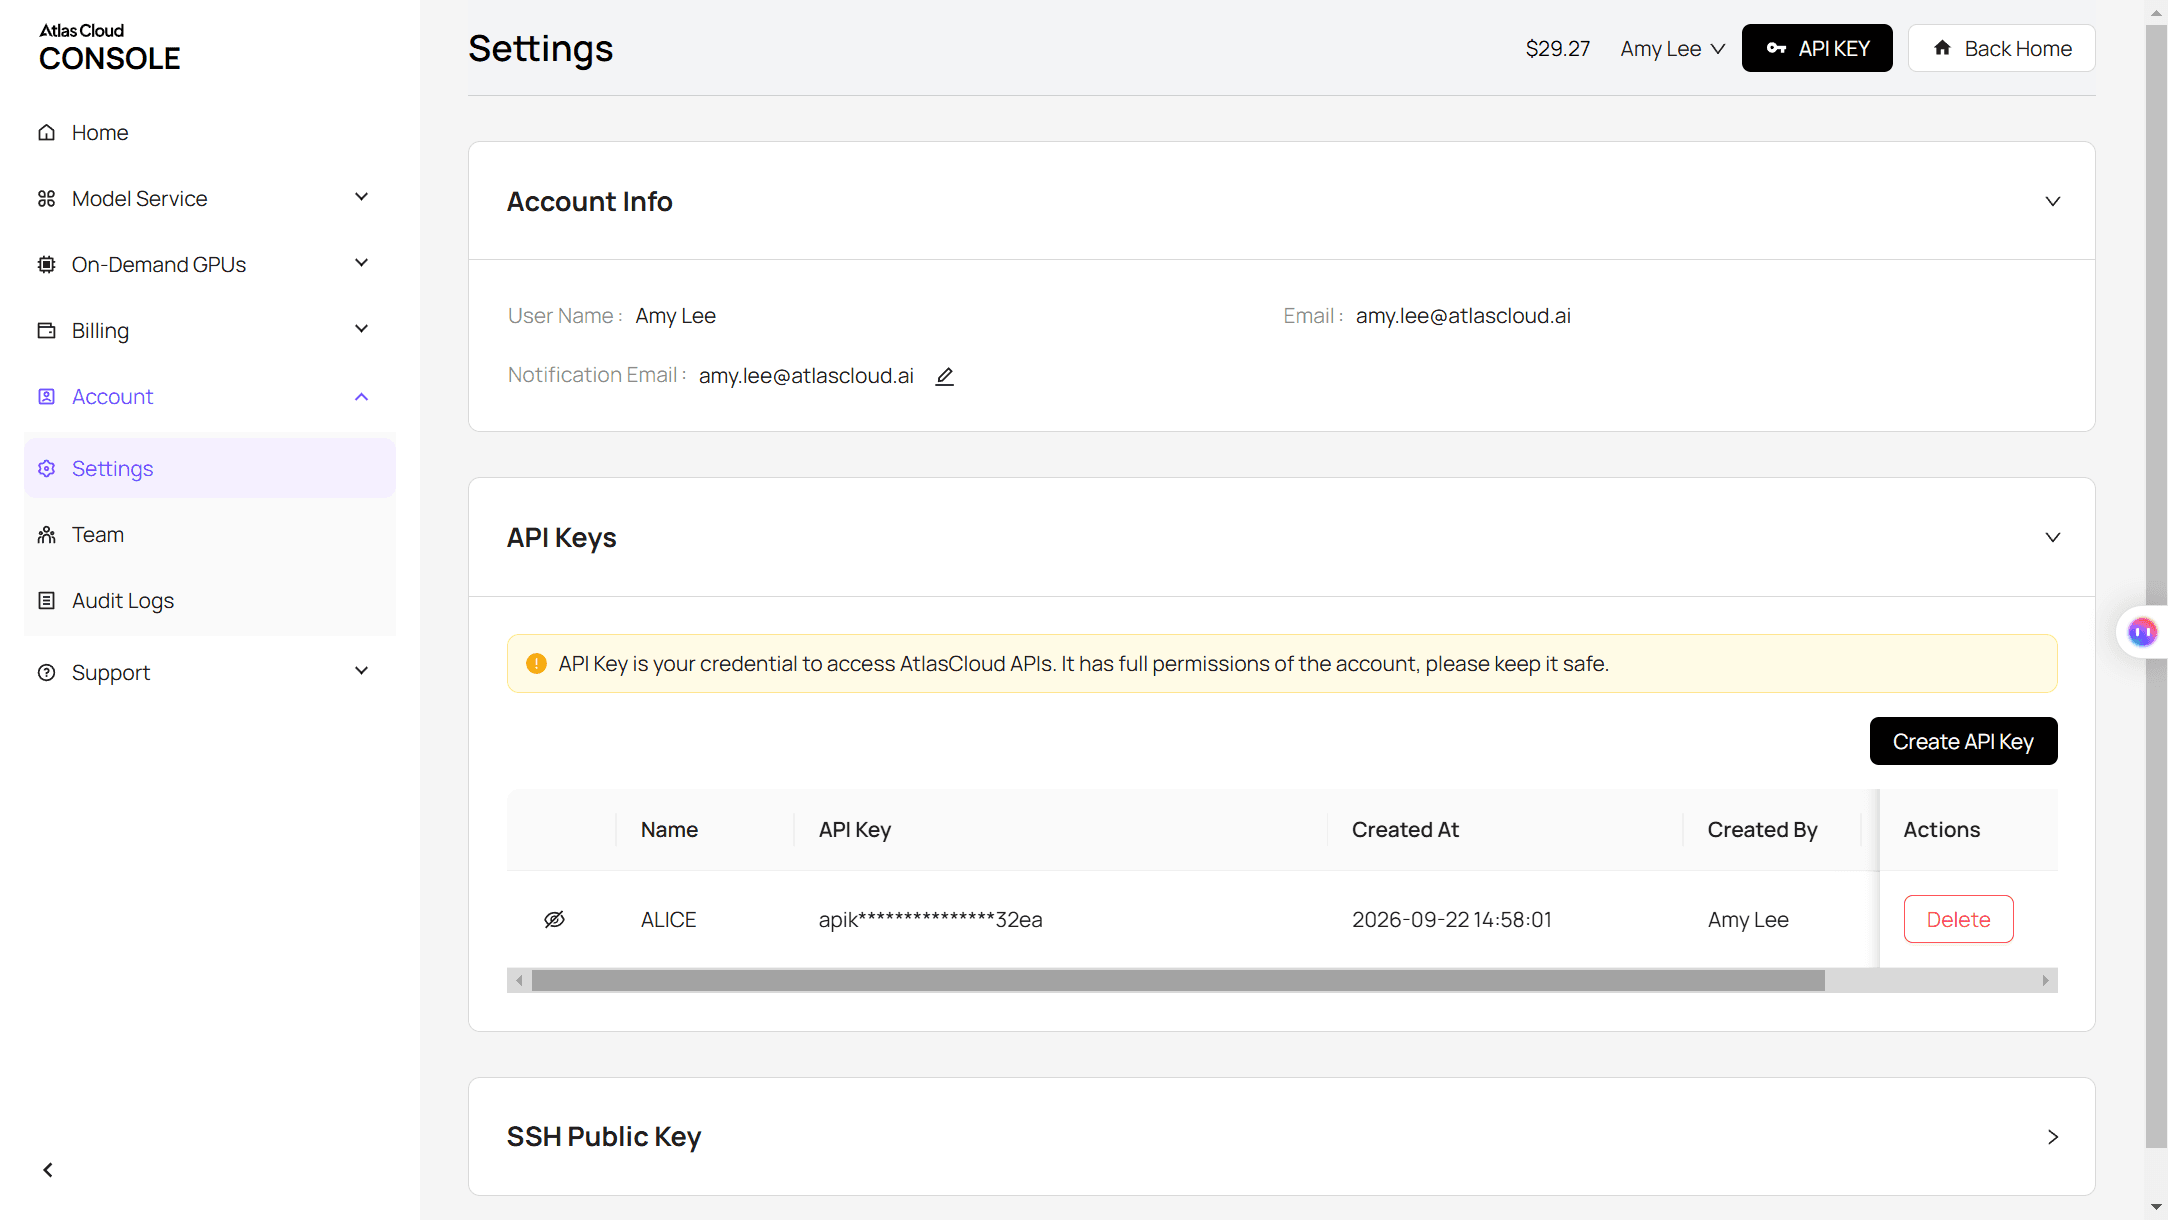
Step 1: Create an API key. In the console, open Settings and create a key under API Keys. One key works for every model.
Step 2: Check the request format. The Atlas Cloud docs cover authentication and the video endpoint.
Step 3: Send the request and poll. The group photo goes in image and the "after" frame in last_image:
plaintext1curl -X POST https://api.atlascloud.ai/api/v1/model/generateVideo \ 2 -H "Authorization: Bearer $ATLASCLOUD_API_KEY" \ 3 -H "Content-Type: application/json" \ 4 -d '{ 5 "model": "bytedance/seedance-2.5/image-to-video", 6 "prompt": "<paste the Method 1 video prompt here>", 7 "image": "https://your-cdn.com/group-photo.jpg", 8 "last_image": "https://your-cdn.com/after-frame.jpg", 9 "duration": 10, 10 "resolution": "720p", 11 "generate_audio": true 12 }'
Poll the returned prediction ID until the status reads completed, then download the clip from the outputs array:
plaintext1curl https://api.atlascloud.ai/api/v1/model/prediction/<prediction_id> \ 2 -H "Authorization: Bearer $ATLASCLOUD_API_KEY"
The endpoint and key stay the same across every video model on Atlas Cloud. To try another one, change the model string.
Which Mandem in Disguise CapCut Template Does What?
We opened 74 posts from the mandem in disguise hashtag pages on TikTok and read the links attached to each. Six linked a CapCut template, five of them "how to do mandem in disguise" tutorial accounts. Here is what those templates make, as of November 6, 2026:
| Template name | Uses | What it makes |
|---|---|---|
| photo trend | 2,047 | A group photo of girls, two white flashes, then the same lineup filled by lads in balaclavas and black puffers |
| Nansen in disguise | 1,525 | One full-body photo of a woman, cut to a masked figure in a black tracksuit with a crossbody bag |
| Ai photo | 6,252 | A single AI still of a figure in a balaclava, black puffer and black joggers, with no video |
| mandem in disguise | 7 | Coloured text cards with the lyric, no AI |
The group template and the football edit agree on the punchline: the girls come back as lads, not as the same girls in masks. That swap is why our pass two exists. None of the 74 posts used a TikTok effect made for the trend; the effects attached were general ones such as green screen and face filters.
Mandem in Disguise Prompt for a Solo Flash Reveal
One person works too. We started from a full-body street photo: a short platinum bob, a striped crop top, grey baggy jeans and a studded belt, leaning on a dark car with a pink phone.
Same workflow, 8 seconds this time. She scrolls and smirks, the flash peaks at 3.25 seconds, and when it fades the passers-by are still walking behind the car while a masked figure holds the pink phone at chest height. Four details carry most of the weight in both prompts:
| Prompt detail | What it controls |
|---|---|
| "At 3s: a bright white camera flash" | Hides the swap and lines up with the title line in the sound |
| "lit by a harsh direct on-camera flash" after the flash | The colder, darker look that makes the second half read as a new moment |
| One coloured item kept, a pink bag or a pink phone | Tells viewers it is the same spot and the same people, and gets the laugh |
| "the twin brother of the person who stood in the same spot" | Keeps skin tone and eye colour from drifting when the girls become lads |
For a gender swap without the costume, our gender swap filter guide walks through it. If you like the hooded look but want a hand over the lens instead of a flash, try the skull cap trend.
Frequently Asked Questions
What does mandem mean?
Mandem is British slang for a group of close male friends. Collins dates it to this century and traces it to "man" plus a Jamaican pronunciation of "them". In the trend, "in disguise" is the joke: the group you see first is not the group you get after the flash.
How do I do the mandem in disguise trend without AI?
Film two takes from the same spot: one in your normal outfit, one in a black puffer with the hood up and a balaclava or snood over your face. Cut between them on the title line of the sound, about 3 seconds in. A phone flash or a hand over the lens hides the cut.
Is there a mandem in disguise filter on TikTok?
We did not find one built for the trend. The AI versions come from CapCut templates or from video models like the one above, and the real-life versions are filmed.
Does the AI video come with the Skepta sound?
No. With Audio on, Seedance 2.5 writes its own audio from the sound line in the prompt; ours asked for a flash pop and a bass drop. When you post, mute that track and add the trend sound in the TikTok app from its first second, so the title line ends as the flash hits.
How much does a mandem in disguise AI video cost on Atlas Cloud?
A 10-second Seedance 2.5 clip with a first frame, a last frame and audio costs $3.04 at 720p and $5.98 at 1080p, as shown on November 6, 2026. Both are currently 20% off the $3.80 and $7.47 list prices. The "after" frame adds $0.072 per 2K image edit, so two passes come to about 14 cents.
Conclusion
Mandem in disguise is a three-second setup and a one-frame punchline. The song supplies the line, the flash hides the switch, and the balaclava and black puffer do the rest. The templates that took off agree on one thing: the girls have to come back as lads.
If you want your own, take one bright group photo, build the "after" frame in two passes, and give Seedance 2.5 both ends with the flash at 3 seconds. Keep one pink thing in the second half, and the mandem in disguise reveal lands.


