One short clip asks a character to walk forward and remove her sunglasses. Another portrait changes expression over a few seconds. A third shows a reference face drifting into somebody else. Those are more useful signals than a polished launch reel if you are deciding what to make with Meta Muse video. We reviewed 18 video posts collected during the first week of Muse activity around its Japan expansion, then watched the supplied video files rather than judging their cover frames. The clips suggest a practical use for quick, phone-first experiments, along with a specific problem for anyone whose subject must stay identifiable.
Key takeaways
- The 18 selected posts are a curated observation set, not 18 independent, controlled generations or a model benchmark.
- Short portraits and simple actions make it easy to see whether a clip holds expression, timing, and subject identity.
- A prompt can appear to follow an action while the person's face, body, or visual style changes; inspect the full clip before publishing.
- Meta's Muse agent, its Muse Video research preview, and Meta's developer API are distinct product surfaces. Public posts do not establish which model version made each clip.
What the observation page contains
The supplied research page is a visual index of X posts published from October 22 to 27, 2026. Its author reports reading 200 posts through the X API, finding 163 with video, and selecting 18 for close review. The final set includes one official post, 14 user posts, and three compilation or repost posts. Three of the user posts are explicitly labeled as failures. Each card shows a video, a short editorial note, and engagement figures captured at the time. The ZIP supplied with the page contains the 18 video files and a TSV with dates, durations, and resolutions.
That is a useful collection, but its selection process is qualitative. Popular posts can rise to the top because of an existing audience, a referral offer, or the topic of the clip. Some compilation posts repeat material already present in the user set. One 10-second portrait appears again inside a compilation. We therefore treat the set as examples of what people were posting, not as a success-rate estimate or a count of unique model runs. The saved engagement numbers are historical snapshots, not current totals.
The page says Muse launched in Japan on October 22. Meta's Japanese announcement dates the local launch to October 23, Japan time. A time-zone difference may explain the discrepancy, but the official local date is the one to use for a Japan-facing article. The page's approximate $1 figure refers to its X API research cost; it is not a Muse video generation price.
Which Muse are these posts discussing?
“Muse” now names several related things. Meta describes Muse as a personal AI agent available through an app, the web, and some messaging surfaces. Separately, Meta Superintelligence Labs introduced Muse Image and previewed Muse Video in July 2026. The research post describes native audio support and says Meta was still working on audio-video synchronization and physically accurate fast motion. Those statements describe the research preview as published, not a measured result for every clip circulating in October.
The users in this sample say they used Muse to make video, often in the phone app. Their posts and the downloaded clips are evidence of the outputs they shared. They do not reveal the backend model identifier, its version, generation settings, hidden edits, or the number of attempts behind a successful post. It would be a mistake to attribute a specific visual behavior to a named research checkpoint from these files alone. It would also be a mistake to use Meta's Model API pricing page to calculate the cost of these videos: that page lists text, image, transcription, and segmentation charges, but no published Muse Video generation rate in the version we checked.
This distinction matters when planning a production workflow. A casual user may care whether a usable short can be made in an app. A developer needs an API, documented limits, reproducible settings, and predictable cost per accepted clip. The posts speak mostly to the first question.
What the videos show when you watch them, not just the thumbnails
A launch clip demonstrates the format, not the failure boundary
The official launch post is a 6-second sequence of small character photographs arranged on a tabletop. A hand places a new print among them. It is a clear launch illustration of short-form visual creation, but it does not test whether a human face stays consistent over 10 seconds, whether a product label remains readable, or whether fast action follows physical rules. The difference between a promotional sequence and a controlled user test is worth keeping in view throughout this sample.
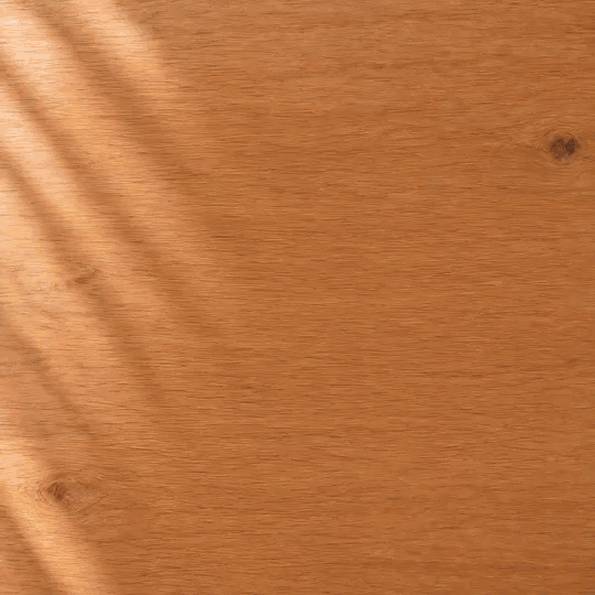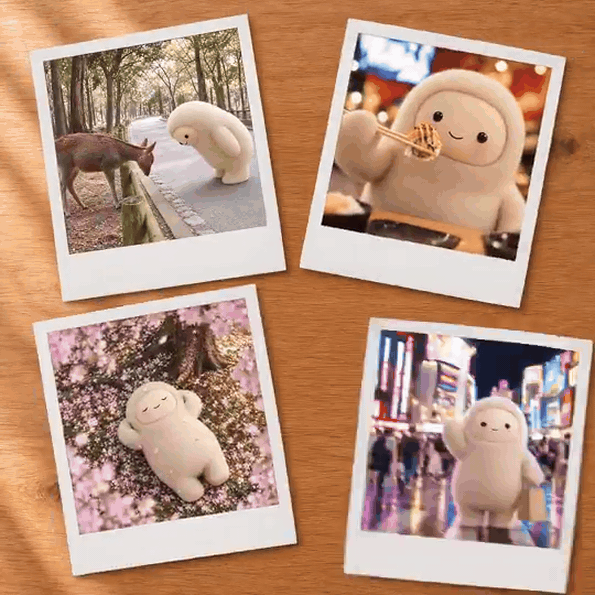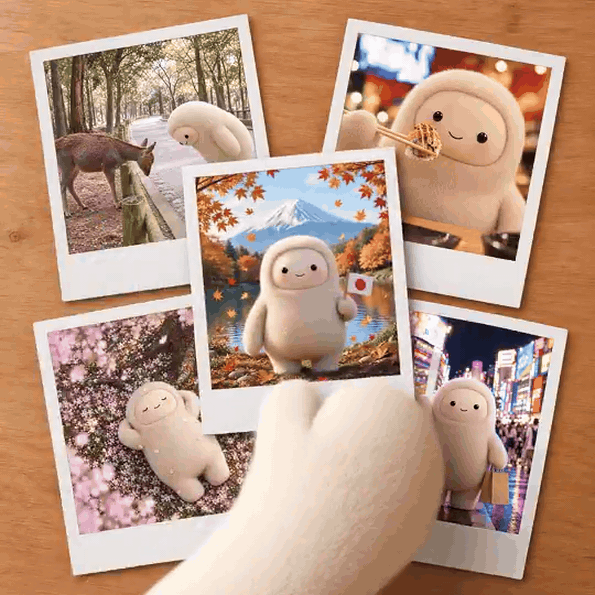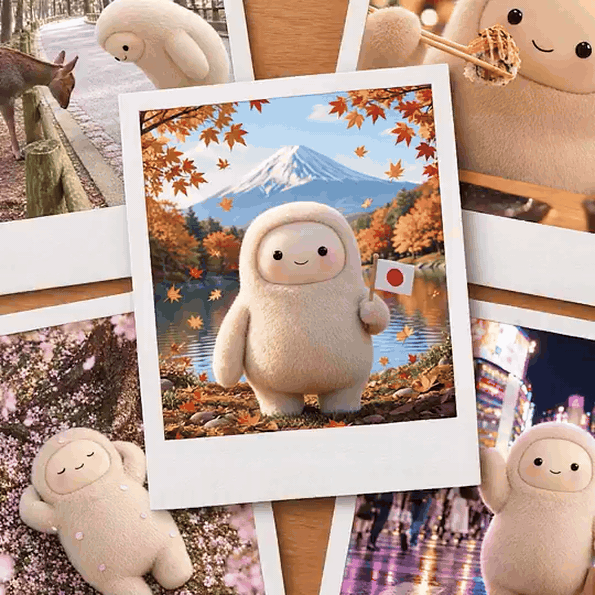
The complete 6.2-second official clip, converted to a silent GIF from the supplied archive. The still photographs and hand placement are the point of this example.
Portrait motion is easy to like and easy to misread
In one user post, a close-up character moves from concern to a smile, cuts to a wider teddy-bear shot, and returns to the face. The expression change gives the clip a beginning and a payoff in about seven seconds. This is the kind of motion a phone user can assess immediately: does the character react, and does the edit feel like one short idea rather than a still image with camera movement?
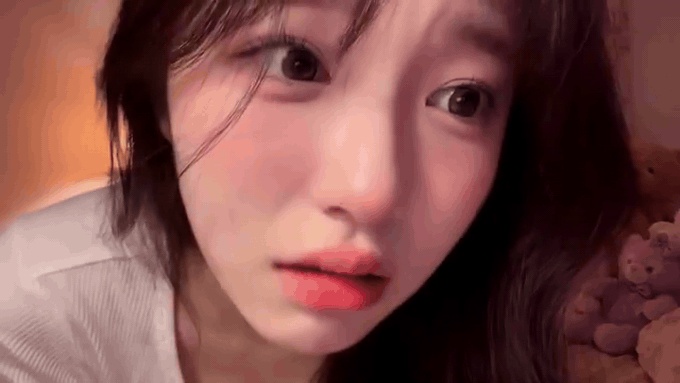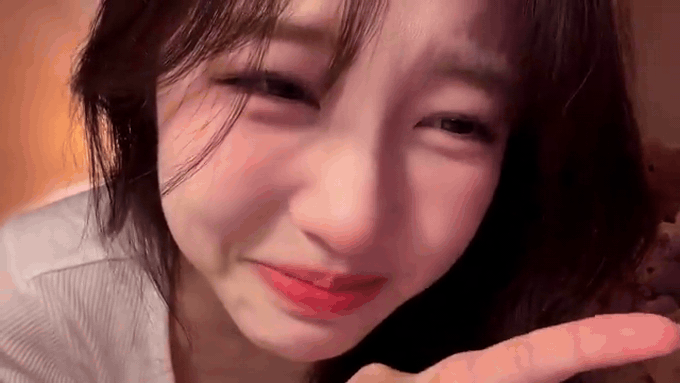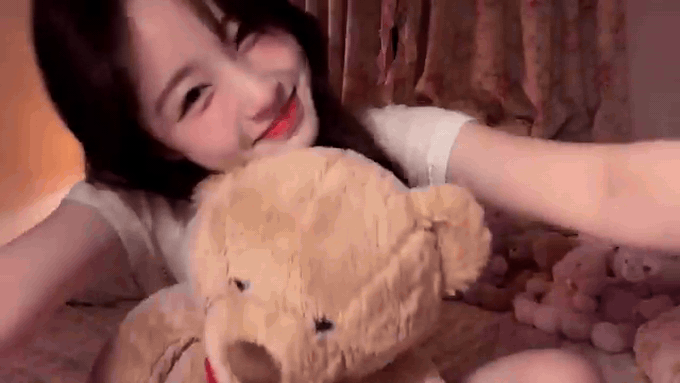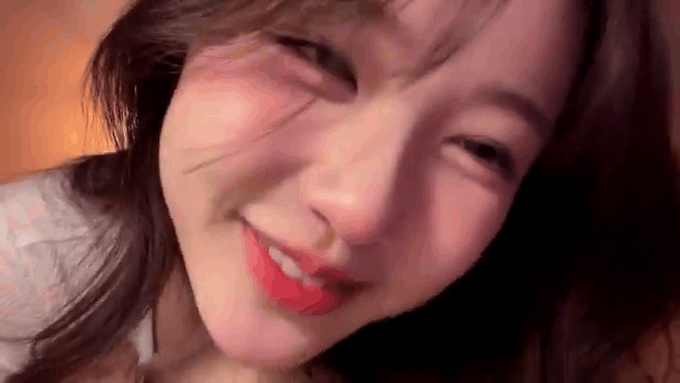
The complete 7.4-second clip from the observation set, shown as a silent GIF. The cut to the teddy bear makes this an expression-and-editing example, not a continuous identity test.
It is less useful as proof of portrait consistency. The short changes framing and includes a cut, so the viewer does not get a continuous, high-resolution view of the same face throughout. The accompanying post claims Muse is cheaper than another video model, but it does not provide comparable settings, generation counts, or invoices. Treat that as an anecdotal cost impression, not an independent price comparison.
Another phone-first clip moves from a rear view at a cafe entrance to a front-facing conversation shot. The change also shifts angle, lighting, and distance. For a character campaign, the test is not whether each frame looks plausible alone. It is whether a viewer recognizes the same person when those conditions change. A single first frame cannot answer that.
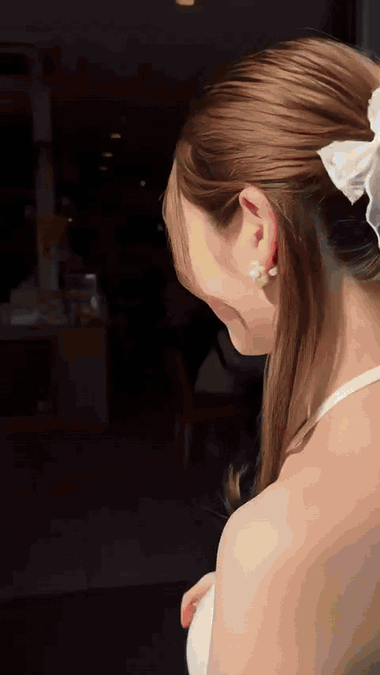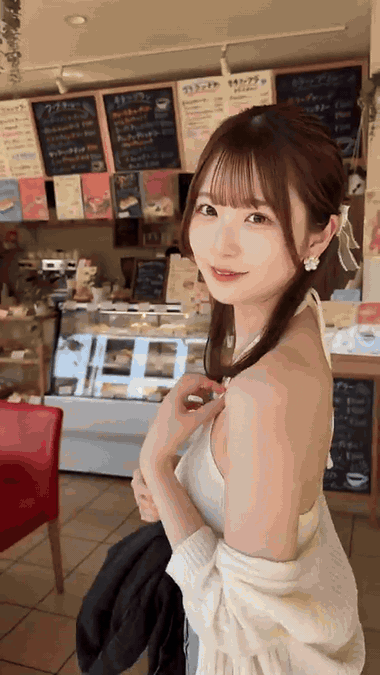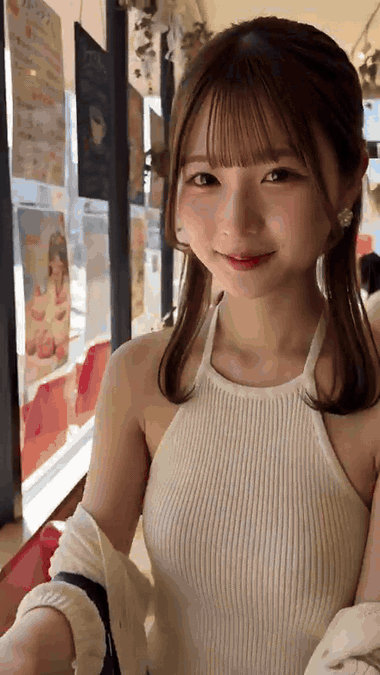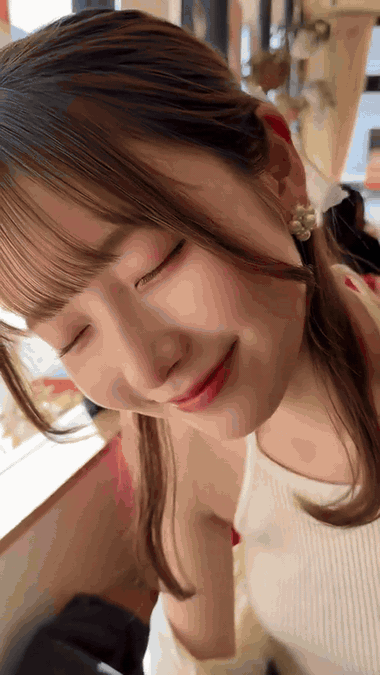
The complete 10-second cafe clip from the supplied archive, converted to a silent GIF. Compare the subject at the entrance, inside the cafe, and by the window to judge whether the character remains recognizable across the change in angle and light.
A short instruction can produce an action and still lose the reference
One post reports giving a reference image and a brief instruction: walk toward the camera and remove the sunglasses. The archived clip does show a walking subject and the glasses come off. It also transitions from a realistic street portrait into an anime-like close-up. The accompanying note was positive about the result, so this is not a claim that the user considered it a failure. It is a reminder that action adherence and style continuity are separate checks. If the reference image is meant to lock a character for an advertisement or series, the final frames matter as much as whether the requested gesture happened.
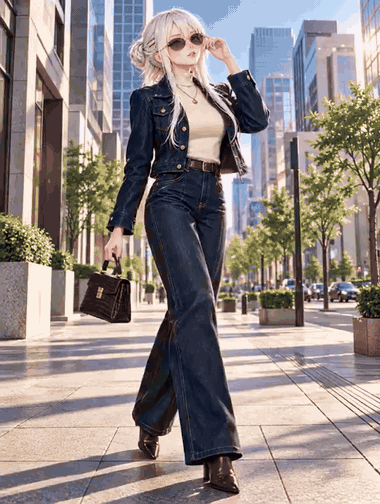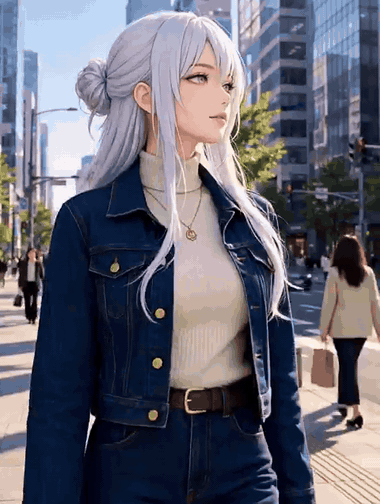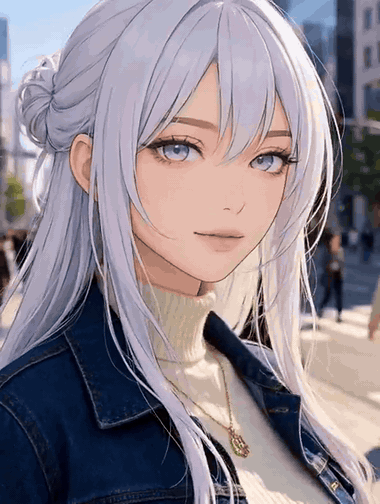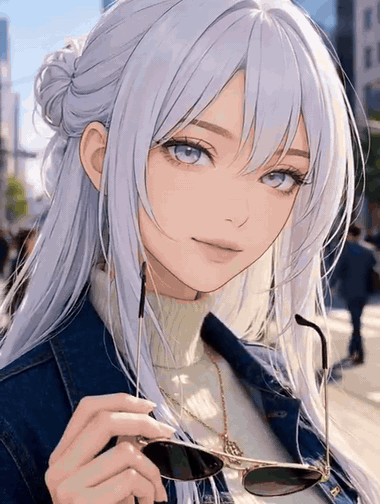
The complete 10.1-second archived clip. Watch the move from a realistic walking shot to a stylized close-up after the sunglasses action.
This is where a more specific brief helps. State which features must persist, which single action is allowed, and whether the camera should stay in one shot. Even then, a written constraint is a request, not a guarantee. Compare the first, middle, and final frames against the source image before deciding that the clip is usable.
Visible Japanese text is not the same as verified Japanese text
An animated Halloween clip moves a character through a bright street. The accompanying note says Japanese text appears in the scene. In the supplied video, sign-like lettering remains present as the camera moves. That is a useful observation for a Japanese setting. It is not a legibility audit: some characters are small, angled, or visible for only a fraction of a second. For a real storefront name, safety label, or product package, freeze the exported video at full resolution and check every required character. A generated sign should never be the only source of important copy.
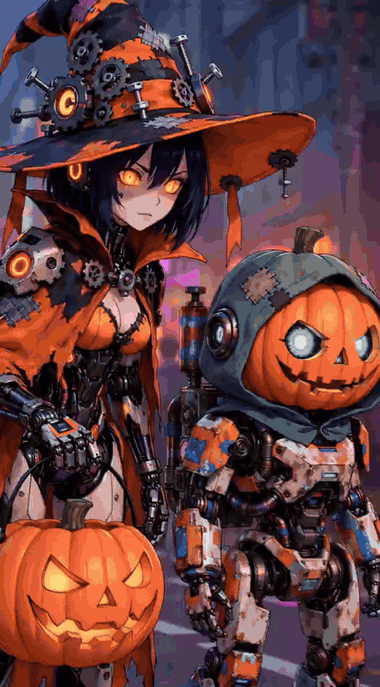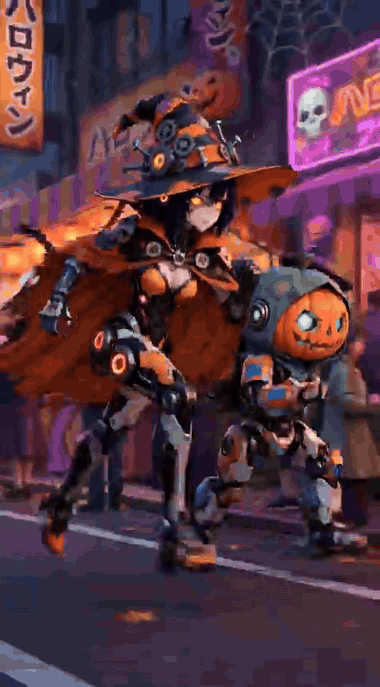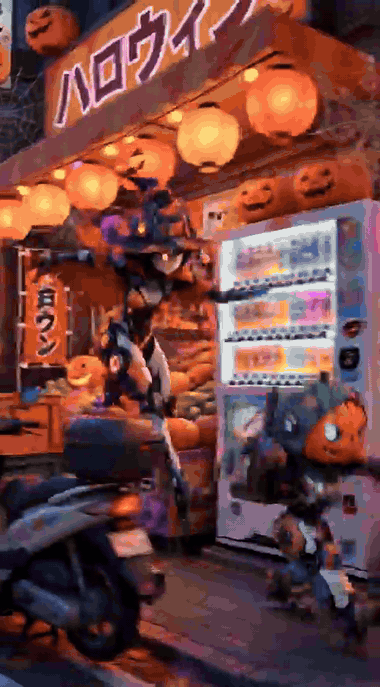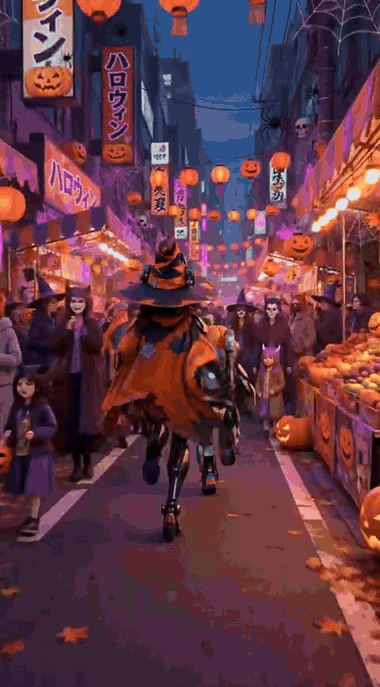
The complete 10.1-second archived clip. The poster shows the moving character beside Japanese-style signage; text accuracy needs a separate check.
The failure posts show why identity needs its own review pass
One of the clearest negative examples is a test of an increasingly sinister smile. The accompanying note says the face changes too much. Watching the 10-second clip, the subject approaches the camera and the face's proportions and expression shift with the framing. This example is valuable because the drift is identified rather than hidden behind a favorable frame.
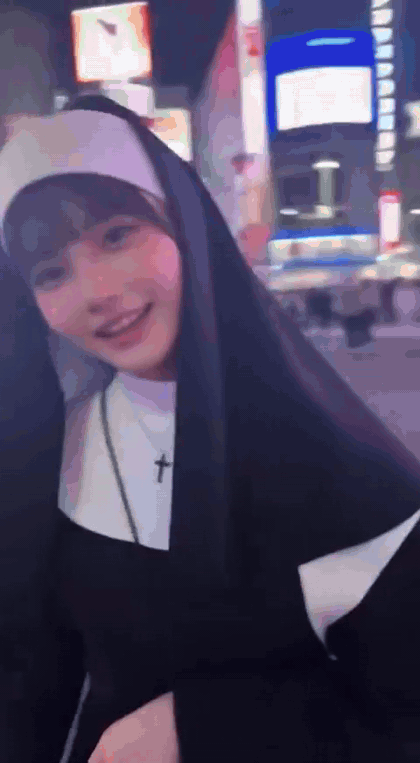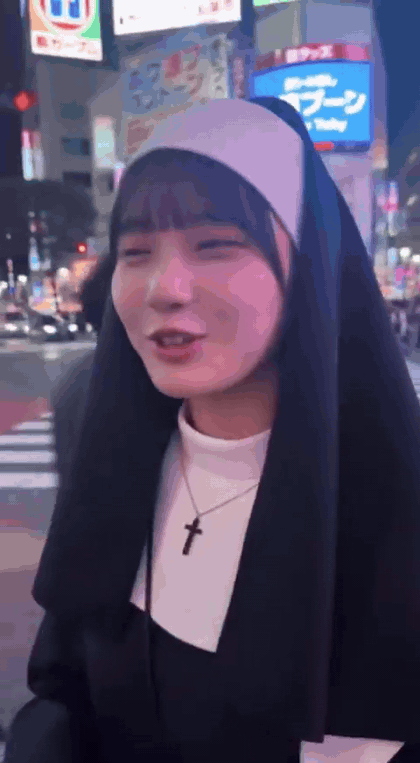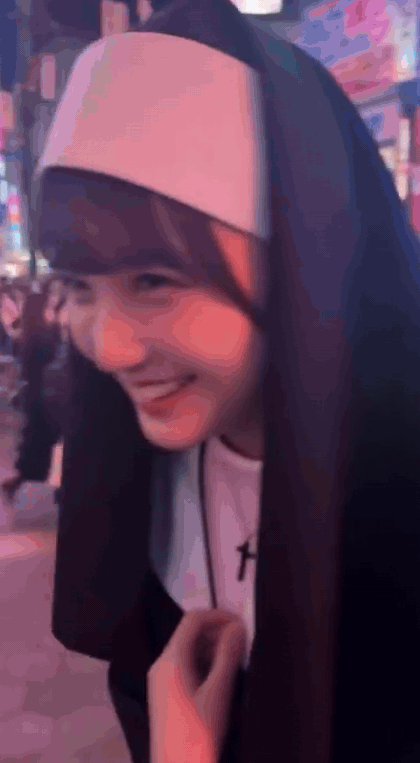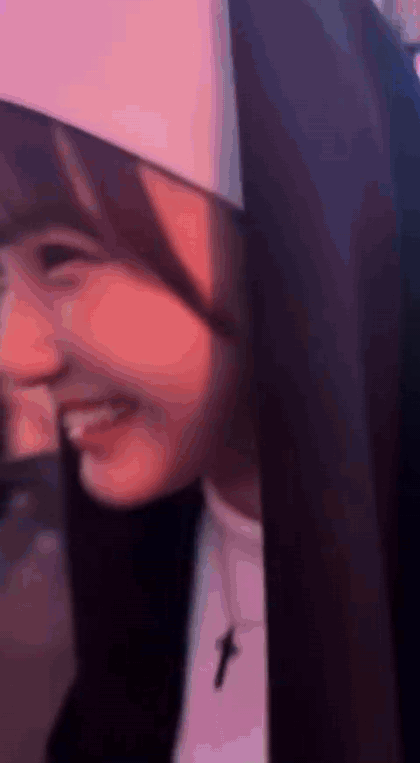
The complete 10.1-second archived clip. The accompanying note explicitly calls out the face change during the smile test.
Two other posts in the collection make related complaints: one says two distinct reference characters became different people, and another says a referenced woman's identity and body type changed. We cannot reconstruct their original inputs from the archive, so we report these as user observations and use the visible clips only for what they show. Their shared warning is practical: reference-based animation should be reviewed for identity, silhouette, clothes, and scene continuity, not just motion.
| Creative task | What these clips can show | What they cannot prove | Review before use |
|---|---|---|---|
| Short expressive portrait | Whether a face changes expression and keeps the shot alive | Stable identity across cuts or a longer sequence | Compare face shape and distinctive features at start, middle, and end |
| Reference-image action | Whether a requested gesture appears | That the reference locks style, outfit, or body | Check the reference beside final frames and note every drift |
| Animated scene with signage | Whether text-like marks persist in a moving frame | Correct spelling or readable Japanese | Inspect full-resolution stills from the export |
| Multi-character or fast motion | Whether the scene has movement and a recognizable beat | Physical accuracy, exact count, or reliable character separation | Review frame by frame around contact, turns, and occlusion |
How to test Muse video without mistaking a good post for a reliable workflow
Start with a task whose acceptance criteria you can write down before generating. For a character short, choose one reference image, one action, one camera plan, and one target duration. Save the exact instruction you submit. If the product offers aspect ratio, quality, or duration controls, record the settings visible on your own screen. The X archive does not contain those settings for its examples, so reproducing them from the clips would be guesswork.
For instance, a reference-image test brief could say: “Use the uploaded portrait as the same adult character throughout. In one continuous waist-up shot, she walks two steps toward the camera, pauses, and removes her sunglasses with her right hand. Keep her hair, jacket, face shape, and background consistent. Use natural daylight and a vertical frame.” This is a test prompt, not the prompt behind any video in the collection. Its value is that it gives the reviewer separate checks for action, character, setting, and camera behavior.
Make at least three attempts with the same brief before drawing a workflow conclusion. Keep failed outputs, not just the best one. Log whether each run satisfies the specific acceptance criteria and how much time you spent revising it. A cheap generation that requires many retries can be more expensive per usable clip than a pricier model that succeeds early. The supplied page records the cost of collecting X data, not the cost per generated video, so it cannot answer that economic question.
If the piece will be posted by a brand, run a final human review for rights and representation. Confirm that any real person's face or voice is used with permission, that a generated character does not impersonate a person, and that product claims and on-screen words are accurate. These are editorial checks regardless of model choice. If consistency or exact text is essential, use generated motion as footage to review and edit, then add verified typography in a conventional editor instead of trusting text rendered inside the clip.
Anyone comparing other hosted video models can use the same brief and acceptance sheet in Atlas Cloud's model catalog. Keep the comparison fair by matching duration, aspect ratio, reference input, and review criteria. The sample here does not establish a ranking between Muse and any other model.
What to take from the first wave
The useful reading of these 18 posts is narrower than “Muse is good” or “Muse is bad.” The short clips show that users were quickly making portraits, anime scenes, action prompts, and remixed compilations after the Japan launch. They also show why a 10-second export needs a full watch: a face can drift late in the clip, a style can change after the requested action, and lettering can be present without being reliable. A prompt-following moment is not the same as a finished production asset.
For your first Meta Muse video test, pick one small scene with one observable action. Save the reference and prompt, inspect the full export, and judge the result against the criteria you set before seeing it. That gives you an answer you can use, even if the clip itself does not make the cut.
FAQ
Is the Muse app the same thing as the Muse Video model?
Meta presents Muse as a personal AI agent and separately published a research preview of Muse Video. The public posts in this collection do not expose the backend version used by the app. Avoid treating the names as interchangeable in a technical comparison.
Is Meta Muse video generation free?
Meta says many basic Muse agent functions are free and offers subscription plans for heavier use. Several posts describe phone video creation as free. Those reports do not establish a permanent video quota or a developer price. Check the current terms in the app before planning a recurring production schedule.
Does this sample prove Muse is better or cheaper than other video models?
No. The page is a curated collection of social posts, not a controlled side-by-side test. It lacks the prompts, matched settings, retry counts, and verified generation charges needed for a quality or cost ranking.
Can I reuse the videos in my own campaign?
The archived posts and clips supplied for this review are third-party examples. Their presence in a research page does not grant reuse rights. Obtain permission from the rights holders or make and review your own original outputs.
Sources and observation notes
- Meta Japan's Muse launch announcement, dated October 23, 2026 in Japan.
- Meta Superintelligence Labs' Muse Image and Muse Video introduction, published July 7, 2026.
- Meta Model API pricing and rate limits, checked October 28, 2026.
- The 18 supplied video files and
清单.tsv. We reviewed the archived files directly; a social post's attribution and engagement can change after capture.





