A two-person scene becomes convincing when you can see and hear who owns each line. To make Gemini Omni 1.2 Flash multi-speaker dialogue easy to follow, give each character a fixed visual and vocal identity, write short lines in speaking order, and review the finished video with your eyes and ears. Google's November 2026 update supports more natural multi-speaker speech and clips up to 15 seconds, but a prompt cannot guarantee clean speaker assignment on the first render. Start with a simple 2-person exchange, then add a third turn or street ambience only after you can judge the basic handoff.
Key takeaways
- Gemini Omni 1.2 Flash generates video with native sound, including dialogue; it is different from audio-only Gemini text-to-speech models.
- Use named speakers, exact quoted lines, clear positions, and a silent listener for each turn.
- Leave room for pauses within the 15-second maximum, then check every line against the clip.
- Price a render from its selected duration and resolution, not a platform's lowest advertised rate.
What Does Multi-Speaker Dialogue Mean in Gemini Omni 1.2 Flash?
The model makes a short scene in which people can speak as part of the generated audio and video. The practical test is whether a viewer can tell who says each line without reading a transcript. The words, voice, visible person, and mouth movement need to agree at the same time. A clip may look persuasive with its sound muted and still fail that test.
Google announced Gemini Omni 1.2 Flash on November 5, 2026, with up to 15 seconds of generated or edited video. It describes more fluid dialogue, clearer lip sync, and distinct multi-speaker conditioning. Those are capability claims, not a promise that every script will be delivered exactly as written (Google's November 2026 announcement).
Google's published demonstration shows the capability it announced. It is separate from the three supplied video cases below.
What Changed From Gemini Omni 1.1 Flash?
The official comparison gives 1.2 a longer ceiling: 15 seconds rather than 10. It also names improvements in speech, lip sync, reference following, and conversational editing. The extra 5 seconds make a 3-turn exchange more plausible to script, but a longer duration does not create more speaking time if a director also asks for pauses, physical reactions, and scene changes.
The safest reading is directional. Better conditioning may make dialogue easier to direct, while each delivered clip still needs inspection. A creator can use the 15-second limit to set a script target. A producer promising exact legal copy or a precise voice match should treat generated output as a draft until it passes review.
Video Dialogue vs Multi-Speaker Text-to-Speech
Gemini text-to-speech models accept text and return audio. Their speaker settings and voice choices belong to that audio workflow, which Google documents separately (Google's Gemini text-to-speech documentation, accessed November 2026). Gemini Omni 1.2 Flash's text-to-video route accepts a scene prompt and produces video with native sound. A text-to-speech speech_config example is not a Gemini Omni 1.2 Flash video control. These examples describe vocal character in text; they do not claim to upload, clone, or select a recorded voice. If a brief requires the voice of a specific actor, verify that access and consent separately before planning the shot.
If your deliverable is a podcast conversation or a locked voiceover, use text-to-speech and edit the picture around that audio. If it is two people visibly speaking in a generated scene, use Gemini Omni 1.2 Flash video and test alignment in the actual output.
Where Can You Run It, and What Will a Clip Cost?
Choose the Text-to-Video Route
Google lists Gemini Omni 1.2 Flash across its creative and developer products. For a reproducible test, use one route: Atlas Cloud offers the model, and its Gemini Omni 1.2 Flash Text-to-Video playground is where to paste the prompts below. The route ID is google/gemini-omni-1.2-flash/text-to-video. The prompts below use text only, without image, motion, or voice references.
The prompts request 12 seconds in 16:9 for the office, 15 seconds in 16:9 for the café, and 12 seconds in 16:9 for the street interview. The three supplied files are 720p. Confirm the live controls and selected values before pressing Run. A setting advertised on a product page is not proof that a particular test run accepted it. Save the selected values and the quote with each output. This makes every render useful evidence: you can compare the prompt with the selected resolution and route when reviewing its output. This guide specifies the text-to-video route, so a result from an image-to-video or reference-to-video route should be identified separately.
The supplied video files do not include a completed playground capture, selected settings, or a pre-submit quote. Their route and configuration therefore remain unverified.
| Route | Input for this guide | Best fit | Where to verify cost |
|---|---|---|---|
| Google's creative products | A scene prompt; controls vary by product | Manual creation in Google's editor | The current plan or credit screen |
| Google API | A developer video request | Application integration | Google's price for the exact resolution |
| Atlas Cloud text-to-video | Prompt, duration, aspect ratio, resolution | Repeating these text-only tests in one playground | The selected configuration's pre-submit quote |
Check the Price Before You Render
Google quotes $0.07 per generated second for 720p through its API, 30% below Gemini Omni 1.1 Flash. At that quoted rate, 12 seconds of 720p is $0.84 before any other billable work. That calculation is not an Atlas Cloud quote for the supplied files; their route and billing are unverified. Credits in Flow or another editor follow that product's own rules.
Atlas Cloud lists a lower starting per-second rate on its model catalog, but the minimum may correspond to another resolution or configuration. Read the live quote after choosing duration and resolution. A 360p draft can help explore a prompt; it is a separate generation rather than a frame-for-frame preview of a later 1080p render.
Fit Two Voices Into a 15-Second Scene
Give Each Speaker a Visual and Vocal Identity
Write descriptions that a reviewer can verify. "Speaker A is on the left in a navy shirt" is clearer than "the first coworker." Add an audible distinction, such as mid-pitched versus lower. Keep names, clothing, position, and voices consistent across the prompt. These anchors make a swapped line easier to spot.
Visual identity matters because audio alone can fool a reviewer. If voices differ but the wrong mouth moves, the clip has a lip-sync problem. If the correct mouth moves but A's voice changes on A's second turn, it has voice drift. The café example brings A back after B so a reviewer can check whether A's voice stays consistent.
Budget Time for Speech and Reaction
Read the script aloud at the intended pace. Include a natural pause at each handoff, then leave space for a listener to react and for the opening shot to establish both faces. The revised office script has 5 turns in 12 seconds. The café has 8 short turns in 15 seconds, making it the most demanding timing test here. These are example scripts, not a universal words-per-second threshold or a promise about output.
| Scene budget | Spoken sequence | Time needed beyond words |
|---|---|---|
| 12-second office | A-B-A-B-A | Establish both people and fit 4 handoffs |
| 15-second café | Eight alternating turns | Seven handoffs with little spare time |
| 12-second street | A-B-A-B-A | Four handoffs over street ambience |
A long line invites rushing or omission near the end. If the draft takes almost all 15 seconds to read aloud, shorten it before generation. If the scenario needs more dialogue, plan separate shots and verify continuity as another production task. Keep faces visible during spoken lines on the first attempt. Rapid cuts and occluded mouths make speaker assignment harder to judge. Do a timed table read with two people if the line order matters. Have one person speak A and the other B while a third person notes where each sentence ends. If the last word lands at the clip limit, remove a clause or a reaction beat before rendering. A shorter script is easier to audit because the reviewer can replay the whole exchange without guessing whether a line was intended to continue offscreen.
How to Prompt Gemini Omni 1.2 Flash for 2 Speakers
A useful prompt reads like a compact shooting brief: setting and camera, identities, exact dialogue, then sound and exclusion rules. This order also gives a reviewer a checklist. It is a prompting method, not a documented guarantee of control. Keep the character labels identical from the identity paragraph through the dialogue block. Avoid referring to the same person as both A and “the customer” in instructions about a later turn unless the mapping is already explicit. A reader should be able to draw two columns, one for each person, and place every requested action and spoken line into exactly one column.
Use Explicit Speaker Labels and Quoted Lines
Use one line per turn with Speaker A: or Speaker B: and quoted words. Specify who remains silent. Asking for "a discussion about launch readiness" allows improvisation. An exact script lets you mark a missing or rewritten word immediately.
Here is the first prompt to copy. It keeps both adults in one continuous shot so the viewer can inspect each mouth.
plaintext1Create a 12-second realistic video in one continuous medium two-shot in a quiet office. Two adult coworkers remain visible throughout. Speaker A is a woman on the left wearing glasses and a navy striped top, with a clear mid-pitched voice. Speaker B is a man on the right wearing a white shirt, with a lower voice. A points to an open laptop; B checks a notebook. 2 3Dialogue, spoken exactly in this order: 4Speaker A: "Can we publish the page now?" 5Speaker B: "Almost. One link needs fixing." 6Speaker A: "Which one?" 7Speaker B: "The footer link." 8Speaker A: "I'll fix it now." 9 10Only the named person speaks each line. The listener stays silent and reacts naturally. Keep each voice attached to the same person throughout. Show the correct mouth moving for every line, with brief natural pauses. Quiet room tone. No narrator, third voice, subtitles, music, or logos.
Supplied 12-second, 720p office render. Both people remain visible; the five spoken lines and lip sync still require a listening review.
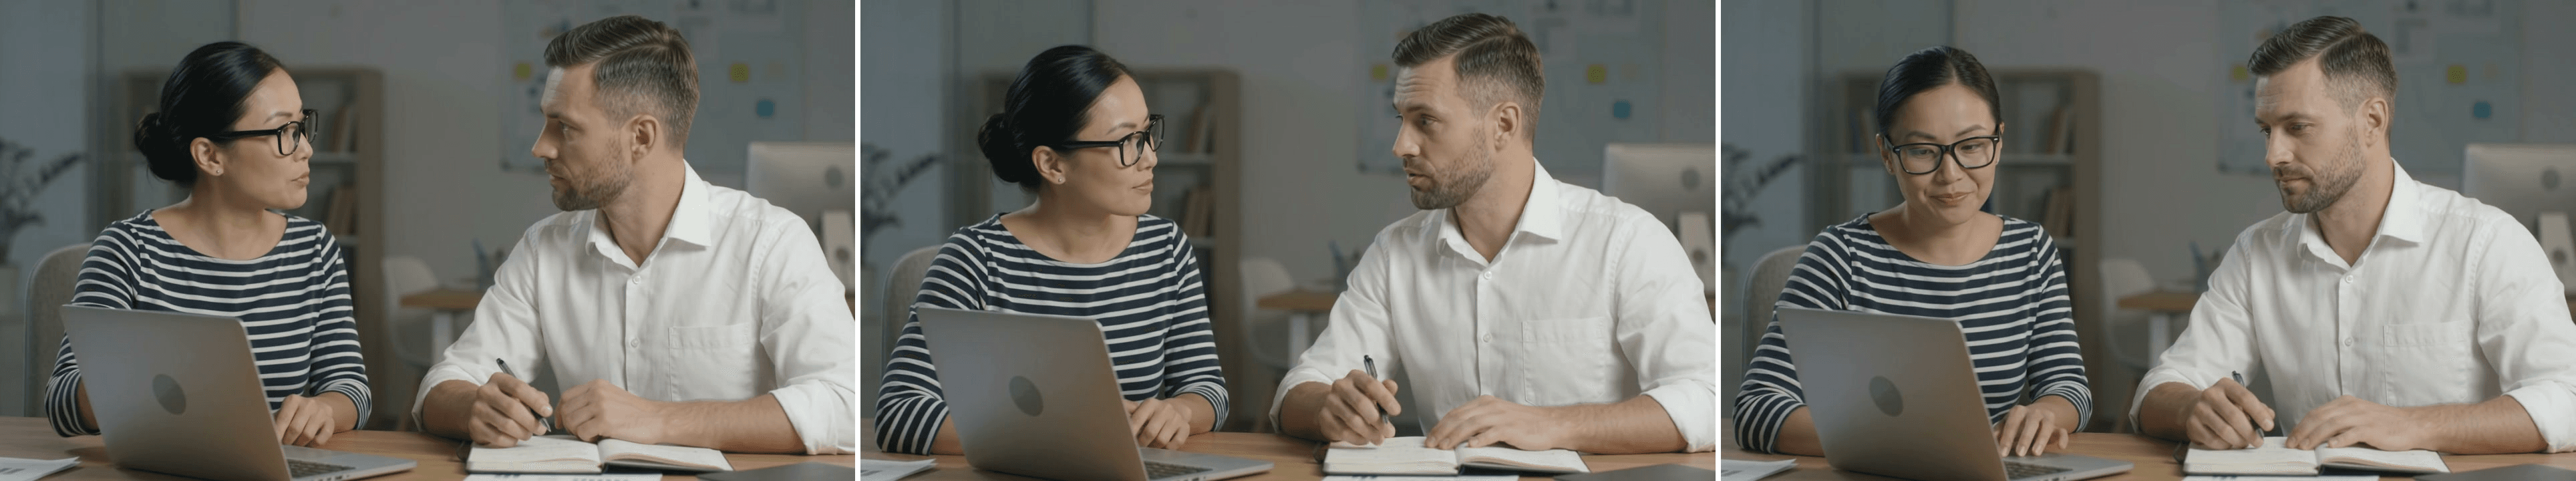 Case A frames, left to right (about 0:02, 0:05, 0:10): the woman faces her coworker; he appears to reply while both stay in frame; they return their attention to the laptop and notebook.
Control the Camera Without Losing the Speaker
A continuous medium 2-shot is a diagnostic choice. Both faces remain in view, so a missed handoff cannot hide behind editing. The model may still vary framing, which is why the final file needs inspection.
Once the handoff works for your purpose, try a modest move that preserves both faces. The street prompt requests one in a 16:9 frame that keeps both faces visible, making mouth movements easier to judge. That is a reason to establish the office baseline first.
Keep Background Audio Below the Dialogue
Name the ambience and its priority. Quiet room tone gives the office clip little to compete with speech. Soft café sound adds context while keeping lines testable. The street prompt asks for footsteps and distant sound below both voices, without bystander speech.
Negative instructions may reduce unwanted audio, but they remain requests. Listen for a third voice, narration, music, and brand audio. Check the picture for captions and logos too.
3 Dialogue Scenes That Show Who Speaks When
The three supplied video files show the intended office, café, and street scenes. Their visual content can be inspected here, but the files do not establish which route or settings produced them. The prompts below are reproducible requests, not a claim that the output spoke every word correctly. The office checks 5 turns, the café tests 8 rapid turns, and the street adds environmental sound.
| Case | Prompt request | Supplied file | Main check |
|---|---|---|---|
| A: office handoff | 12s, 16:9, 5 turns | 12s, 16:9, 720p | Five lines, correct mouths |
| B: café exchange | 15s, 16:9, 8 turns | 15s, 16:9, 720p | Eight lines, stable voices |
| C: street interview | 12s, 16:9, 5 turns | 12s, 16:9, 720p | Street audibility and speaker turns |
A Five-Turn Office Handoff
Use the complete prompt and video above. Both coworkers stay in the same shot, so each of the five requested turns has a visible person to check. Record each audible line against the text and inspect the active mouth. The supplied file establishes the scene and duration, but its words and lip sync have not been independently verified.
A clear handoff in one clip would support a conclusion about that clip alone, not a model-wide success rate. Keep the first result so any revision can be compared with the original.
An Eight-Turn Café Exchange
Request 15 seconds in 16:9. Eight short turns put repeated voice ownership and timing under pressure. Compare each person's first and last line, then check whether any line overlaps or disappears. The supplied file is 720p.
plaintext1Create a 15-second realistic video in one continuous medium two-shot at a quiet café counter. Speaker A is an adult customer on the left in a cream sweater, holding a reusable cup, with a warm mid-pitched voice. Speaker B is an adult café worker on the right in a white shirt, with a lower voice. Both faces remain visible throughout. 2 3Dialogue, spoken exactly in this order: 4Speaker A: "Could I use my reusable cup?" 5Speaker B: "Of course. Hot or iced?" 6Speaker A: "Iced, please." 7Speaker B: "Small or large?" 8Speaker A: "Small." 9Speaker B: "Any milk?" 10Speaker A: "Oat milk, thanks." 11Speaker B: "Coming right up." 12 13Use a brisk but natural conversational pace. Do not rush or overlap the lines. Only the named person speaks each line; the other listens silently. Keep both voices consistent across all eight turns and match every line to the correct mouth. Soft café ambience stays below the dialogue. No extra speech, subtitles, music, or visible brands.
An Outdoor Q&A
Request 12 seconds in 16:9. This adds a mild camera move and environmental sound. The supplied file is 16:9 at 720p and can be reviewed for five speaker turns and street audibility.
plaintext1Create a 12-second 16:9 street interview in daylight. Keep two adults visible from the waist up throughout. Speaker A is the interviewer on the left in a dark checked shirt, holding a plain unbranded microphone, with a bright mid-pitched voice. Speaker B is the interviewee on the right in a tan jacket, with a deeper calm voice. Use a gentle sideways camera move that keeps both mouths in frame. 2 3Dialogue, spoken exactly in this order: 4Speaker A: "What makes a short video easy to follow?" 5Speaker B: "Clear voices." 6Speaker A: "What about pacing?" 7Speaker B: "Short lines and time to react." 8Speaker A: "Thanks. That's useful." 9 10Only the named person speaks each line; the other listens silently. Keep both voices consistent and match every line to the correct mouth. Keep footsteps and distant street ambience below the dialogue. No bystander speech, narrator, music, captions, or logos.
Combined playback: 0:00–0:15 is Case B, the café exchange; 0:15–0:27 is Case C, the street interview. Both source clips are included in full.
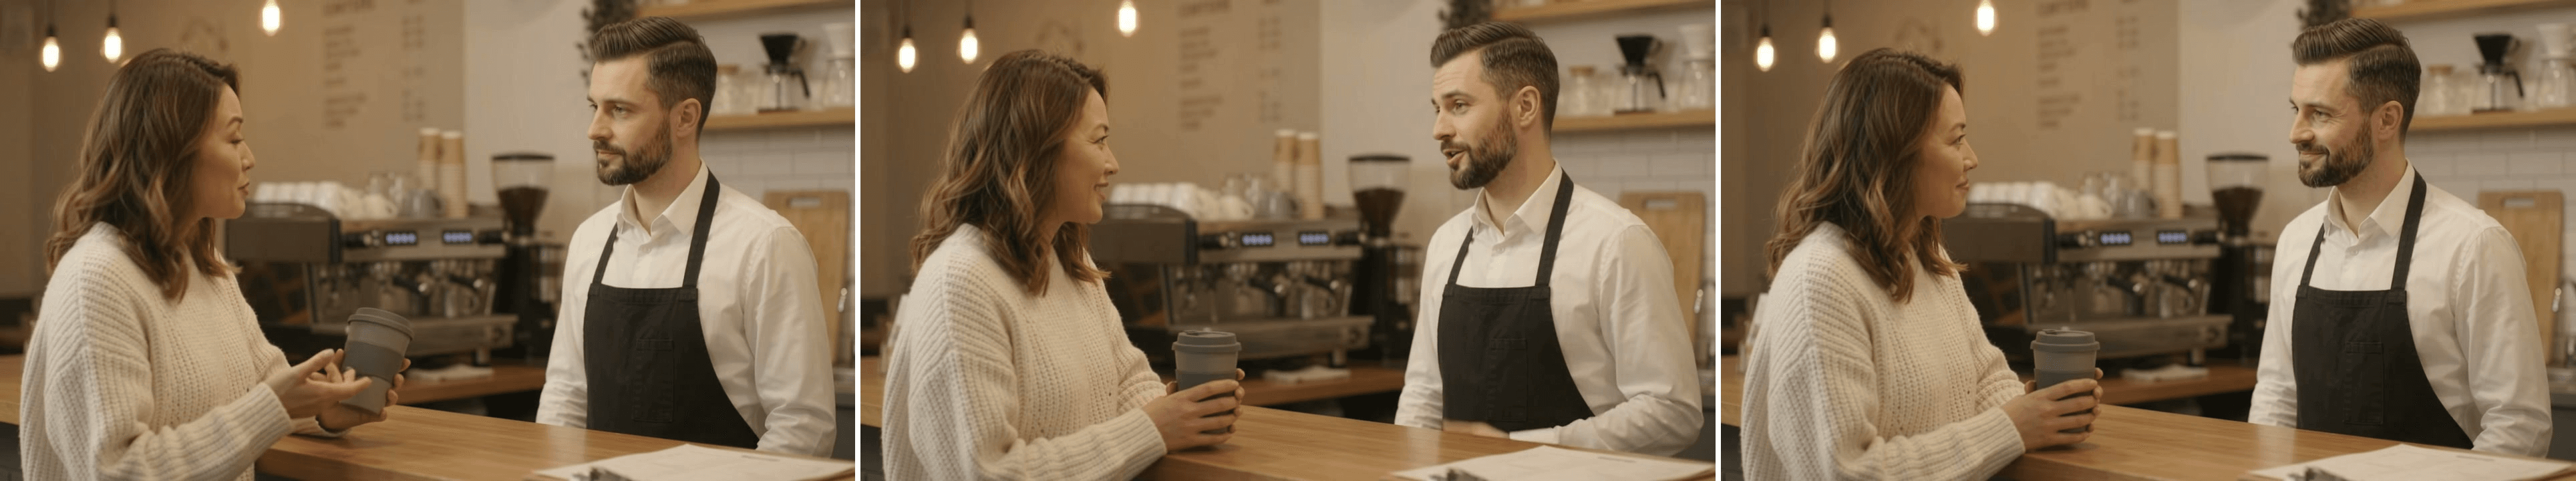 Case B frames, left to right (about 0:02, 0:08, 0:13 of the combined video): the customer shows her cup; the café worker appears to answer; they face each other at the close.
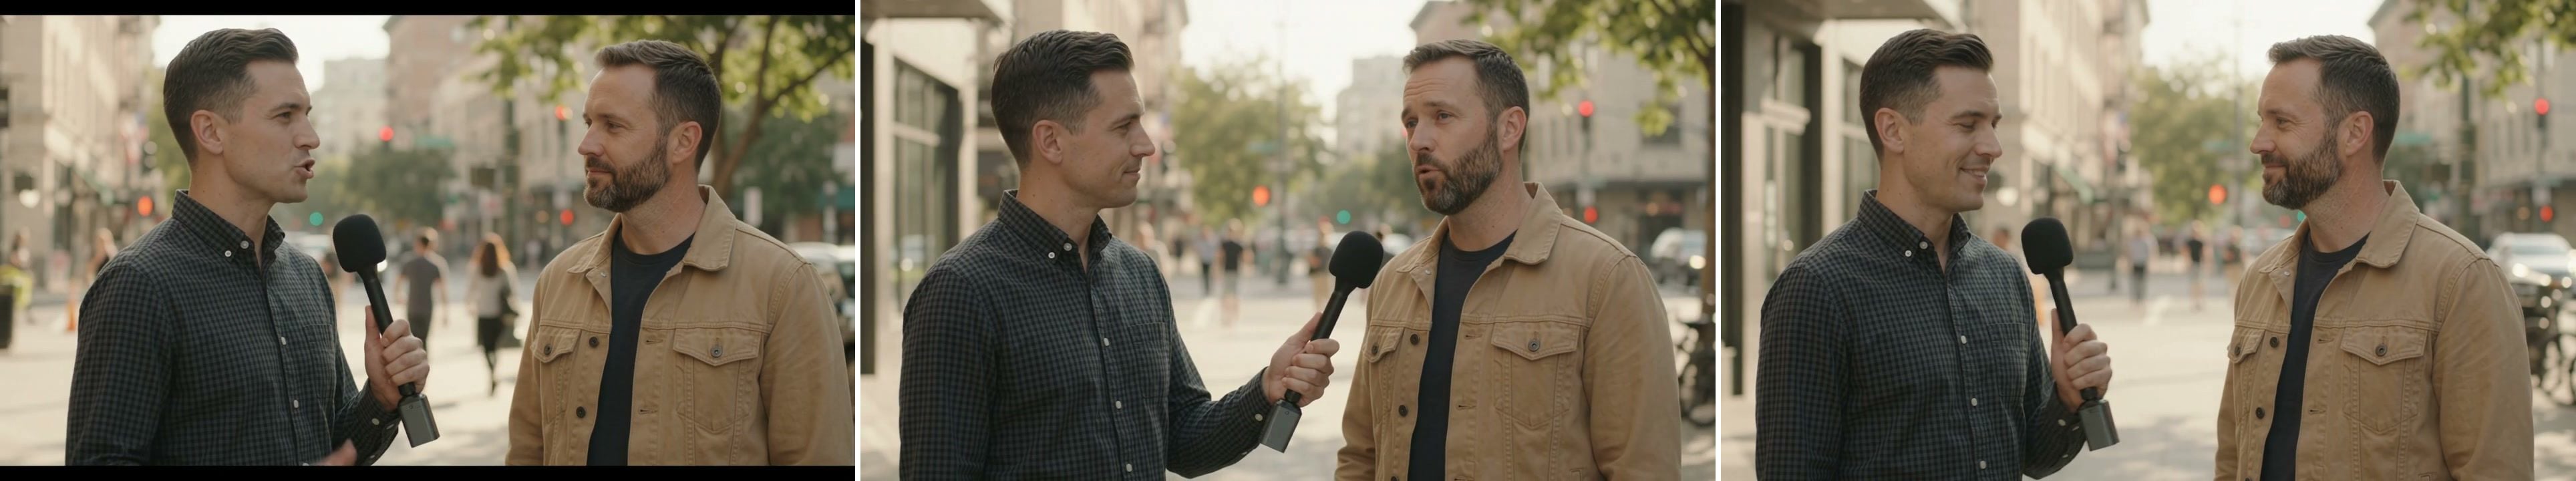
Case C frames, left to right (about 0:16, 0:19, 0:26 of the combined video): the interviewer holds the microphone; he turns it toward the interviewee; both face each other at the end.
Check Speaker Order, Lip Sync, and Voice Drift Before Publishing
Review the Clip Line by Line
Download the video. Play it once without reading the script to find obvious confusion, then replay with the prompt beside it. Pause at each turn and write down what you hear. Inspect both mouths, and note speech outside the scripted turns. For a repeatable review, log the start and end time of each audible line, the expected speaker, the voice you heard, and the visible mouth that moved. Write “unclear” if a face is hidden or the sound masks a word. Do not turn an unclear cell into a pass because the rest of the scene looks convincing. A second listener who has not seen the prompt can identify who they think is speaking; compare that judgment with the script before deciding whether a public viewer will understand the scene.
Check 4 things for every line:
- Words: Were the quoted words spoken in order, without an omitted ending or added sentence?
- Voice owner: Did the named person sound like the speaker, especially when A returned?
- Visible timing: Did that person's mouth move while the listener stayed silent?
- Other content: Did the clip add a narrator, bystander, captions, logo, or music?
A timestamped quality-assurance timeline remains pending until the audio and mouth movements have been reviewed line by line.
Revise One Constraint at a Time
If the last line disappears, shorten the script or give it more duration within the 15-second cap. If the wrong character speaks, repeat the visual position and specify that the listener stays silent. If ambience covers a word, lower or remove it. If a cut hides the active mouth, return to a continuous 2-shot. Change one factor per retry so the next output answers a clear question.
None of these edits guarantees a fix. If a render needs revision, save its file, settings, and the issue you want to address. A producer can then decide whether another render is worth the cost or whether recorded voices and manual editing would give the needed precision. For a short, visibly spoken exchange, start with the office prompt and accept a clip only after the line-by-line check. That is the standard for Gemini Omni 1.2 Flash multi-speaker dialogue.
Frequently Asked Questions
Can Gemini Omni 1.2 Flash keep the same voices across separate clips?
A voice staying recognizable within one generated clip is a narrower requirement than preserving it across separate generations. These text-only examples test the first case. Do not promise cross-clip voice identity from them. A campaign needing one recurring speaker should run a separate continuity test.
Can Gemini Omni 1.2 Flash generate dialogue in languages other than English?
The model may produce other languages, but these prompts are in English. Review the target language word by word with a fluent listener, including names, numbers, and localized claims. Another creator's successful language test is evidence for that test, not a guarantee for your script.
How do I keep each line assigned to the right speaker?
Give each person a visual position and voice, label every quoted line, and specify who stays silent during the other person's turn. Review the generated video line by line. If a render does not meet the brief, shorten the exchange or use a controlled audio workflow for exact delivery.
How many dialogue turns fit in a 15-second Gemini Omni 1.2 Flash clip?
The café prompt requests eight brief turns in 15 seconds, while the office and street prompts request five turns in 12 seconds. These are script examples, not guaranteed limits. Read the lines aloud, allow for pauses, and shorten them if the last turn reaches the end of the clip.
Does Gemini Omni 1.2 Flash need a reference image for two-speaker dialogue?
No reference image is used in these three text-to-video prompts. They describe each speaker's position, clothing, and voice in text. If a project needs a specific face or visual style, test a route that accepts references and review its output separately.


