


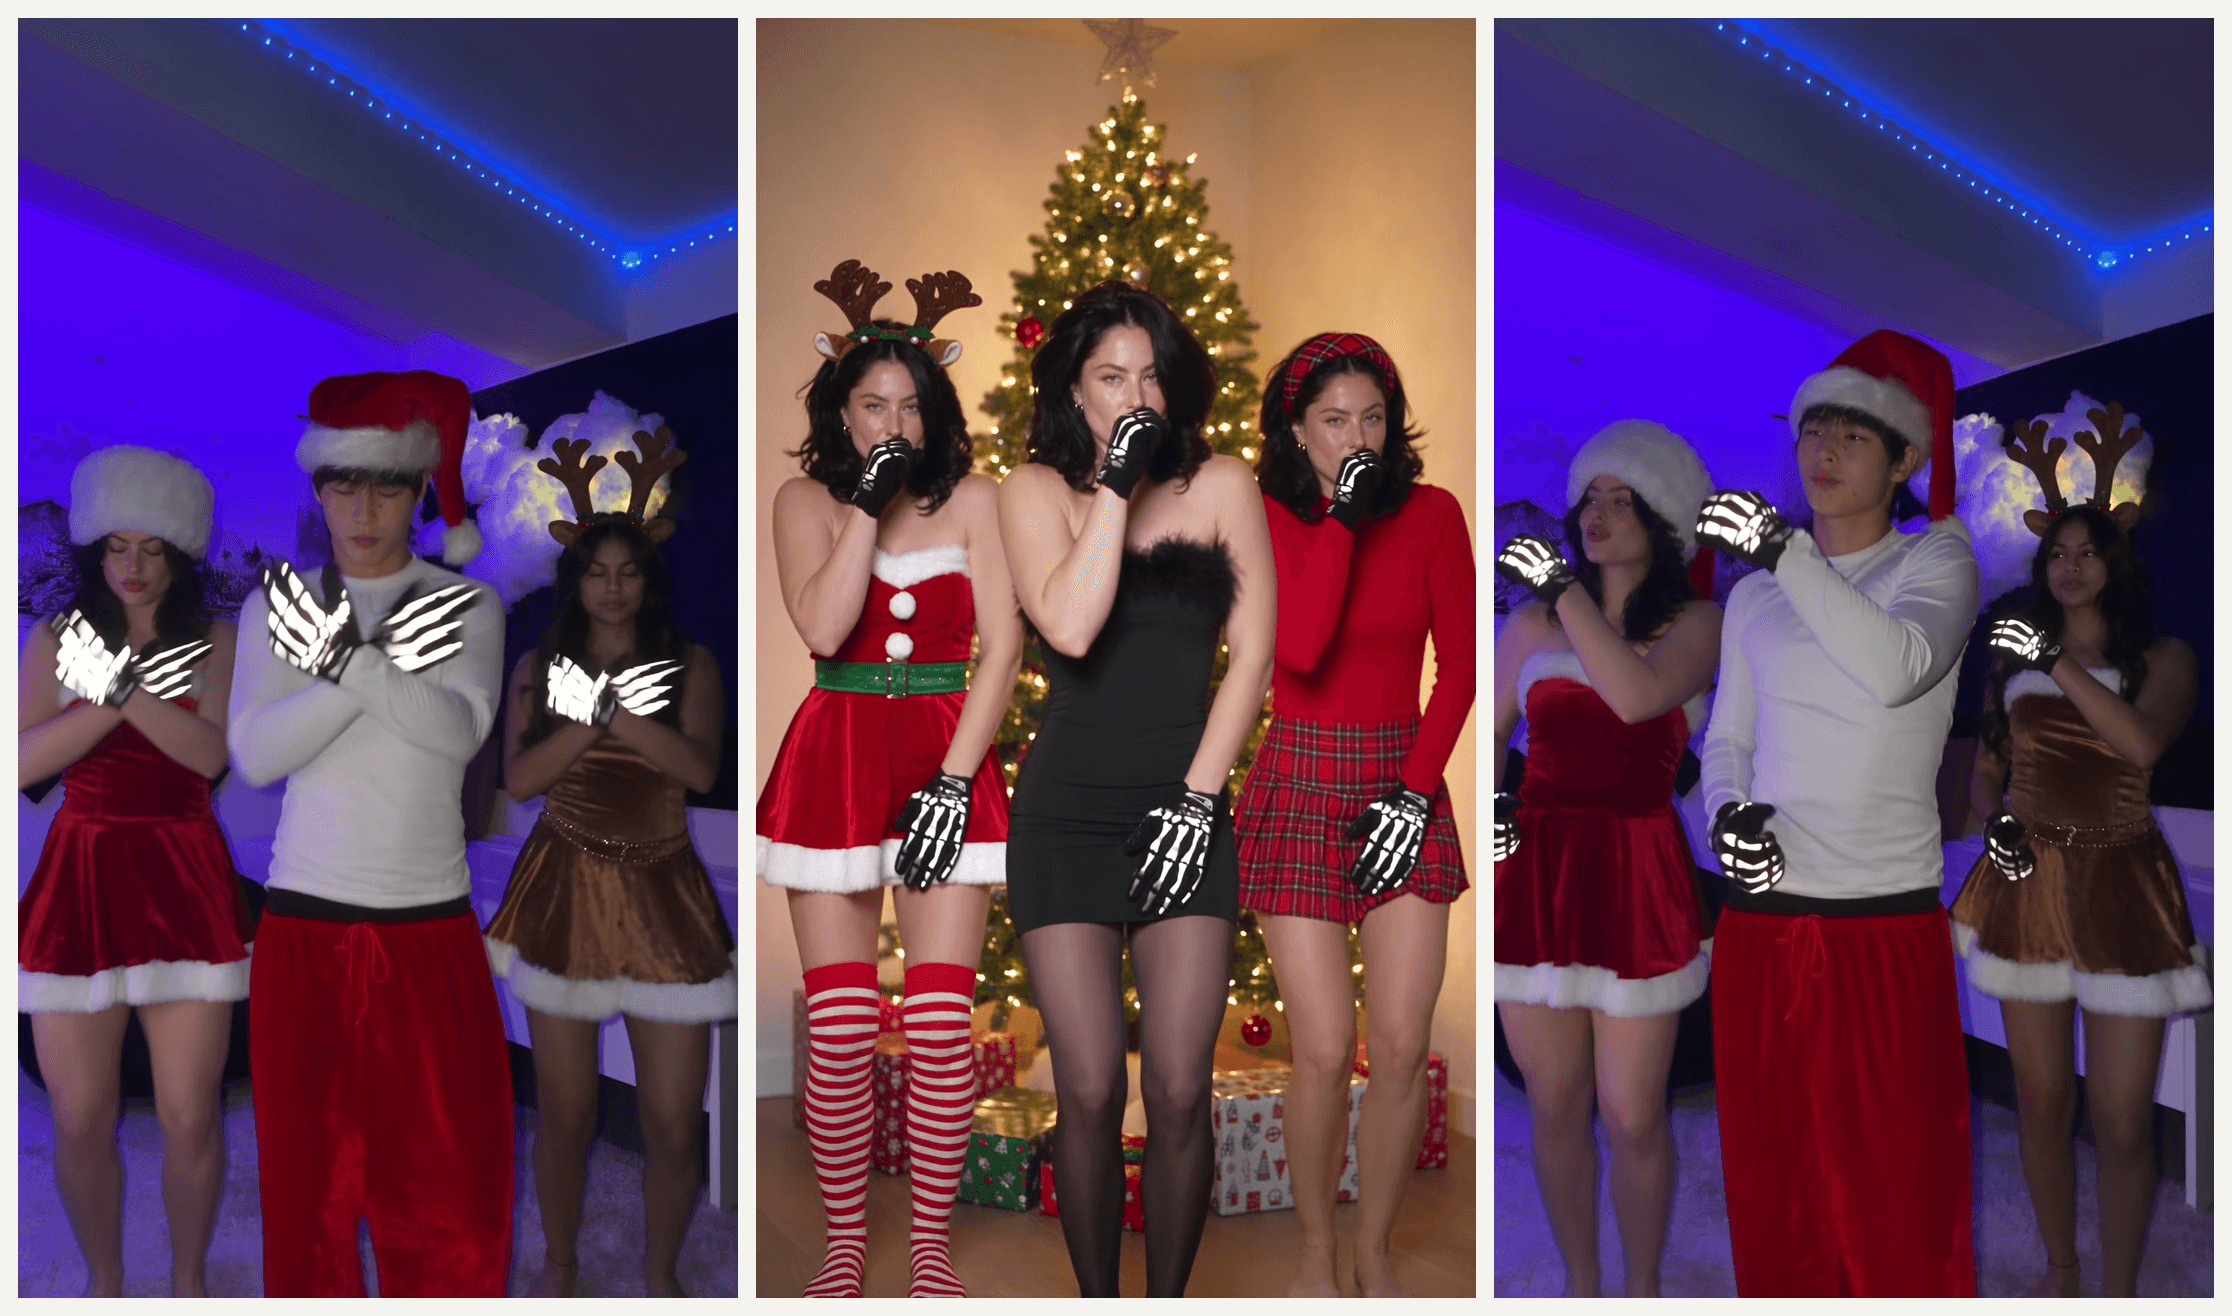
三个戴圣诞帽的人站成一排,什么也不做。双手交握,面无表情,整整三秒。然后,巴西 funk 节拍叠在 Jingle Bell Rock 上,三个人同时猛地将双臂交叉在胸前。
这就是 Jingle Bell Brazil 舞蹈,一套在 2026 年 11 月第二周席卷 TikTok 的圣诞舞步套路。
我们用 Seedance 2.5 重建了两次:一次用三个不同的人,一次用一张照片变成三胞胎。两次生成都保留了定格、交叉手臂和踩拍拍胸。下面是声音的来源、动作、单照片帖子背后的 CapCut 模板,以及我们的确切提示词。
关键要点
- Jingle Bell x Brazil 舞蹈是一套 15 秒的排舞,配乐是 Jingle Bell Rock 的巴西 funk 混音。
- 许多翻拍和 AI 模板都模仿同一个视频:三名戴面具的舞者,戴圣诞帽和骷髅手套,发布于 2026 年 11 月 9 日。
- 在三秒定格后,整套动作由四个动作组成:交叉手臂、拳头抵嘴、拍胸、换手臂。
- TikTok 上的单照片 AI 帖子可追溯到名为“trend video”的 CapCut 模板。
- 在 Atlas Cloud AI 视频生成器 中,Seedance 2.5 用你的照片和你自己的服装重新演绎这套动作。_
什么是 Jingle Bell x Brazil 舞蹈潮流?
这是一套适合两到三人的短排舞。所有人面朝镜头站成一排,中间的人向前站一步,节拍落下之前没人动。整段动作 15 秒内完成,用一部固定不动的手机拍摄。
引人注目的是它的速度。我们查看时,这个声音才发布了十一天。
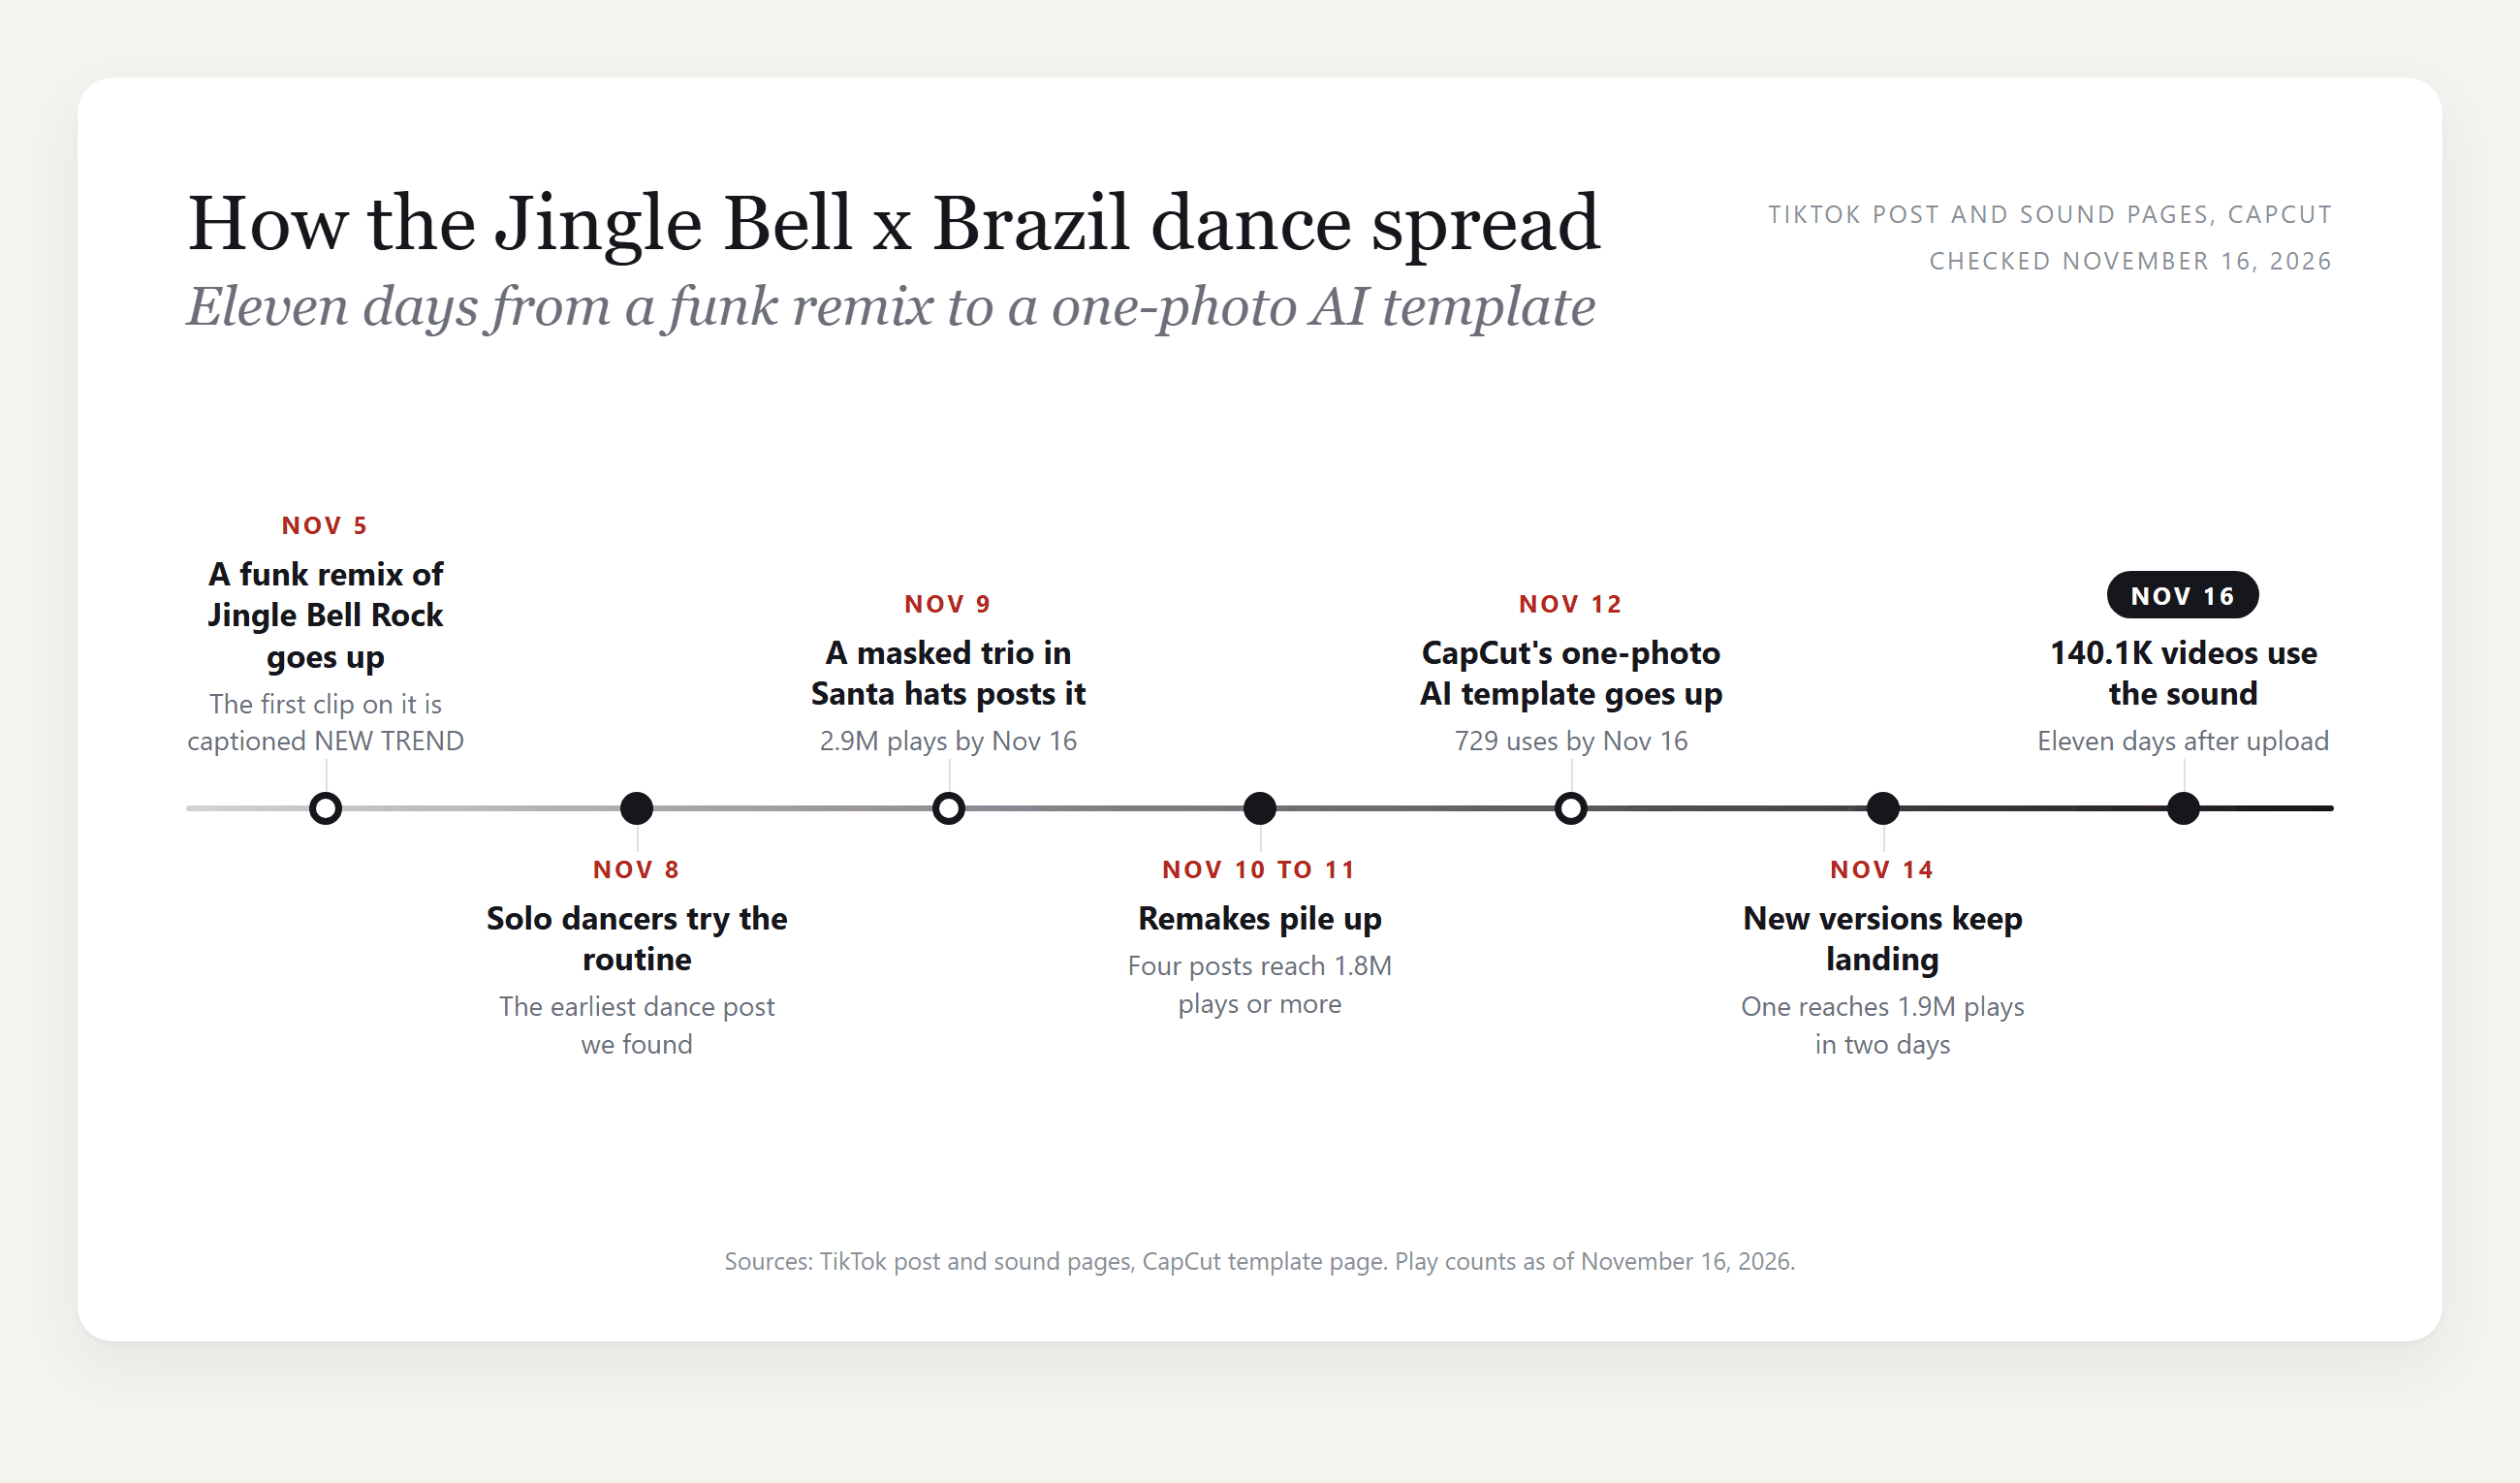
混音于 11 月 5 日上线,到 11 月 16 日,声音页面显示有 140,100 条视频。许多翻拍模仿的那个片段在上传四天后出现:三名戴面具的舞者,戴圣诞帽、穿白色上衣、红色运动裤和骷髅印花手套,在蓝色 LED 灯带下排成一排。
截至 11 月 16 日,那条帖子有 290 万次播放。11 月 9 日至 14 日间,该声音下至少有十条帖子各自超过 10,000 次收藏,说明人们打算学会它。
Jingle Bell Brazil 歌曲:Jingle Bell Rock 的 funk 混音
搜索 jingle bell x brazil,你会找到三种不同的东西。只有第一种是这支舞。
| 潮流声音 | 较早的梗 | 健身版 | |
|---|---|---|---|
| 是什么 | Jingle Bell Rock 的巴西 funk 混音,TikTok 上标注为 DJ Paul Bigata | MC Teteu 对 Jingle Bell 的 funk 演绎,常以“Brazilian Jingle Bell kid”传播 | 配合其他 Jingle Bells 混音的舞蹈健身操 |
| 出现时间 | 2026 年 11 月 5 日 | 2019 年 12 月发布,2023 年 6 月在 TikTok 重新流行 | 在潮流出现前上传到 YouTube 和 Facebook |
| 人们发布什么 | 本指南中的排舞 | 跟唱片段和剪辑 | 三分钟或更长的全套动作 |
较早的梗有自己的 Know Your Meme 条目,常在圣诞前后重新出现。要把你的视频归到这支舞下,选择名称中带有 Jingle Bell Rock Brazil 的混音。
如何在 Atlas Cloud 上制作 Jingle Bell Brazil 舞蹈 AI 视频
下面是我们三人版的生成:中间一名男子,两侧各一名穿天鹅绒圣诞裙的女子,还有原版中发光的骷髅手套。
Atlas Cloud 运行 Seedance 2.5,这是字节跳动的视频模型,可在同一请求中接收参考照片和参考视频。你在提示词中给每个参考打标签,因此舞蹈来自片段,演员来自你的照片。房间、服装以及谁站在中间都由你写。
方法 1:在视频生成器中用三张照片选角
登录,打开 视频生成器,按照截图中的数字操作。
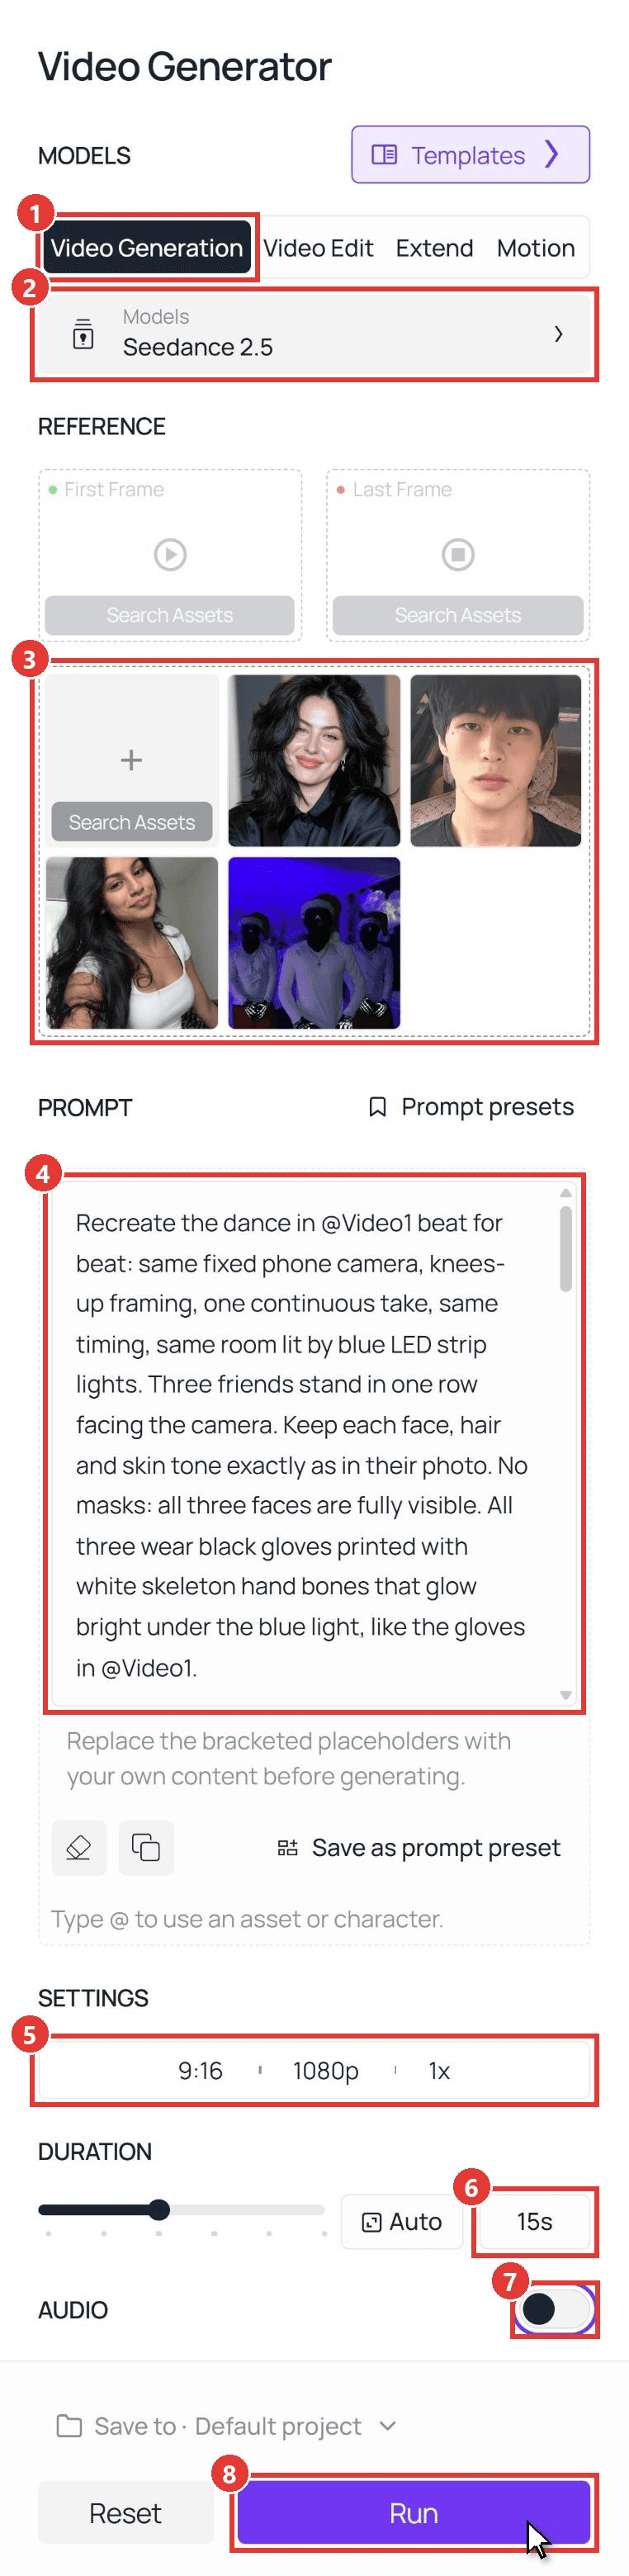
- 点击 视频生成 标签页。
- 将模型保持为 Seedance 2.5。
- 在首帧和尾帧下方的框中(为空时显示 上传其他参考),加入你的三张照片,然后加入一段静音的音乐版动作片段。上传顺序决定标签:照片成为 @Image1、@Image2 和 @Image3,片段成为 @Video1。半身照就足够。
- 粘贴提示词。我们的提示词:
plaintext1Recreate the dance in @Video1 beat for beat: same fixed phone camera, knees-up framing, one continuous take, same timing, same room lit by blue LED strip lights. Three friends stand in one row facing the camera. Keep each face, hair and skin tone exactly as in their photo. No masks: all three faces are fully visible. All three wear black gloves printed with white skeleton hand bones that glow bright under the blue light, like the gloves in @Video1. 2 3The man from @Image2 stands in the middle, one step in front. He is tall and athletic, with broad shoulders and a flat, wide chest, a full head taller than the two women. He wears a red Santa hat, a fitted white long-sleeve top and loose red sweatpants. 4 5The woman from @Image1 stands on the left. She has a slim feminine figure and is clearly smaller than the man. She wears a red velvet strapless mini dress trimmed with white fur at the top and hem, and a round white fur hat. 6 7The woman from @Image3 stands on the right. She has a slim feminine figure and is clearly smaller than the man. She wears a brown velvet strapless mini dress trimmed with white fur at the top and hem, a thin belt at the waist, and a reindeer antler headband. 8 9[0-3.5s] The tall man in the white top, the woman in the red dress and the woman in the brown reindeer dress all stand still, gloved hands clasped low in front of the hips, calm straight faces, looking into the lens. 10[3.5-7s] On the beat all three cross both forearms over the chest, then bring the right fist up to the mouth while the left hand drops to the hip, knees bouncing lightly. The skeleton gloves flash as they move. 11[7-11s] All three swing one forearm across the chest and tap it, switch arms, tap again, small bounce on every beat, shoulders loose. 12[11-15s] They repeat the arm cross, fist to mouth and chest tap a little bigger, still bouncing, and hold the last arm cross on the final beat. 13 14The three move together but not like copies: tiny differences in timing and arm height, like friends filming for fun. Each body keeps its own build from start to finish: the man stays tall and broad, the two women stay slim and smaller. Both dresses stay in place the whole time, hems at mid-thigh. Exactly three people in every frame. Each gloved hand has five fingers and stays in front of the torso. Nobody holds a phone. 15 16No music, no singing, no lyrics: only quiet room sound.
- 打开设置栏,选择 9:16 和 1080p。
- 将时长设为 15 秒,即这套动作的长度。
- 让 音频 保持关闭。发布时在 TikTok 里加上声音。
- 点击 运行。
在我们的生成中,两个细节起了主要作用。每位舞者都有一段描述体型和服装的文字,之后每一句都通过那套服装来指代他们。我们的参考片段是去掉音乐的 15 秒动作,因此模型只读取动作,不读取其他东西。
想了解更多像这样写分秒台词的方法,请参阅我们的 Seedance 2.5 提示词指南。
用一张照片制作 Jingle Bell Brazil 舞蹈:三个你
这周没有两个朋友有空?一张照片就能填满整排。我们上传了一张单人肖像和同一个舞蹈片段,并要求生成穿三套不同圣诞服装的三胞胎。
与 方法 1 步骤相同,只需在上传其他参考下放一张照片和该片段:
plaintext1Recreate the dance in @Video1 beat for beat: same fixed phone camera, knees-up framing, one continuous take, same timing. The woman from @Image1 appears three times as identical triplets, standing in one row facing the camera in a cozy living room with a lit Christmas tree behind them. All three have exactly her face, hair and skin tone from the photo, and the same slim feminine figure. Each triplet wears a different outfit, and the outfits never swap or blend. All three wear black gloves printed with white skeleton hand bones, like the gloves in @Video1. 2 3The triplet in the black dress stands in the middle, one step in front. She wears a fitted black strapless mini dress with a band of black faux fur across the top, and sheer black tights. 4 5The triplet in the red velvet dress stands on the left. She wears a red velvet strapless skater dress with white fur trim at the top and hem, a thin green belt, a reindeer antler headband, and red-and-white striped over-the-knee socks. 6 7The triplet in the red plaid skirt stands on the right. She wears a red long-sleeve top, a red plaid mini skirt and a matching red plaid headband. 8 9[0-3.5s] The triplet in the black dress, the triplet in the red velvet dress and the triplet in the red plaid skirt all stand still, gloved hands clasped low in front of the hips, straight faces, looking into the lens. 10[3.5-7s] On the beat all three cross both forearms over the chest, then bring the right fist up to the mouth while the left hand drops to the hip, knees bouncing lightly. 11[7-11s] All three swing one forearm across the chest and tap it, switch arms, tap again, small bounce on every beat, shoulders loose. 12[11-15s] They repeat the arm cross, fist to mouth and chest tap a little bigger. The triplet in the red velvet dress cracks a small smile; the other two stay straight-faced. They hold the last arm cross on the final beat. 13 14Exactly three people in every frame, never a fourth. Tiny differences in timing between the three, not perfect copies. All dresses and the skirt stay in place the whole time, hems at mid-thigh. Each gloved hand has five fingers and stays in front of the torso. Nobody holds a phone. 15 16No music, no singing, no lyrics: only quiet room sound.
同一张脸在画面中出现三次时,服装就是区分舞者的关键。在我们的生成中,三套剪裁和面料不同的服装在整整 15 秒里都保持了各自的位置。
方法 2:通过 API 提交 Jingle Bell Brazil 舞蹈
正在构建一个把上传内容变成这套动作的节日功能?同一个模型就在一个端点背后。
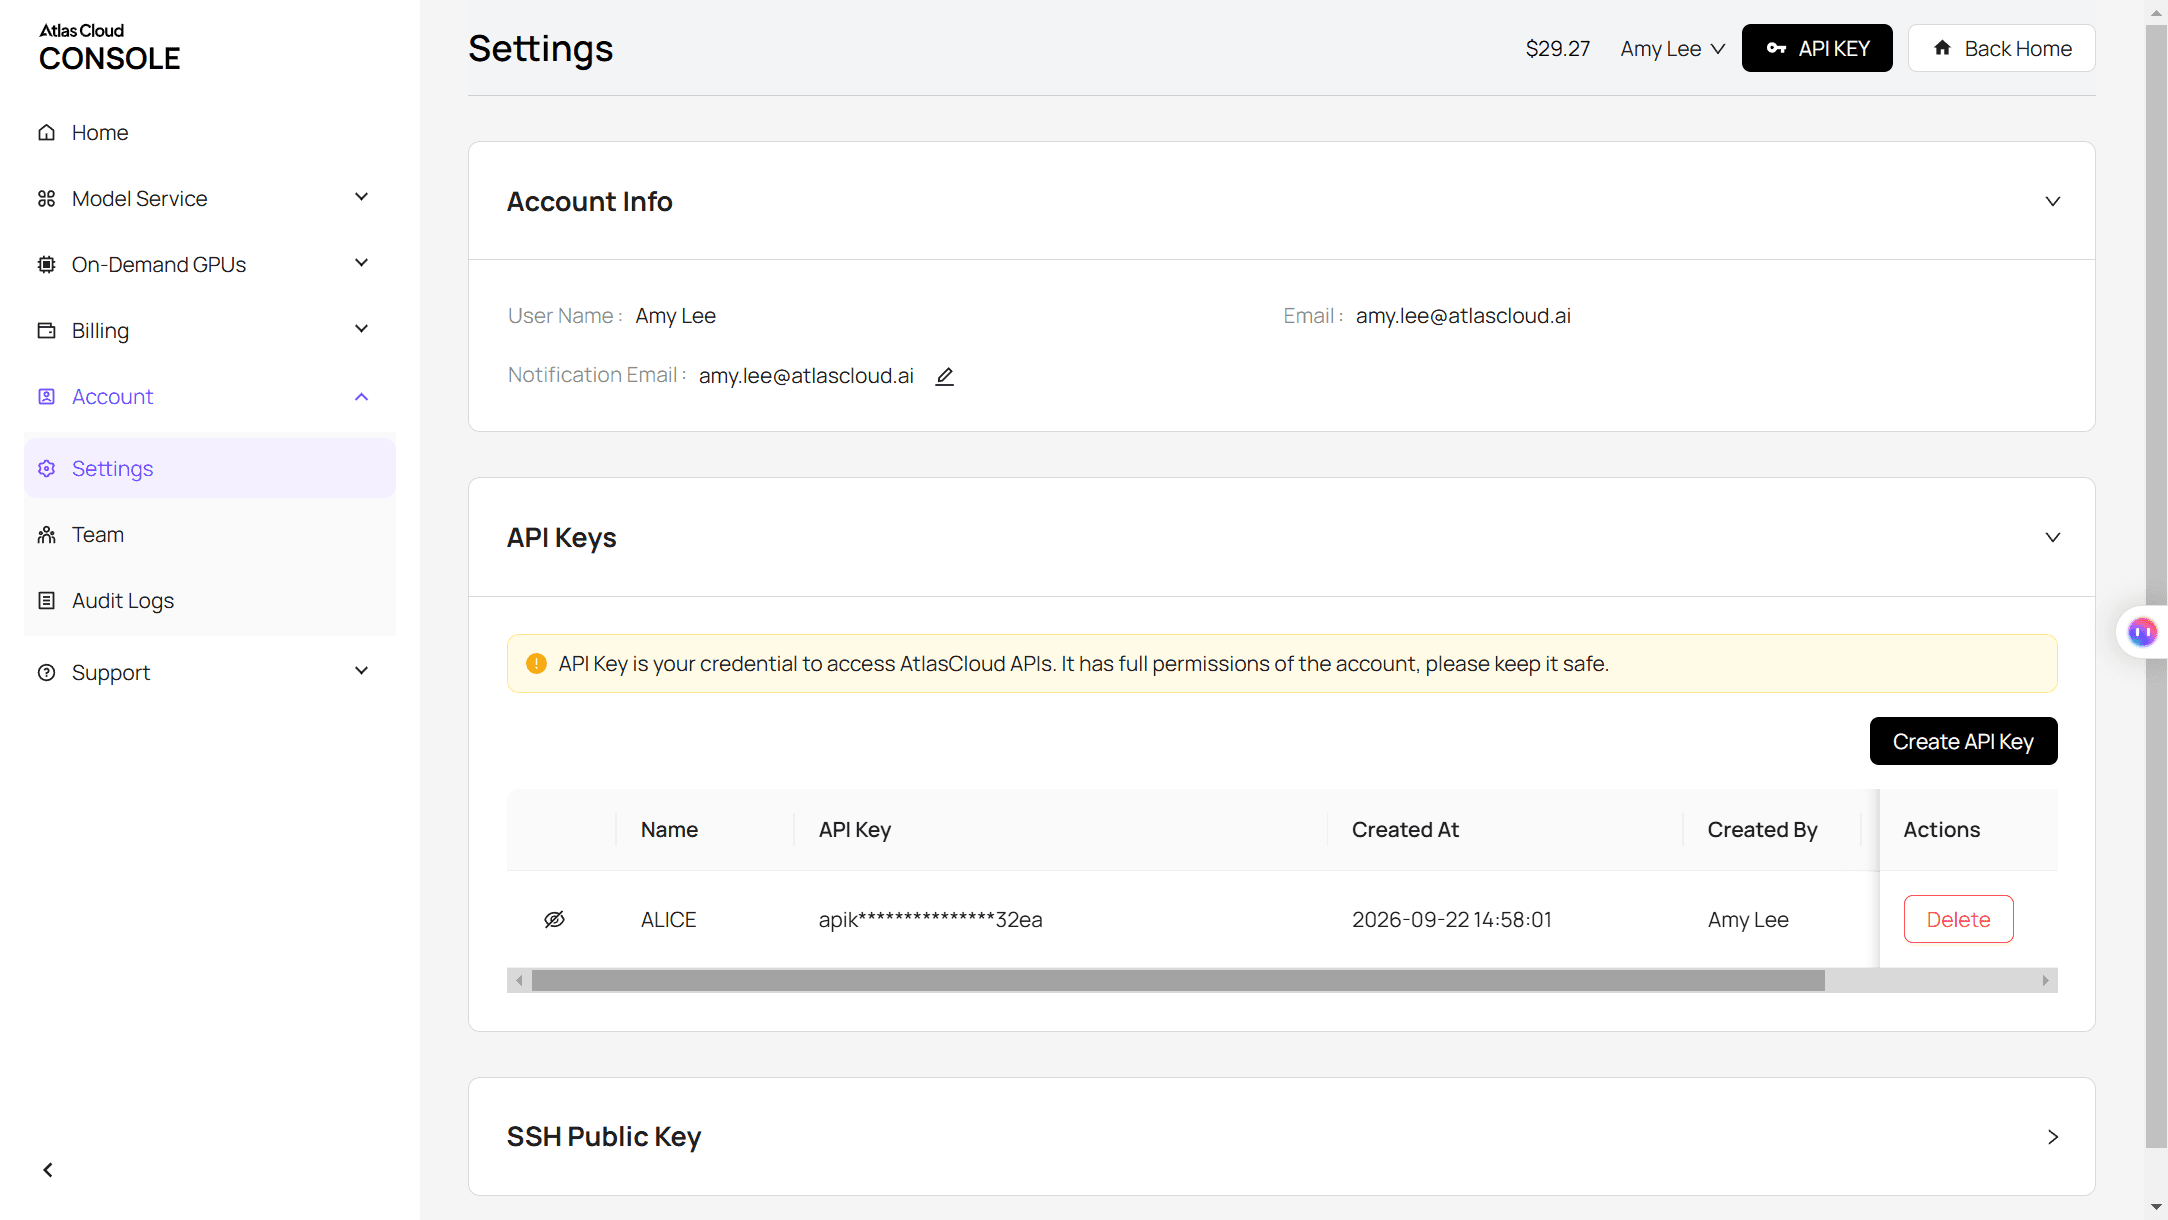
步骤 1:创建并复制 API 密钥。 在 Atlas Cloud 控制台打开设置,点击创建 API 密钥,并立即复制;之后列表会将其掩码。
步骤 2:检查请求格式。 API 文档 列出了 Seedance 2.5 Reference-to-Video 的每个字段,这是视频生成标签页在你添加参考文件时调用的模型。
步骤 3:提交任务并轮询结果。 按提示词给它们打标签的顺序,将照片 URL 放入 reference_images,并将舞蹈片段放入 reference_videos:
plaintext1curl -X POST https://api.atlascloud.ai/api/v1/model/generateVideo \ 2 -H "Authorization: Bearer $ATLASCLOUD_API_KEY" \ 3 -H "Content-Type: application/json" \ 4 -d '{ 5 "model": "bytedance/seedance-2.5/reference-to-video", 6 "reference_images": [ 7 "https://your-cdn.com/dancer-1.jpg", 8 "https://your-cdn.com/dancer-2.jpg", 9 "https://your-cdn.com/dancer-3.jpg" 10 ], 11 "reference_videos": [ 12 "https://your-cdn.com/dance-clip-muted.mp4" 13 ], 14 "prompt": "Recreate the dance in @Video1 beat for beat... (paste the full Method 1 prompt)", 15 "duration": 15, 16 "resolution": "1080p", 17 "ratio": "9:16", 18 "generate_audio": false 19 }'
响应会返回一个 prediction ID。轮询它,直到状态显示 completed,且片段 URL 出现在 outputs 数组中:
plaintext1curl https://api.atlascloud.ai/api/v1/model/prediction/<prediction_id> \ 2 -H "Authorization: Bearer $ATLASCLOUD_API_KEY"
Atlas Cloud 上的视频模型共用这个端点、密钥和轮询循环。替换模型字符串及其字段,同一段代码就能运行另一个模型。
Jingle Bell Brazil 舞蹈教程:逐拍动作
要和朋友们实拍?这套动作就是一次定格加四个动作。这些画面来自我们的 AI 三人组。
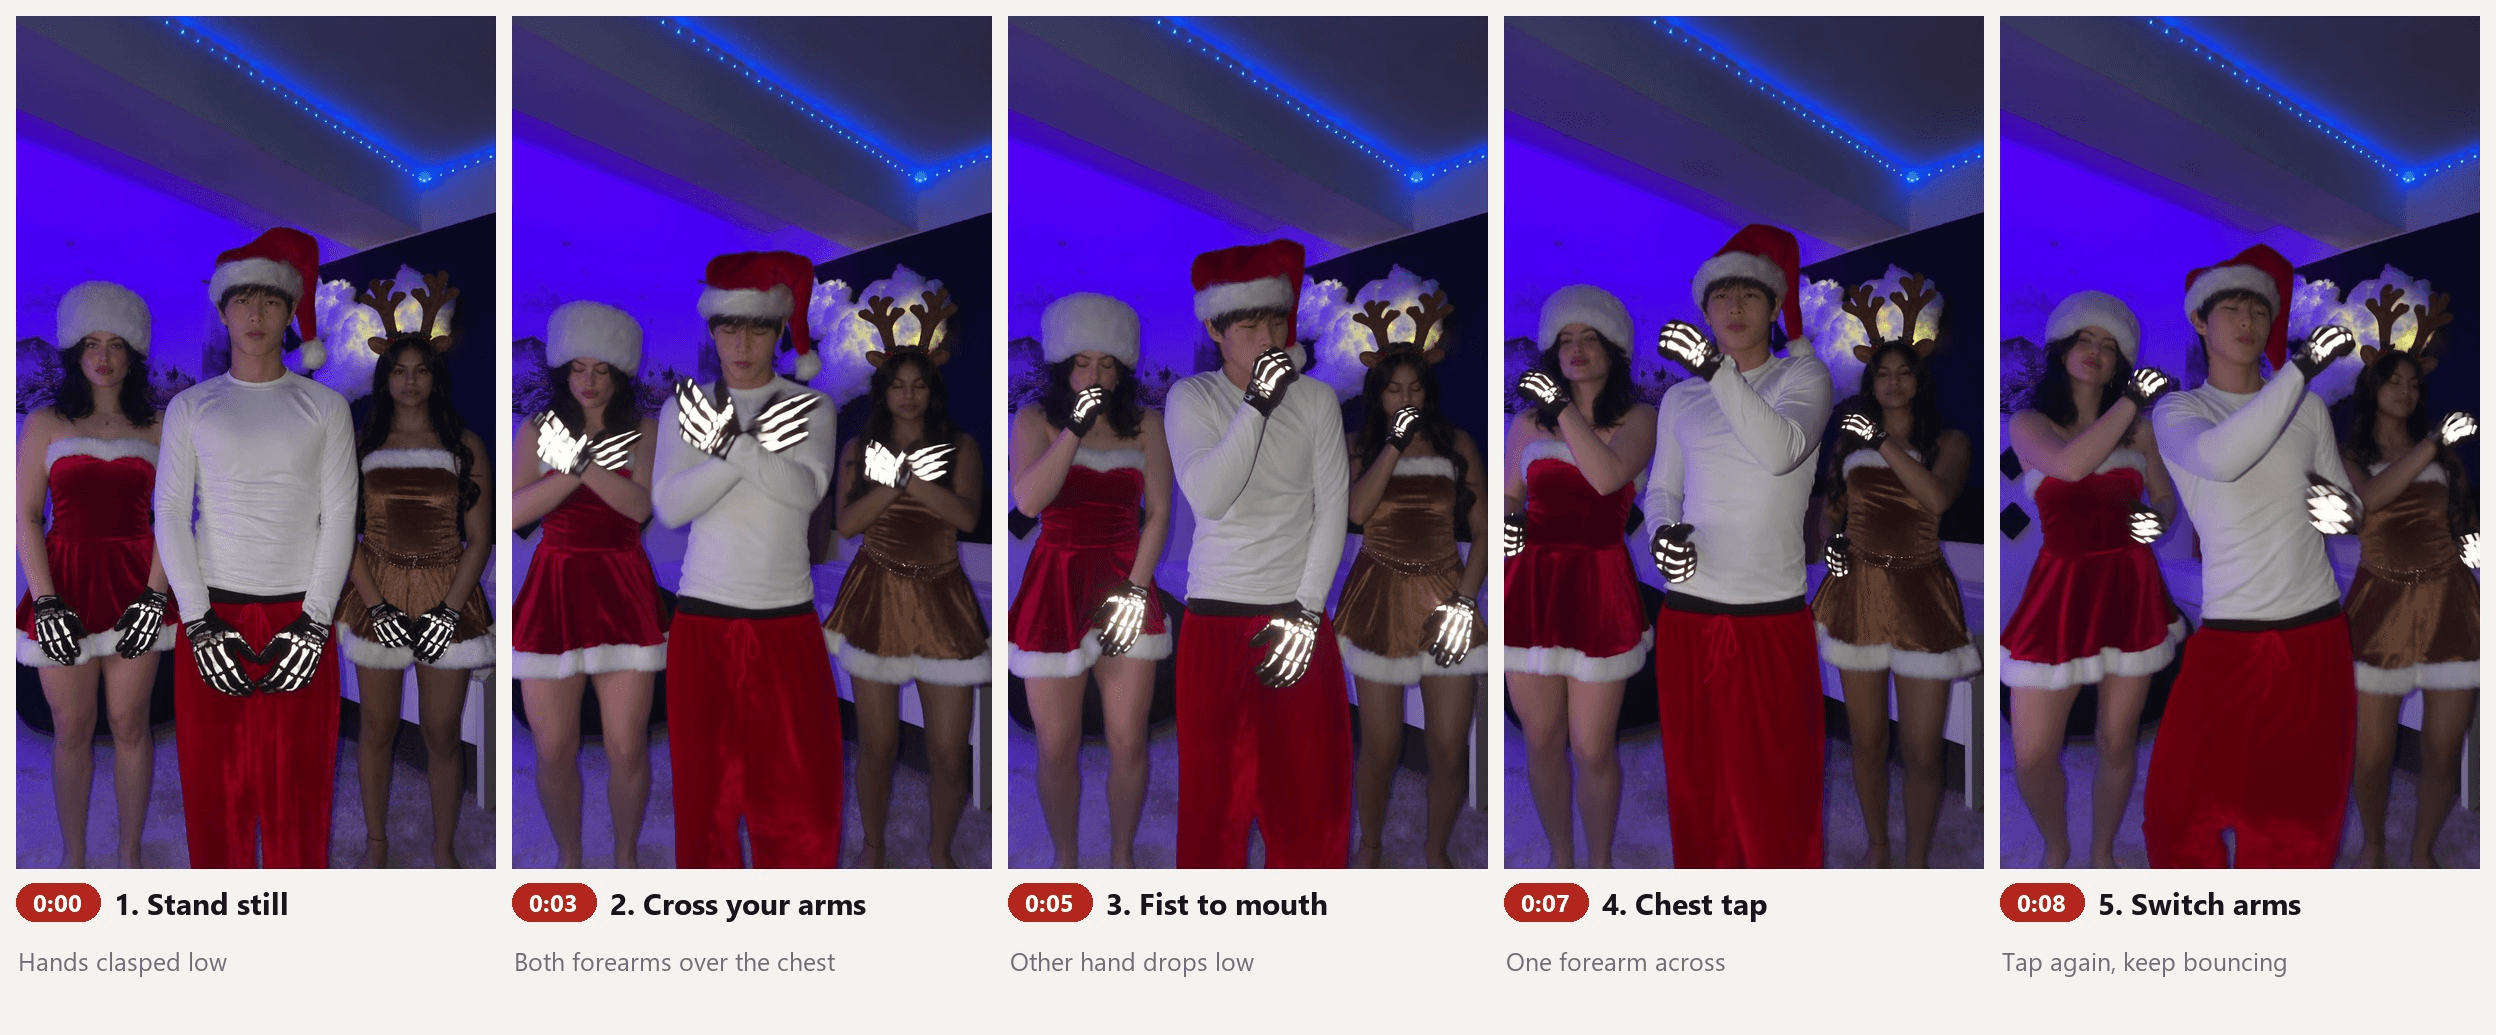
- 站定不动。 双手在胯前交握,面无表情,眼睛看向镜头。保持约三秒。
- 交叉手臂。 节拍落下时,将两条前臂猛地交叉成 X 放在胸前。
- 拳头抵嘴。 将一只拳头举到嘴边,另一只手落到胯部。
- 拍胸。 将一侧前臂横摆过胸前并轻拍,每一拍膝盖轻弹一下。
- 换手臂。 用另一只手臂拍胸,然后重复动作二到四,直到片段结束。
定格就是笑点,所以不要缩短它。把手机支在胸部高度,让每个人都以膝盖以上入镜,并让最高或最自信的舞者站在中间。如果你喜欢为三人设计的动作,花栗鼠舞 加入了旋转和换位。
哪个 CapCut 模板能制作 Jingle Bell Brazil 舞蹈?
配文为“你只需要一张照片”的 TikTok 帖子带有 CapCut 链接,我们打开的那些都指向同一个模板。模板名为“trend video”,于 11 月 12 日上线,也就是蒙面三人组片段出现三天后。
| 路线 | 你上传什么 | 你得到什么 | 适合谁 |
|---|---|---|---|
| CapCut 的“trend video”,作者 Future301 | 1 张照片 | 一段 14.8 秒竖版片段,截至 11 月 16 日有 729 次使用 | 今晚就用手机发布这个潮流 |
| 一键模板网站 | 1 到 3 张照片 | 一段 15 秒的蒙面三人组片段复制版,换上你的脸,并沿用其圣诞帽、白色上衣和红色运动裤 | 想要原版造型且不想写提示词 |
| 你自己的 Seedance 2.5 提示词 | 1 到 3 张照片加一段舞蹈片段 | 在你描述的房间和服装中呈现同一套动作 | 想要自己的演员、房间和服装 |
CapCut 模板可能受地区限制,我们查看时,这个模板在我们的地区无法使用。如果你看不到“试用此模板”按钮,提示词路线在浏览器中也能用。
常见问题
是谁发起了 Jingle Bell x Brazil 舞蹈?
该声音于 2026 年 11 月 5 日上传,而 11 月 9 日的蒙面三人组片段是许多翻拍遵循的版本。我们找到的最早舞蹈帖子是 11 月 8 日的单人版本,比三人组早一天。我们无法确认动作由谁编排,因此对任何单一创作者的署名都要谨慎对待。
我可以独自或两人跳 Jingle Bell Brazil 舞蹈吗?
可以。许多翻拍都是两个人,动作并不依赖第三个人。要做 AI 双人版,上传两张照片,删掉第三位舞者的段落,并将人数句改为“每帧恰好两个人”。如果你独自拍摄但想要一整排,上面的单照片三胞胎提示词就是捷径。
AI 视频会自带 Jingle Bell Brazil 歌曲吗?
我们的视频返回时是静音的,因为我们关闭了音频,并要求不要音乐。发布时在 TikTok 内添加声音:在声音库中搜索 Jingle Bell Rock Brazil。这也会把你的帖子归到潮流所在的声音页面下。如果你也制作节日静图,我们的 AI 圣诞照片潮流 指南涵盖了那部分。
在 Atlas Cloud 上,一段 15 秒的 Jingle Bell Brazil 舞蹈 AI 视频要多少钱?
截至 2026 年 11 月 17 日,用三张照片和一段 15 秒参考片段制作的 15 秒 9:16 视频,1080p 约 $10.65,720p 约 $5.41。两者都是在原价 $13.31 和 $6.76 基础上打 20% 折扣,折扣限时。参考片段的长度会计入价格。生成前,运行按钮会显示准确金额,所以先以 720p 试你的提示词。
结论
这个潮流容易学,也容易换人重制,原因相同:它是一次定格加四个手臂动作,所有人站成一排面朝一台摄像机完成。给模型一段动作片段,给每张照片打标签,写清每套服装,舞蹈就会保留下来,而演员和房间可以改变。
选三张你们一群人的照片,或一张照片加三套服装,粘贴上面的提示词。在 TikTok 里加上声音,你的 Jingle Bell Brazil 舞蹈甚至在圣诞树还没立起来之前就准备好了。




