


A payroll script that pays a night nurse for negative hours. A bakery profile with two quotes that must survive word for word. A 31,864-word meeting transcript where the launch date moves and the budget gets corrected. We gave all three to both apps on November 19, 2026, and the Claude vs ChatGPT question got a lot more specific than "which one is smarter."
Claude Opus 5.5 took the writing round, the other two ended level, and GPT-6.2 Sol finished first all three times. We wrote the pass rules before the first run. Here is how each round went, and what Claude Pro and ChatGPT Plus include this month.
Key Takeaways
- ChatGPT generates images in the app; Claude needs a connector first, and neither generates video footage now.
- Claude won our writing round, coding and long documents tied, and GPT-6.2 Sol finished first every time.
- Claude Pro pays for Fable 5.2 with credits, while ChatGPT Plus includes limited GPT-6.2 Astra.
- Claude's app reads up to 1M tokens depending on model; ChatGPT Plus caps reasoning chats at 256K.
- Run GPT-6.2 Sol bythetoken on Atlas Cloud to test the ChatGPT side first.
Claude AI vs ChatGPT at a Glance: Models and Built-In Tools in November 2026
Several top-ranked comparisons still describe GPT-5.x. Here is what each app runs on November 19, 2026, per each company's plan pages and help centers.
| ChatGPT | Claude | |
|---|---|---|
| Models on the free plan | GPT-6 Luna | Sonnet 5.5 and Haiku 5.5 |
| Models on paid plans | GPT-6 Sol in chat; GPT-6.2 Sol and GPT-6.2 Astra in Work and Codex | Adds Opus 5.5 and Fable 5.2 |
| Image generation | Built in (ChatGPT Images 2.5) | Not built in; Claude Design lays out images you supply |
| Video generation | None since the Sora app closed on April 26, 2026 | None for footage |
| Voice | Every plan, limited on Free | Every plan |
| Memory | Limited on Free, expanded on paid plans | On by default, and it can import memories from other AI apps |
| Agent mode for longer tasks | ChatGPT Work | Claude Cowork, paid plans only |
| Ads | May appear on Free and Go | Anthropic says "Claude will remain ad-free" |
So what can ChatGPT do that Claude cannot? Make a picture. Claude draws charts and SVG, but Anthropic's documentation says it "cannot generate, produce, edit, manipulate, or create images." An MCP connector closes that gap, as our test of Claude image generation shows. Claude's edge runs the other way, toward reading at length, which the long-document test below puts to work.
On raw intelligence scores, the top Claude model leads for now. The Artificial Analysis index put Claude Fable 5.2 at 65 and GPT-6.2 Astra at 62 on November 19, with Opus 5.5 at 59 and GPT-6.2 Sol at 57. Index points don't say which app writes your email better, so we ran our own tasks.
How We Tested ChatGPT vs Claude, With GPT-6.2 Sol on Atlas Cloud
Each app got its own newest everyday model. On the Claude side we used Opus 5.5, the strongest model Claude Pro includes without extra credits: at High effort in the Claude app, and as a Claude Code agent in the Claude desktop app for coding.
On the ChatGPT side we used GPT-6.2 Sol, the model ChatGPT Plus subscribers get in Work and Codex, through the Atlas Cloud API, which bills by the token. You can rerun our ChatGPT side before you pick a plan. Here is GPT-6.2 Sol's first draft for the writing task:
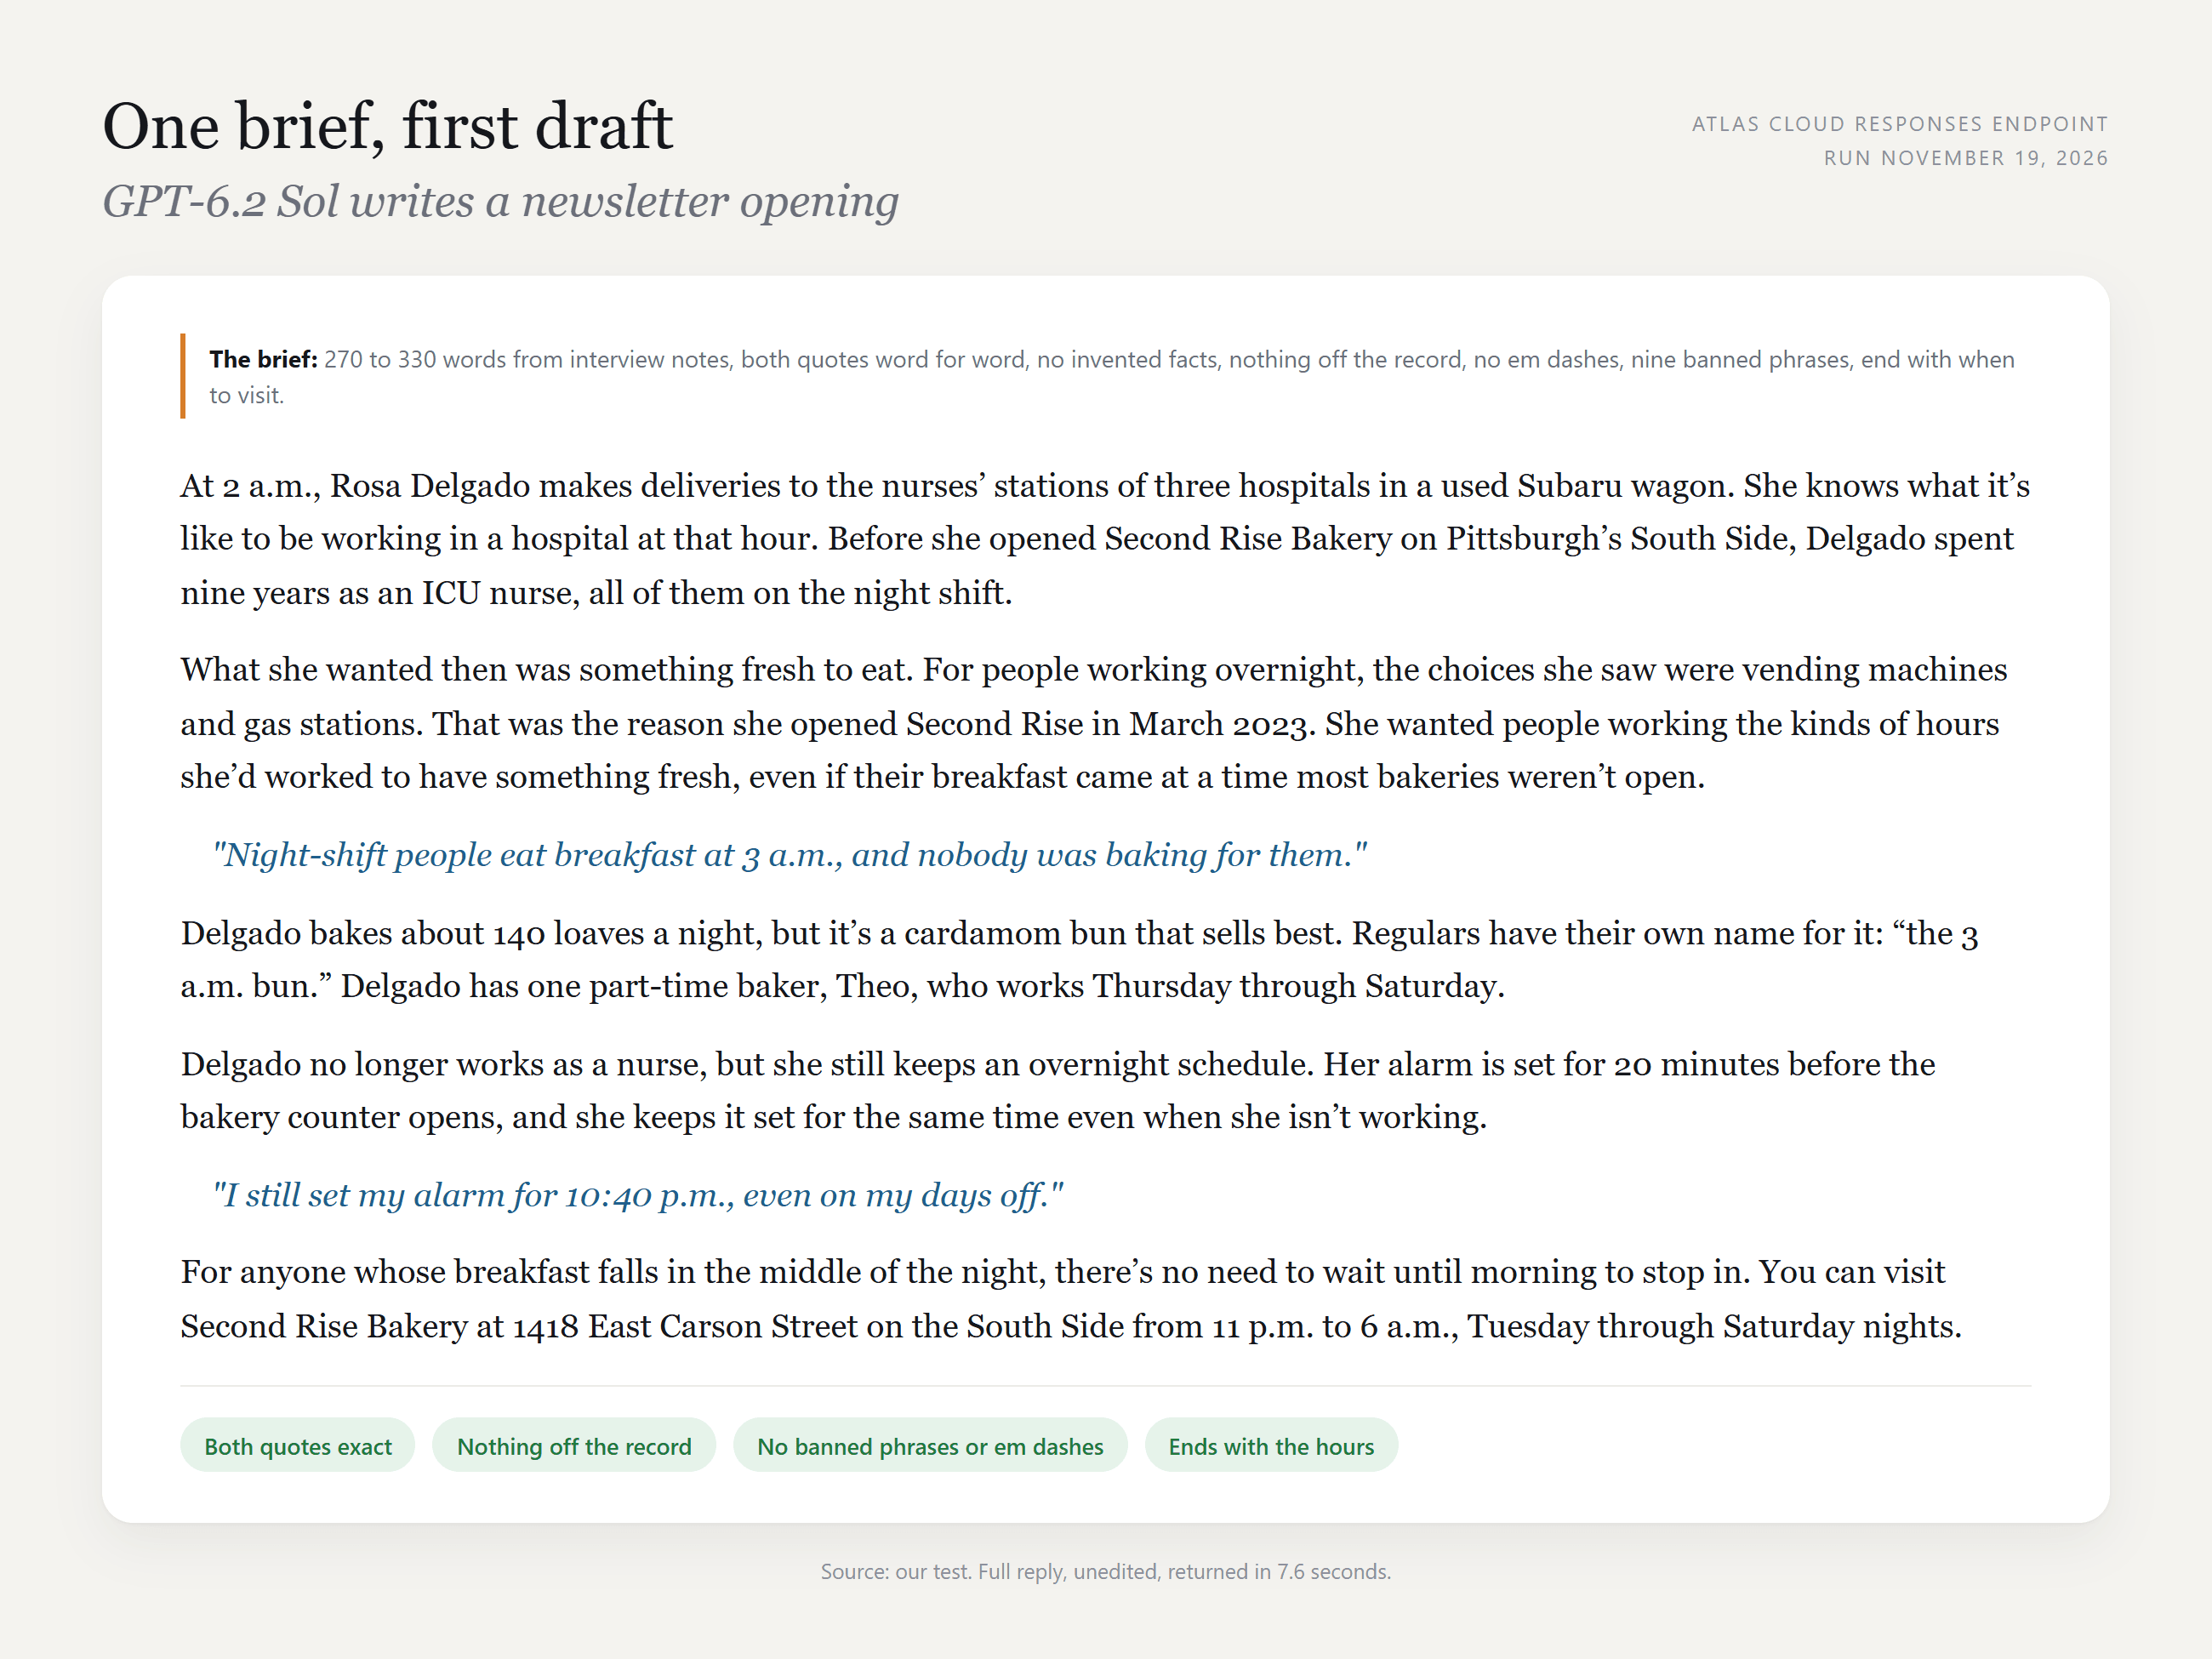
The same key reaches every ChatGPT model on Atlas Cloud, including GPT-6.2 Astra and the Codex versions.
Method 1: Run GPT-6.2 Sol in the Atlas Cloud Playground
Sign in and open the GPT-6.2 Sol playground.
- Paste the prompt below into the message box.
- Click the send arrow.
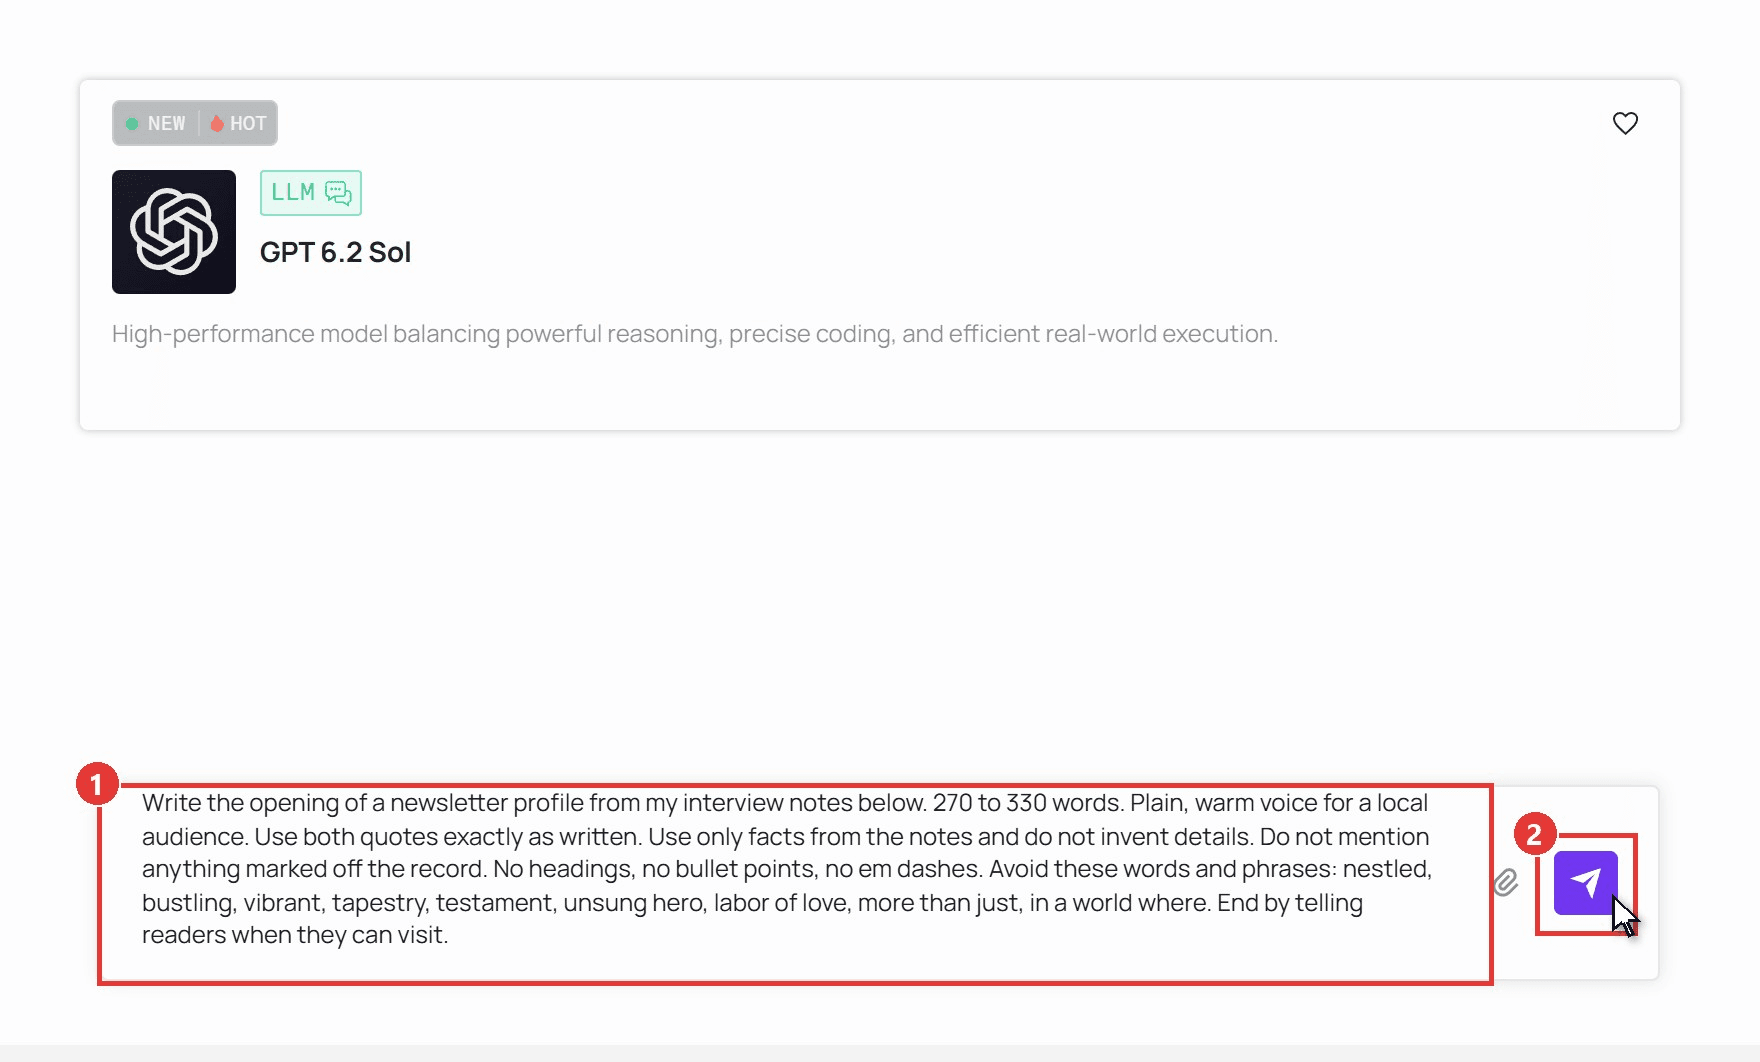
plaintext1Write the opening of a newsletter profile from my interview notes below. 270 to 330 words. Plain, warm voice for a local audience. Use both quotes exactly as written. Use only facts from the notes and do not invent details. Do not mention anything marked off the record. No headings, no bullet points, no em dashes. Avoid these words and phrases: nestled, bustling, vibrant, tapestry, testament, unsung hero, labor of love, more than just, in a world where. End by telling readers when they can visit. 2 3Interview notes: Rosa Delgado, owner of Second Rise Bakery 4- Address: 1418 East Carson Street, on Pittsburgh's South Side. 5- Opened in March 2023. 6- The counter is open from 11 p.m. to 6 a.m., Tuesday through Saturday nights. 7- Before the bakery, Rosa worked nine years as an ICU nurse, all of it on night shifts. 8- Why she opened it: night-shift workers had nothing fresh to eat, only vending machines and gas stations. 9- Bakes about 140 loaves a night. The best seller is a cardamom bun that regulars call "the 3 a.m. bun." 10- At 2 a.m. she delivers to the nurses' stations of three hospitals in a used Subaru wagon. 11- One part-time baker, Theo, works Thursday through Saturday. 12- Quote: "Night-shift people eat breakfast at 3 a.m., and nobody was baking for them." 13- Quote: "I still set my alarm for 10:40 p.m., even on my days off." 14- Off the record: she nearly closed in January 2024 after a bank loan fell through.
Method 2: Send the Same Prompt Through the API
Step 1: Create an API key. In the console, open Settings, then API Keys, and click Create API Key.
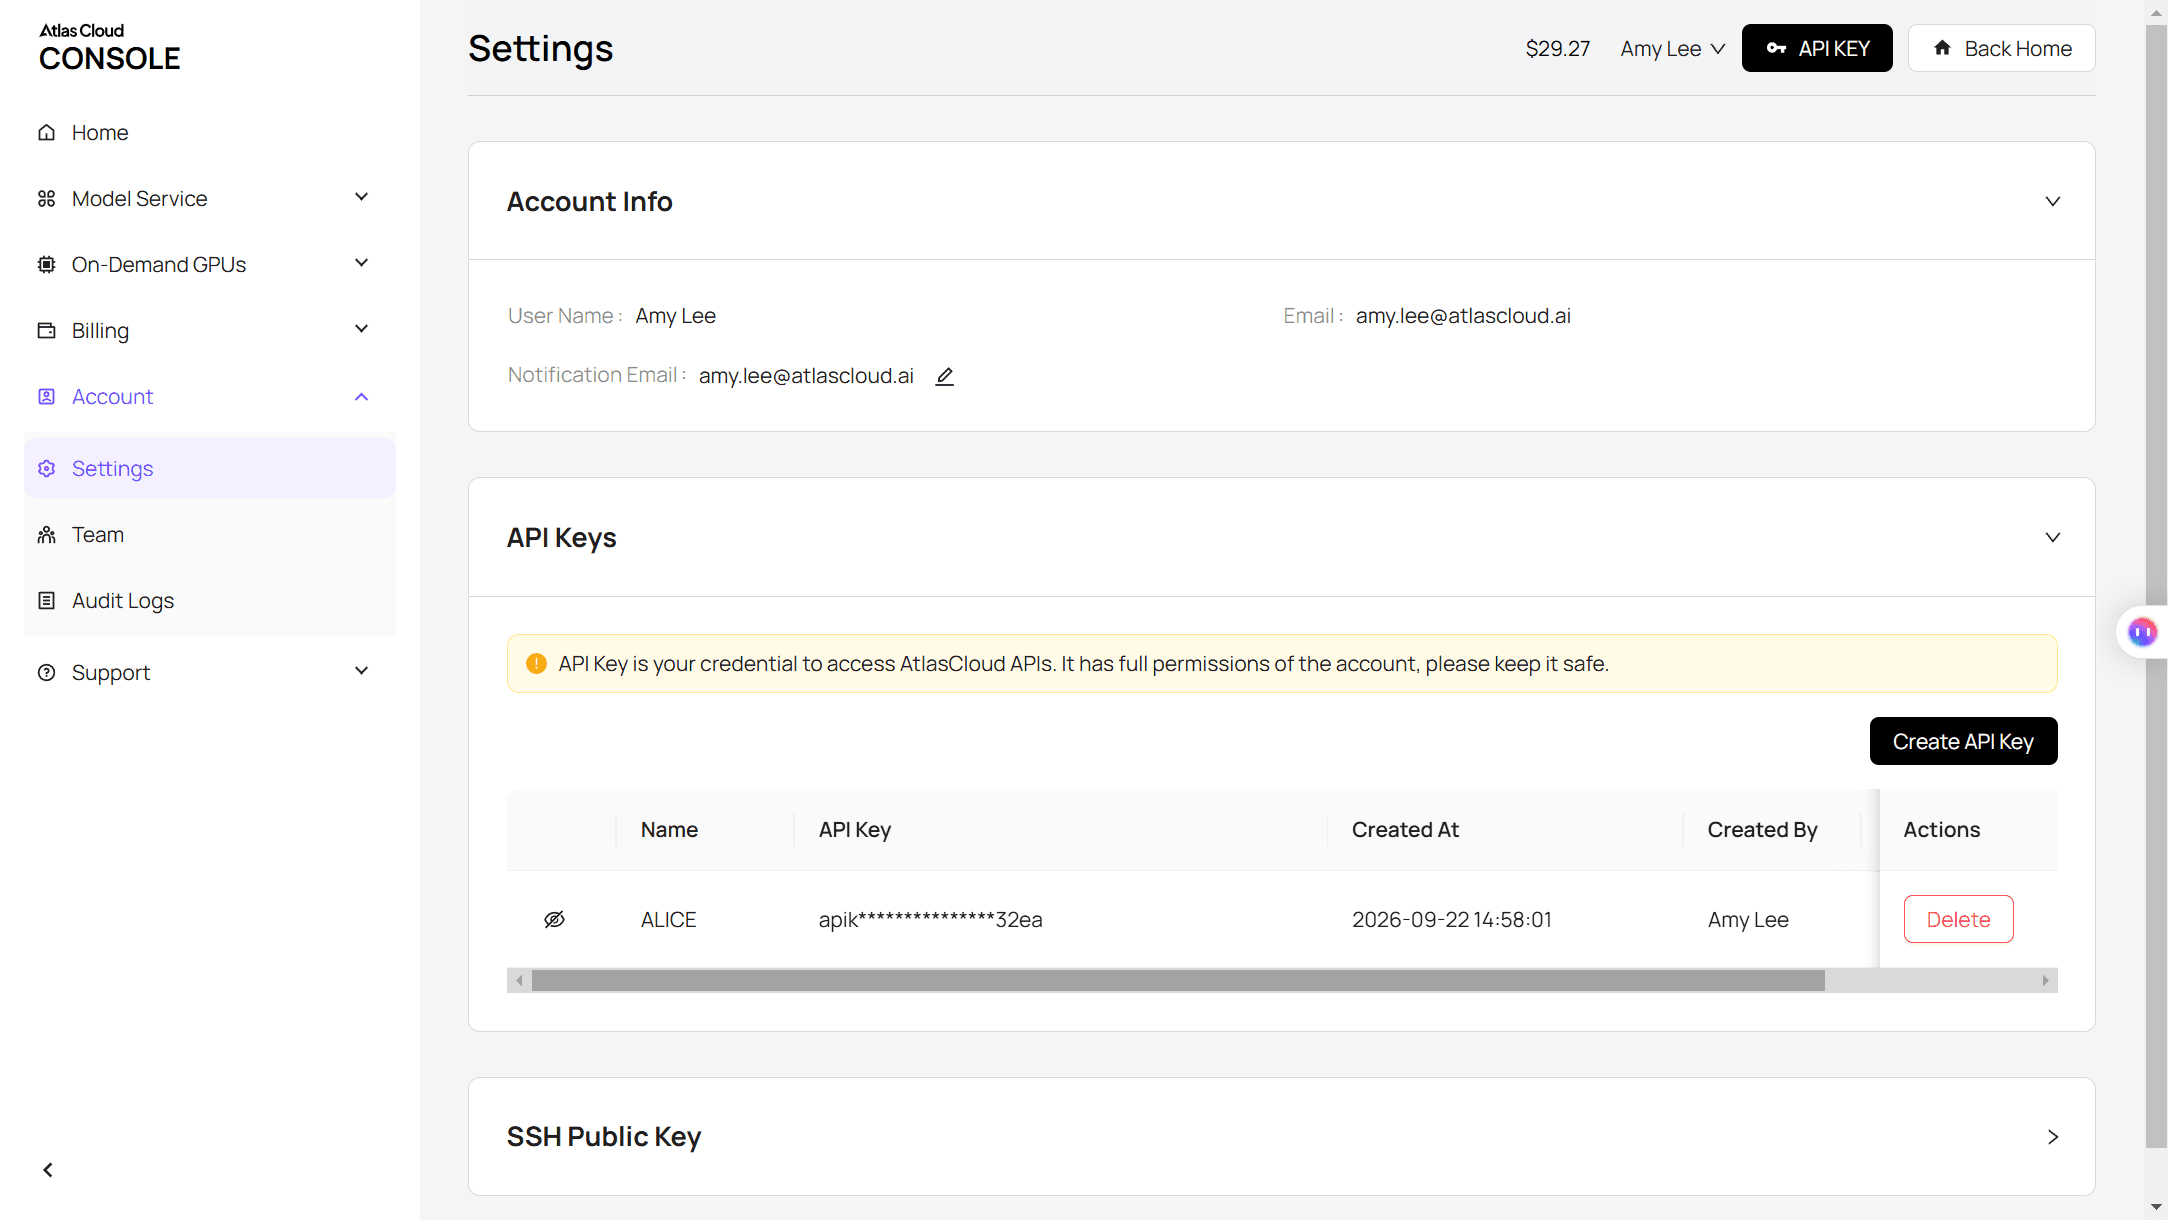
Step 2: Check the request format. The Atlas Cloud API docs list the request formats each model accepts. GPT-6.2 Sol takes the OpenAI Responses format.
Step 3: Send the request.
plaintext1curl https://api.atlascloud.ai/v1/responses \ 2 -H "Authorization: Bearer $ATLASCLOUD_API_KEY" \ 3 -H "Content-Type: application/json" \ 4 -d '{ 5 "model": "openai/gpt-6.2-sol", 6 "input": "Write the opening of a newsletter profile from my interview notes below. 270 to 330 words. ...", 7 "max_output_tokens": 32000 8 }'
The draft comes back in the output array, inside the message item's content, and the usage block counts input, output and reasoning tokens. Change the model string to openai/gpt-6.2-astra and the same request runs on the larger model, with the same endpoint and the same key.
Claude vs ChatGPT for Coding: One Repo, One Rubric
The test repo is a small Python payroll tool with two planted bugs. Overnight shifts came out as negative hours, and pay used Python's round() even though the docstring promised half-up rounding to the cent.
The task, sent once with no follow-up: make the failing tests pass, then add a --week-start option (Monday or Sunday) that changes how overtime weeks are counted. Eight hidden tests, never shown to either agent, did the grading.
| Claude Code (Opus 5.5) | Codex (GPT-6.2 Sol) | |
|---|---|---|
| Tests passing after the run | 22 (17 added) | 9 (4 added) |
| Hidden tests | 8 of 8 | 8 of 8 |
| Files changed | 5, none outside the task | 5, none outside the task |
| Lines added and removed | +207 / -23 | +60 / -10 |
| Time | 208 seconds | 120 seconds |
A tie on the rubric. The styles differed, though. Claude Code wrote 17 new tests, then ran its own sample payroll, caught a half-cent rounding case caused by a 20-minute break (7 2/3 hours) and switched the weekly totals to exact arithmetic. Codex made the smallest change that met the brief and finished in a little over half the time.
We ran Codex against GPT-6.2 Sol with an Atlas Cloud key, which Codex accepts as a custom provider:
plaintext1codex exec -m openai/gpt-6.2-sol \ 2 -c 'model_provider="atlas"' \ 3 -c 'model_providers.atlas={name="Atlas Cloud",base_url="https://api.atlascloud.ai/v1",env_key="ATLASCLOUD_API_KEY",wire_api="responses"}' \ 4 --sandbox workspace-write "Fix the failing tests, then add a --week-start option..."
ChatGPT Codex vs Claude Code: Should You Get Claude Pro or ChatGPT Plus for Coding?
Claude Pro and ChatGPT Plus both include a coding agent. They ration it differently.
| Codex (ChatGPT) | Claude Code | |
|---|---|---|
| Lowest plan that includes it | Free and Go get limited access; Plus and up get more | Pro; not on Free |
| Newest models on Plus and Pro | GPT-6.2 Sol and GPT-6.2 Astra | Opus 5.5; Fable 5.2 costs usage credits on Pro |
| How Plus and Pro meter it | OpenAI estimates 17 to 180 local messages per five hours on GPT-6.2 Sol, 6 to 50 on Astra | Shares one five-hour and one weekly limit with Claude chat |
| Pool shared with | ChatGPT Work | Claude chat and the desktop app |
| At the top tiers | Pro plans have no five-hour Codex limit for now | Ultra has no five-hour limit for verified accounts |
So which plan is better for coding? Both agents shipped a correct fix here, so the plan details decide it.
Plus gives you both GPT-6.2 models in Codex, a published estimate per five-hour window, and for now a coding allowance separate from chat. OpenAI says Plus usage will be shared across ChatGPT and Codex starting in December. Pro puts Opus 5.5, the more thorough agent in our run, behind Claude Code, but every coding session draws on the same limit as your chats.
Claude vs ChatGPT for Writing: Same Notes, Measured Drafts
The brief is the Method 1 prompt: a 270 to 330 word newsletter opening from interview notes, two quotes kept word for word, one off-the-record line left out, nine banned phrases and no em dashes. Seven pass checks; style is described, not scored.
Claude's draft met all seven checks. GPT-6.2 Sol's met six: it kept both quotes word for word as standalone lines, stayed clear of the off-the-record loan and every banned phrase, and closed with the hours. We counted the quotes by their words. Claude folded each one into the story with "she says" and swapped the closing period for a comma, which is standard newsroom punctuation.
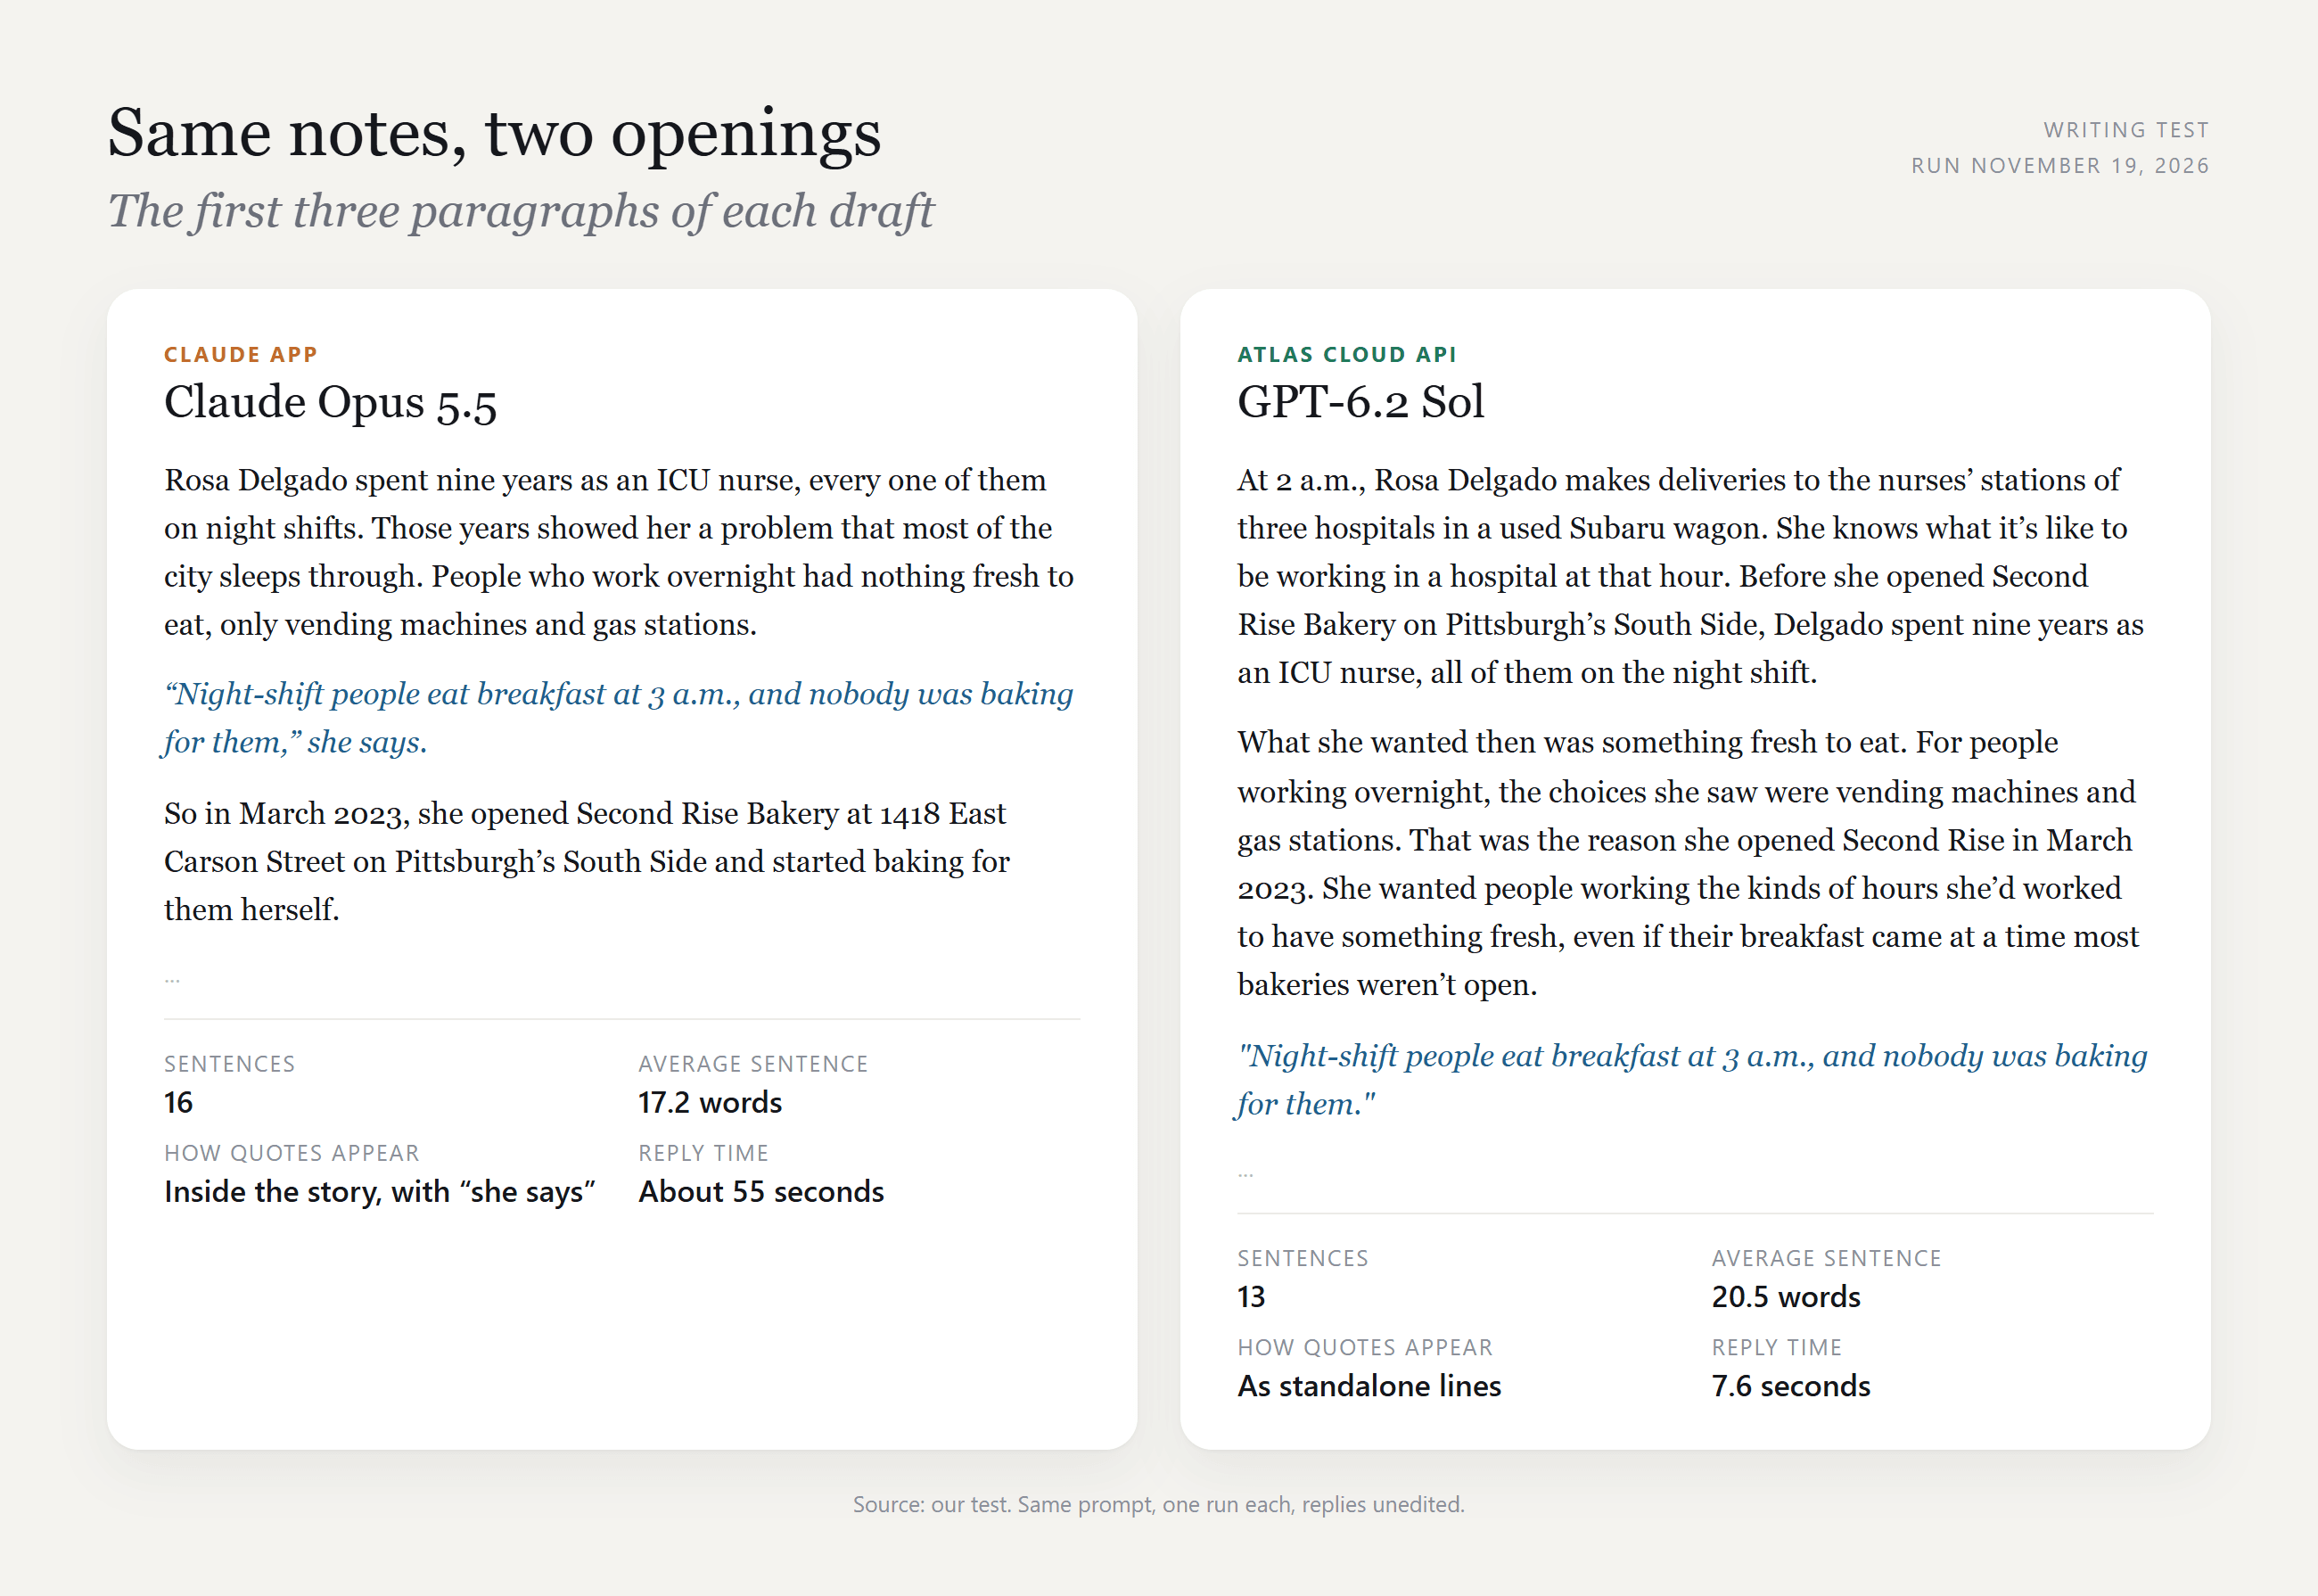
The bigger difference was in how each worked. Claude ran code to check its draft before replying, then listed three of its own lines that went past the notes, such as "Rosa left nursing behind." GPT-6.2 Sol made that same assumption without comment, and it came back in 7.6 seconds against Claude's roughly 55.
Claude opened on her nursing years; GPT-6.2 Sol opened on the 2 a.m. delivery run. Which lede you prefer is taste, so we did not score it.
Claude vs ChatGPT for Long Documents: Context Window Size and a 31,864-Word Transcript
On paper, the plans differ sharply on long files.
| Where you work | ChatGPT | Claude |
|---|---|---|
| Free plan | 27K tokens in Instant | Up to 1M, varies by model |
| Plus and Pro | 54K in Instant, 256K in reasoning mode | Up to 1M, varies by model |
| Top plan | 128K in Instant, 400K in reasoning mode (Pro) | Up to 1M, varies by model |
| GPT-6.2 Sol through the API | 1,050,000 tokens | Not applicable |
Our transcript covers three planning meetings at a fictional coffee roaster, about 44,000 tokens, which fits every paid option above. Inside the chatter we planted 21 facts about a subscription launch: 10 decisions still in force, 8 action items with an owner and a due date, and 3 reversals, including a budget corrected from $48,000 to $84,000. The ask: where does the launch stand?
Both found all 21. Both also flagged tasks the transcript never assigned, one for Claude and three for GPT-6.2 Sol, each labelled as unassigned, so none counts as an error.
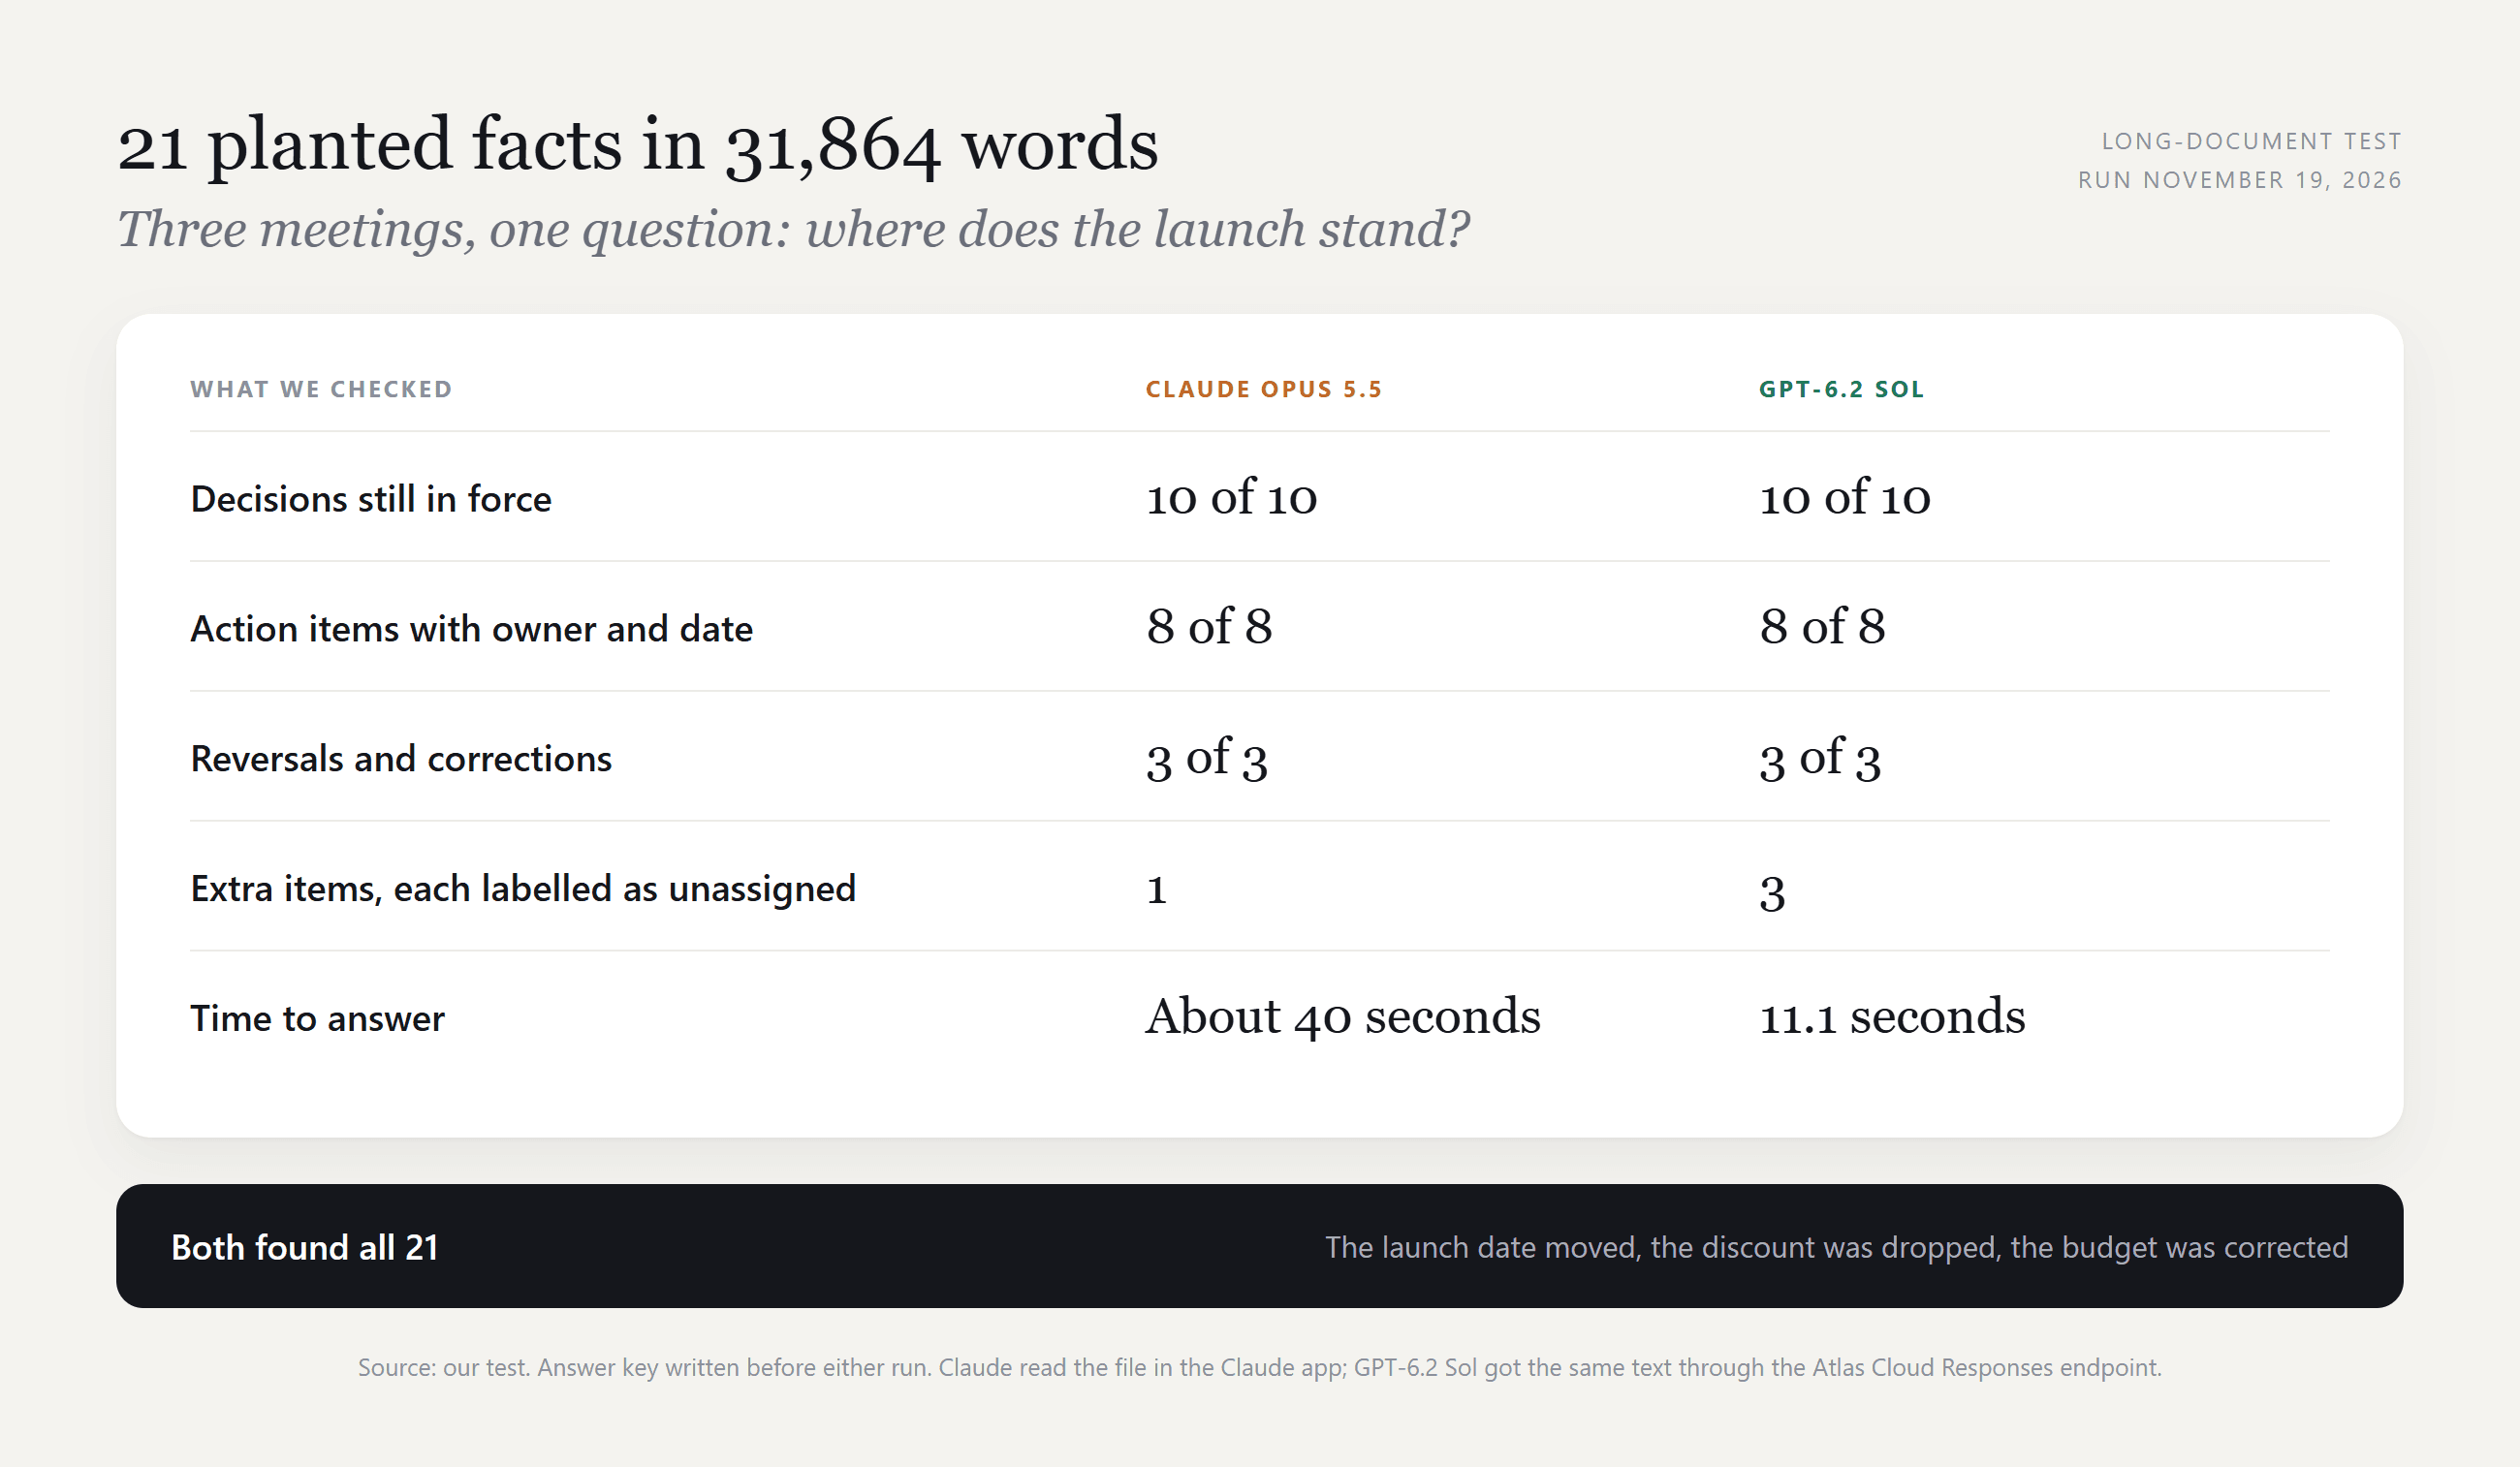
So for summarizing transcripts, the model is not the bottleneck at this length. The window is. Our 44,000 tokens fit everywhere, but a transcript twice as long would overflow ChatGPT Plus in Instant mode and fit in its reasoning mode, in Claude's app and in GPT-6.2 Sol through the API.
Claude Pro vs ChatGPT Plus: What Each Plan Includes, Up to Max and Pro
Prices are list prices in US dollars per month, checked November 19, 2026 on the Claude pricing page and the ChatGPT plans page.
| Monthly price | ChatGPT | Claude |
|---|---|---|
| $0 | Free: GPT-6 Luna, ads may appear | Free: Sonnet 5.5 and Haiku 5.5, limited usage |
| $8 | Go: GPT-6 Luna with more usage than Free, ads may appear | No equivalent |
| $20 | Plus: GPT-6 Sol in chat, both GPT-6.2 models in Work and Codex | Pro ($17 a month billed yearly): Opus 5.5, Claude Code, Fable 5.2 on usage credits |
| $100 | Pro 100: GPT-6 Pro reasoning, $100 of API credits a month | Max: 5x Pro usage, Fable 5.2 up to half the weekly limit, $100 of API credits a month |
| $200 | Pro 200: Ultrafast GPT-6.2 Sol in Codex, $200 of API credits | Ultra: no five-hour limit for verified accounts, 10x Pro weekly usage, $200 of API credits |
| $500 | Pro 500: Ultrafast on both GPT-6.2 models, $500 of API credits | No equivalent |
At $20, the trade is clear. Plus reaches OpenAI's newest models today, with tight windows on Astra. Pro gets you Opus 5.5 in both chat and Claude Code, and Anthropic's top model costs extra until you move up.
At $100 and $200, Claude Max vs ChatGPT Pro is a close match: both bundle API credits worth the monthly price.
The difference is what the extra money unlocks. Max and Ultra buy more Claude usage and include Fable 5.2. On ChatGPT, Pro 100 and Pro 200 add the GPT-6 Pro reasoning mode, and Pro 200 and Pro 500 add Ultrafast speeds in Codex. Our ChatGPT Plus vs Pro breakdown covers the three Pro tiers line by line.
Claude vs ChatGPT vs Gemini: When a Third App Changes the Pick
Gemini changes the answer in two cases.
| If you need | Pick | Why |
|---|---|---|
| Video from a text prompt inside the chat app | Gemini | Google AI Pro includes Gemini Omni video clips; neither ChatGPT nor Claude makes footage |
| A third image model to compare | Gemini | Nano Banana 2.1 sits beside ChatGPT Images 2.5 as the other in-app option |
| Everything else in this article | Claude or ChatGPT | Gemini's 1M context on Google AI Pro matches Claude's ceiling rather than beating it |
Our Gemini vs ChatGPT test ran Gemini 4 Argon against GPT-6 Sol on three other prompts, if Gemini is the app you are weighing.
FAQ
Is Claude better than ChatGPT?
For writing, narrowly, in our test: Claude Opus 5.5 met every check on a strict brief and flagged its own guesses. On coding and a 31,864-word transcript it tied GPT-6.2 Sol, which answered faster each time. ChatGPT is the better pick if you want images in the app, a cheaper $8 tier, or OpenAI's newest models on a $20 plan.
Why is everyone leaving ChatGPT for Claude?
"Everyone" overstates it. OpenAI reported 900 million weekly ChatGPT users on February 27, 2026, and said January and February were on track to be its biggest months for new subscribers.
Still, February brought a real wave toward Claude. OpenAI began testing ads on Free and Go in the US on February 9, after Anthropic promised to keep Claude ad-free. Then Anthropic's Pentagon talks broke down over safeguards against mass domestic surveillance and fully autonomous weapons, and OpenAI announced its own Pentagon agreement.
TechCrunch, citing Sensor Tower data, reported that Claude overtook ChatGPT for No. 1 among free apps in the US App Store on February 28. An Anthropic spokesperson told the outlet that paid subscribers had more than doubled that year.
Can you move your ChatGPT memory to Claude?
Yes. Anthropic's help center says memory import works on every Claude plan, Free included, on the web and in Claude Desktop, and it accepts memories exported from other AI providers.
Do Claude and ChatGPT train on your chats?
Both do unless you switch it off. ChatGPT personal accounts have data sharing on by default under Data Controls. Claude's plan table lists model training as opt-out on Free, Pro, Max and Ultra, and Anthropic keeps opted-in chats in a de-identified form for up to five years. Claude's incognito chats and ChatGPT's Temporary Chats stay out of training either way.
How much did the ChatGPT side of these tests cost?
About $0.31 for all three runs: $0.21 for the Codex coding task, $0.10 for the 31,864-word transcript and under a cent for the writing draft. That is at Atlas Cloud's price for GPT-6.2 Sol as of November 19, 2026: $2 per million input tokens, $10 per million output tokens and $0.10 per million cached input tokens.
The Codex run cost the most because the agent resends the repo context on every step, mostly from cache.
Conclusion
Three tasks gave three different readings of Claude vs ChatGPT. Claude's profile met every check and came with notes on its own guesses. Both coding agents shipped a correct fix, both models found all 21 facts in the transcript, and GPT-6.2 Sol was faster every time.
So pick by the work you do most. Claude Pro suits long writing, big files and a careful coding agent that shares your chat limit. ChatGPT Plus suits image generation, OpenAI's newest models and a coding allowance that stays separate from chat until December. If you only need the ChatGPT side for a project, GPT-6.2 Sol runs by the token on Atlas Cloud with no subscription.




