Qwen Image 3.0 pro Identity Preserving Edits
Qwen Image 3.0 pro is Qwen's image generation and editing family for developers building production visual workflows. It creates images up to 2048×2048, rewrites prompts automatically, selects resolution from prompt intent, and follows natural language editing instructions while preserving facial features and identity. Access both models through Atlas Cloud with one OpenAI compatible key and standard pay as you go pricing of $0.04 per call. Start building today.
Qwen Image 3.0 Pro is developed by Alibaba. Atlas Cloud (operated by Atlas Cloud AI LLC) provides access to it and does not own it. All trademarks belong to their respective owners.
Explore the Leading Qwen Image 3.0 Pro
Atlas Cloud provides you with the latest industry-leading creative models.


Qwen Image 3.0 pro Generation and Editing Modes
Compare the text-to-image and reference-based editing endpoints available for Qwen Image 3.0 pro.
| Modality | Description |
|---|---|
| Qwen Image 3.0 Pro API (Text to Image) | Turn text prompts into images at resolutions up to 2048×2048, with automatic prompt rewriting and prompt-guided resolution selection. Strong complex text rendering and precise prompt adherence support posters, product visuals, illustrations, and other composition-sensitive assets. |
| Qwen Image 3.0 Pro API (Image Editing) | Provide one to three reference images and a natural-language instruction to produce an edited image. Key details such as facial features and identity are preserved while requested changes are applied, making the endpoint suitable for portrait refinement, visual variations, and controlled asset updates. |
Inside Qwen Image 3.0 pro: Type, Detail, and Control
Qwen Image 3.0 pro combines complex text rendering, precise prompt adherence, generation up to 2048 × 2048, automatic prompt rewriting, and identity preserving edits from one to three references through Atlas Cloud's unified pay as you go API.
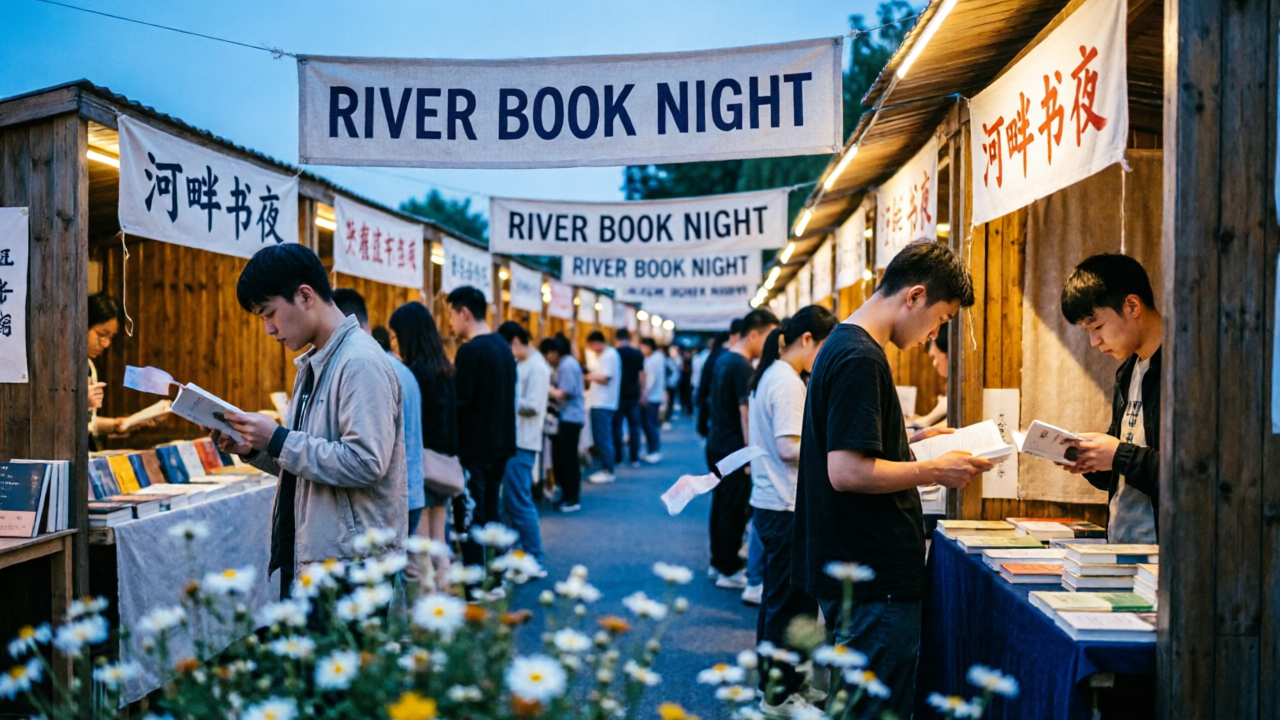
Qwen Image 3.0 pro Typography
Qwen Image 3.0 pro follows detailed prompts while handling complex text rendering in English and Chinese. It can structure dense creative layouts without separating type from the scene. Specify copy, hierarchy, composition, and visual style in one request, then proofread names and numbers before publishing. This makes it practical for banners, editorial graphics, packaging concepts, and information rich artwork.
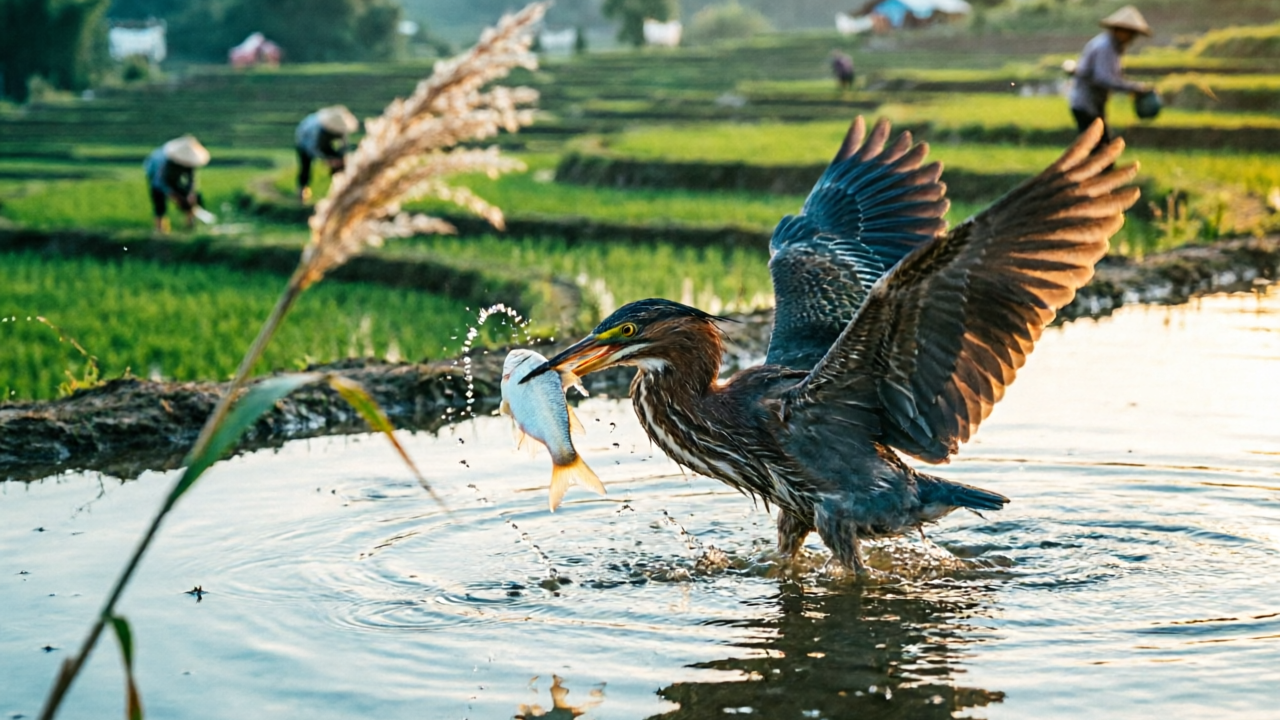
2048 × 2048 Detail
Generate images at resolutions up to 2048 × 2048 when fine texture and readable detail matter. Prompt guided size selection can choose an output resolution automatically, while an explicit size lets you target a known canvas. From product photography to editorial portraits, the extra pixel budget supports closer inspection, flexible downstream crops, and polished production assets.
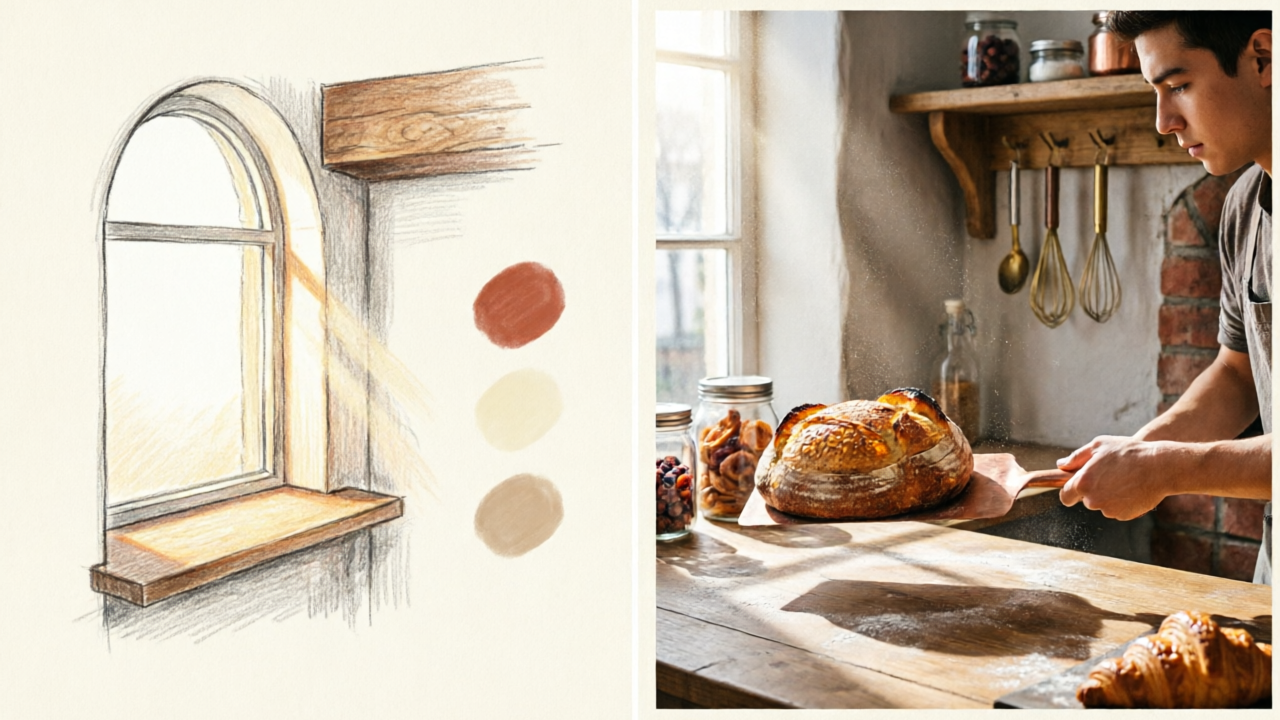
Two Prompt Rewrite Modes
Short prompts can be expanded automatically before generation, with rewriting enabled by default. On the text generation endpoint, Direct mode performs a single pass rewrite, while Agent mode uses an agentic pipeline to enrich the brief. Keep rewriting on for exploratory concepts or disable it when exact wording and tightly controlled instructions matter more in production.
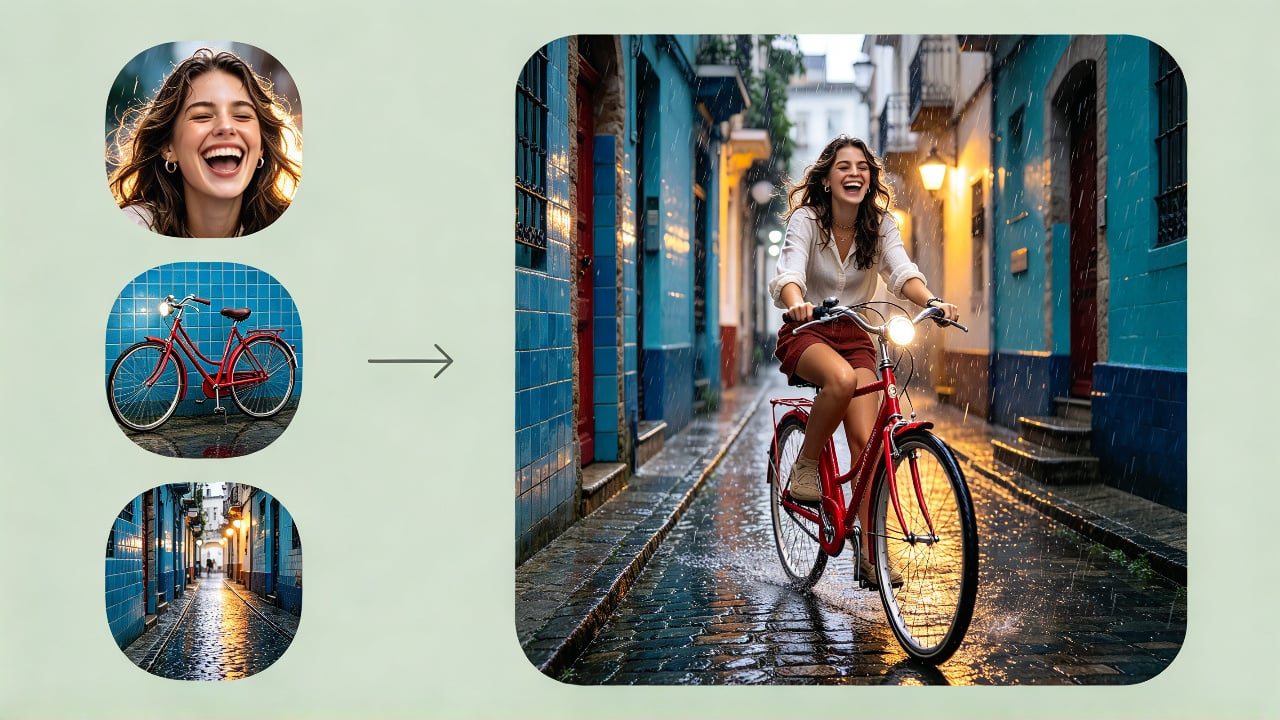
One to Three Reference Edits
Bring one to three reference images into an edit and describe the change in natural language. The model can use those sources for subject, context, or visual guidance while preserving key facial features and identity. Ask for a new environment, styling, or composition without rebuilding the approved subject from scratch. This suits campaign variants, character continuity, and reference led product scenes.
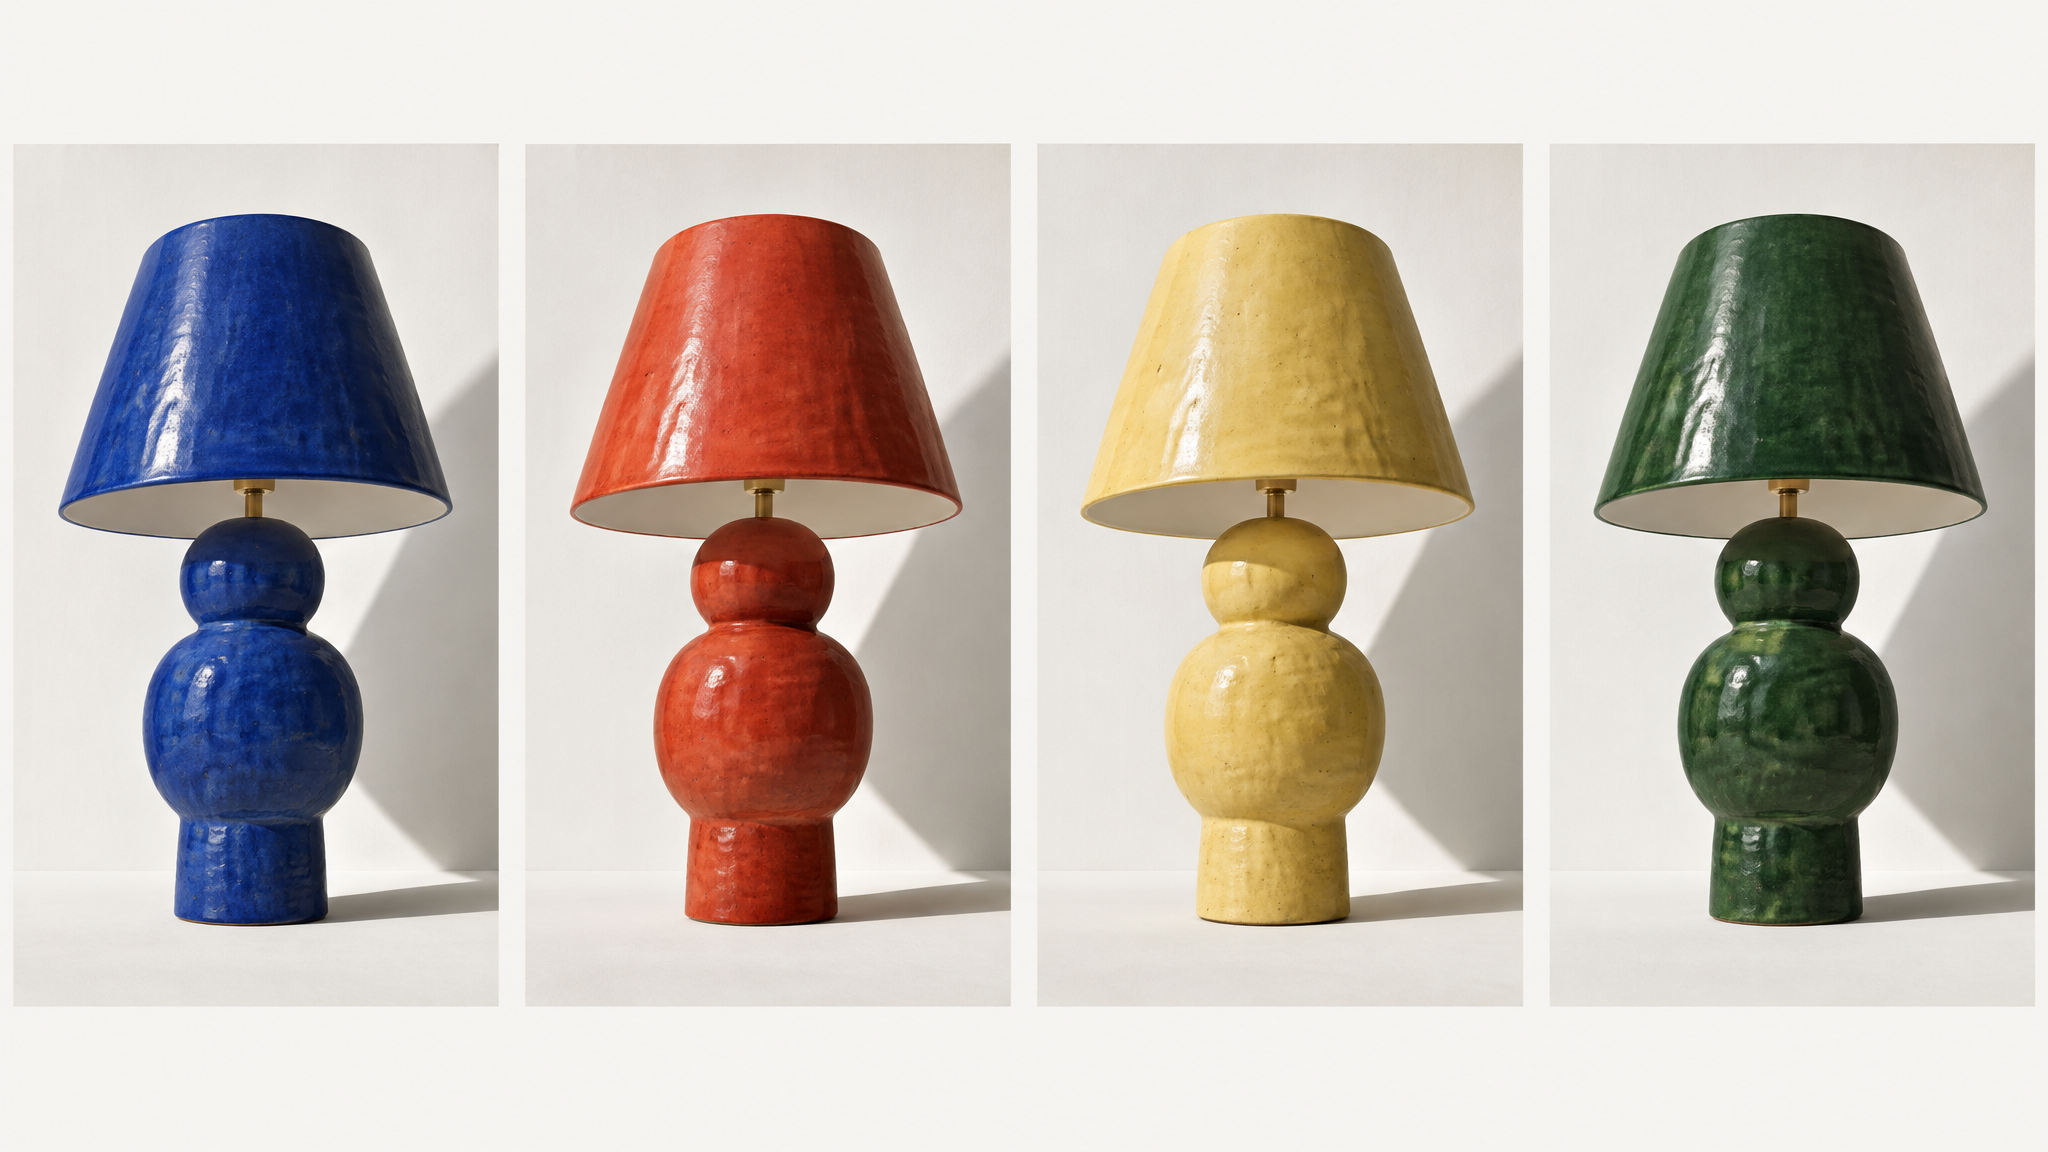
Reproducible Batch Controls
Need repeatable experiments? Set a fixed seed from 0 to 2147483647, add a negative prompt, and request as many as four outputs in one generation call. Those controls make it easier to compare prompt revisions, exclude unwanted content, and review a small option set under consistent conditions. Use them for structured creative testing rather than one off guesswork.
One Prompt, Three Visions: Qwen Image 3.0 pro Compared
See how Qwen Image 3.0 pro, a leading external competitor, and its same-series predecessor interpret identical prompts across typography-rich design and documentary photography.
At a bustling spice bazaar at high noon, capture the decisive, humorous instant when a young male vendor swings a coarse burlap sack of saffron into the air just as a motion-blurred pigeon clips a mound of turmeric, sending a radiant cloud of golden powder suspended across the scene; startled customers react naturally and comically, one clearly shielding several glossy red pomegranates with both hands while another simultaneously clutches folded paper spice packets against their chest, with every arm, hand, finger, object, and interaction anatomically correct, distinct, and easy to read. Frame the market through layered stone arcades for a strong frame-within-a-frame composition, using a slightly elevated Dutch-angle viewpoint; repeating blocks of crimson chilies, deep indigo ceramic bowls, and vivid yellow turmeric piles create a disciplined primary-color palette of red, yellow, and blue only. Hard directional midday skylight cuts crisp geometric shadows across the stalls, faces, and worn paving stones. Preserve tactile realism in airborne powder granules, woven burlap fibers, papery saffron threads, dusty spice heaps, hammered copper weighing scales, glazed pottery, weathered wood grain, wrinkled paper packets, natural youthful skin, and subtle analog film grain. Include a wide horizontal hand-painted shop sign reading exactly “SPICE, SUN & SURPRISE” in large, perfectly legible letters, plus several separate handwritten price tags reading exactly “SAFFRON 12”, “TURMERIC 4”, “CHILIES 6”, and “POMEGRANATES 3”, all correctly spelled, cleanly formed, and naturally integrated into the stall. Vintage 1970s travel-magazine documentary photography, candid human warmth, restrained realism, 28mm environmental lens, deep layered focus with a softly occluded foreground edge, slight pigeon motion blur, sharp faces and hands, authentic exposure, no posing, no oily over-rendering, no HDR look, no plastic skin, no muddy colors, no excessive glow, no fantasy epic lighting, no cluttered rainbow palette, no malformed hands, no extra fingers, no duplicated people, no garbled text, no borders, no mockup, wide landscape 16:9 aspect ratio, full-bleed.
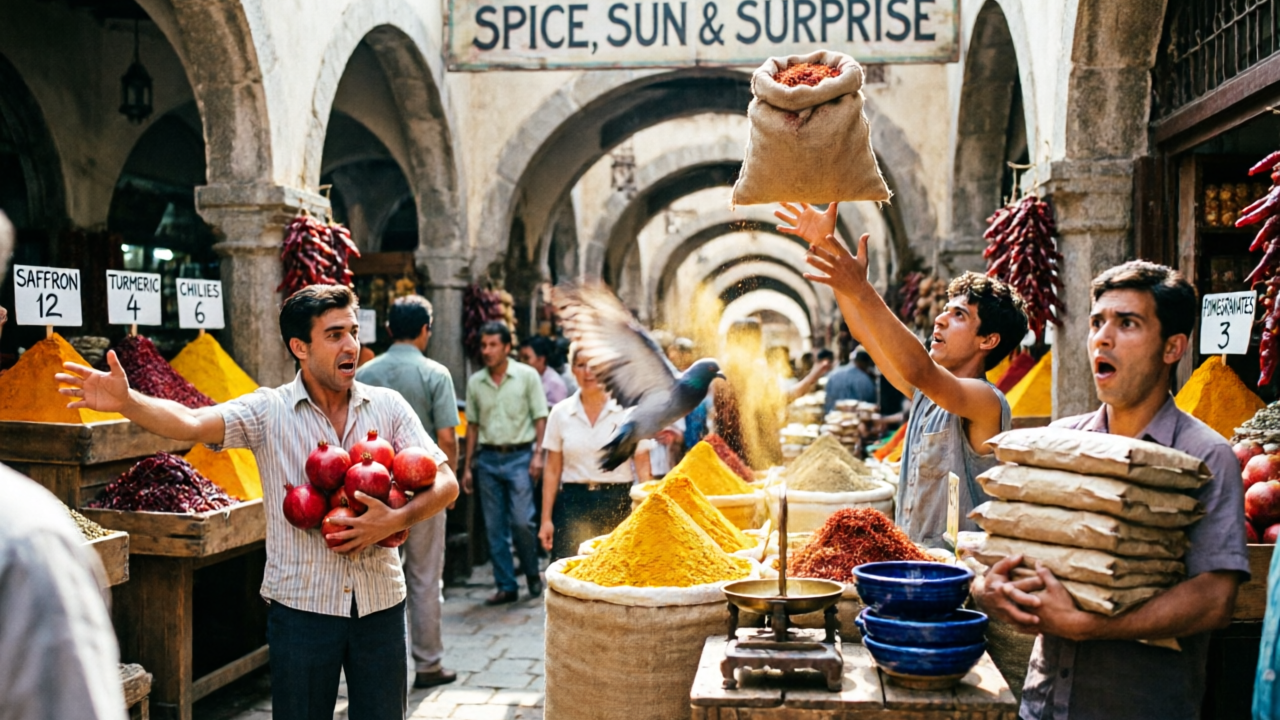
Generated with Qwen Image 3.0 Pro Text-to-Image on Atlas Cloud
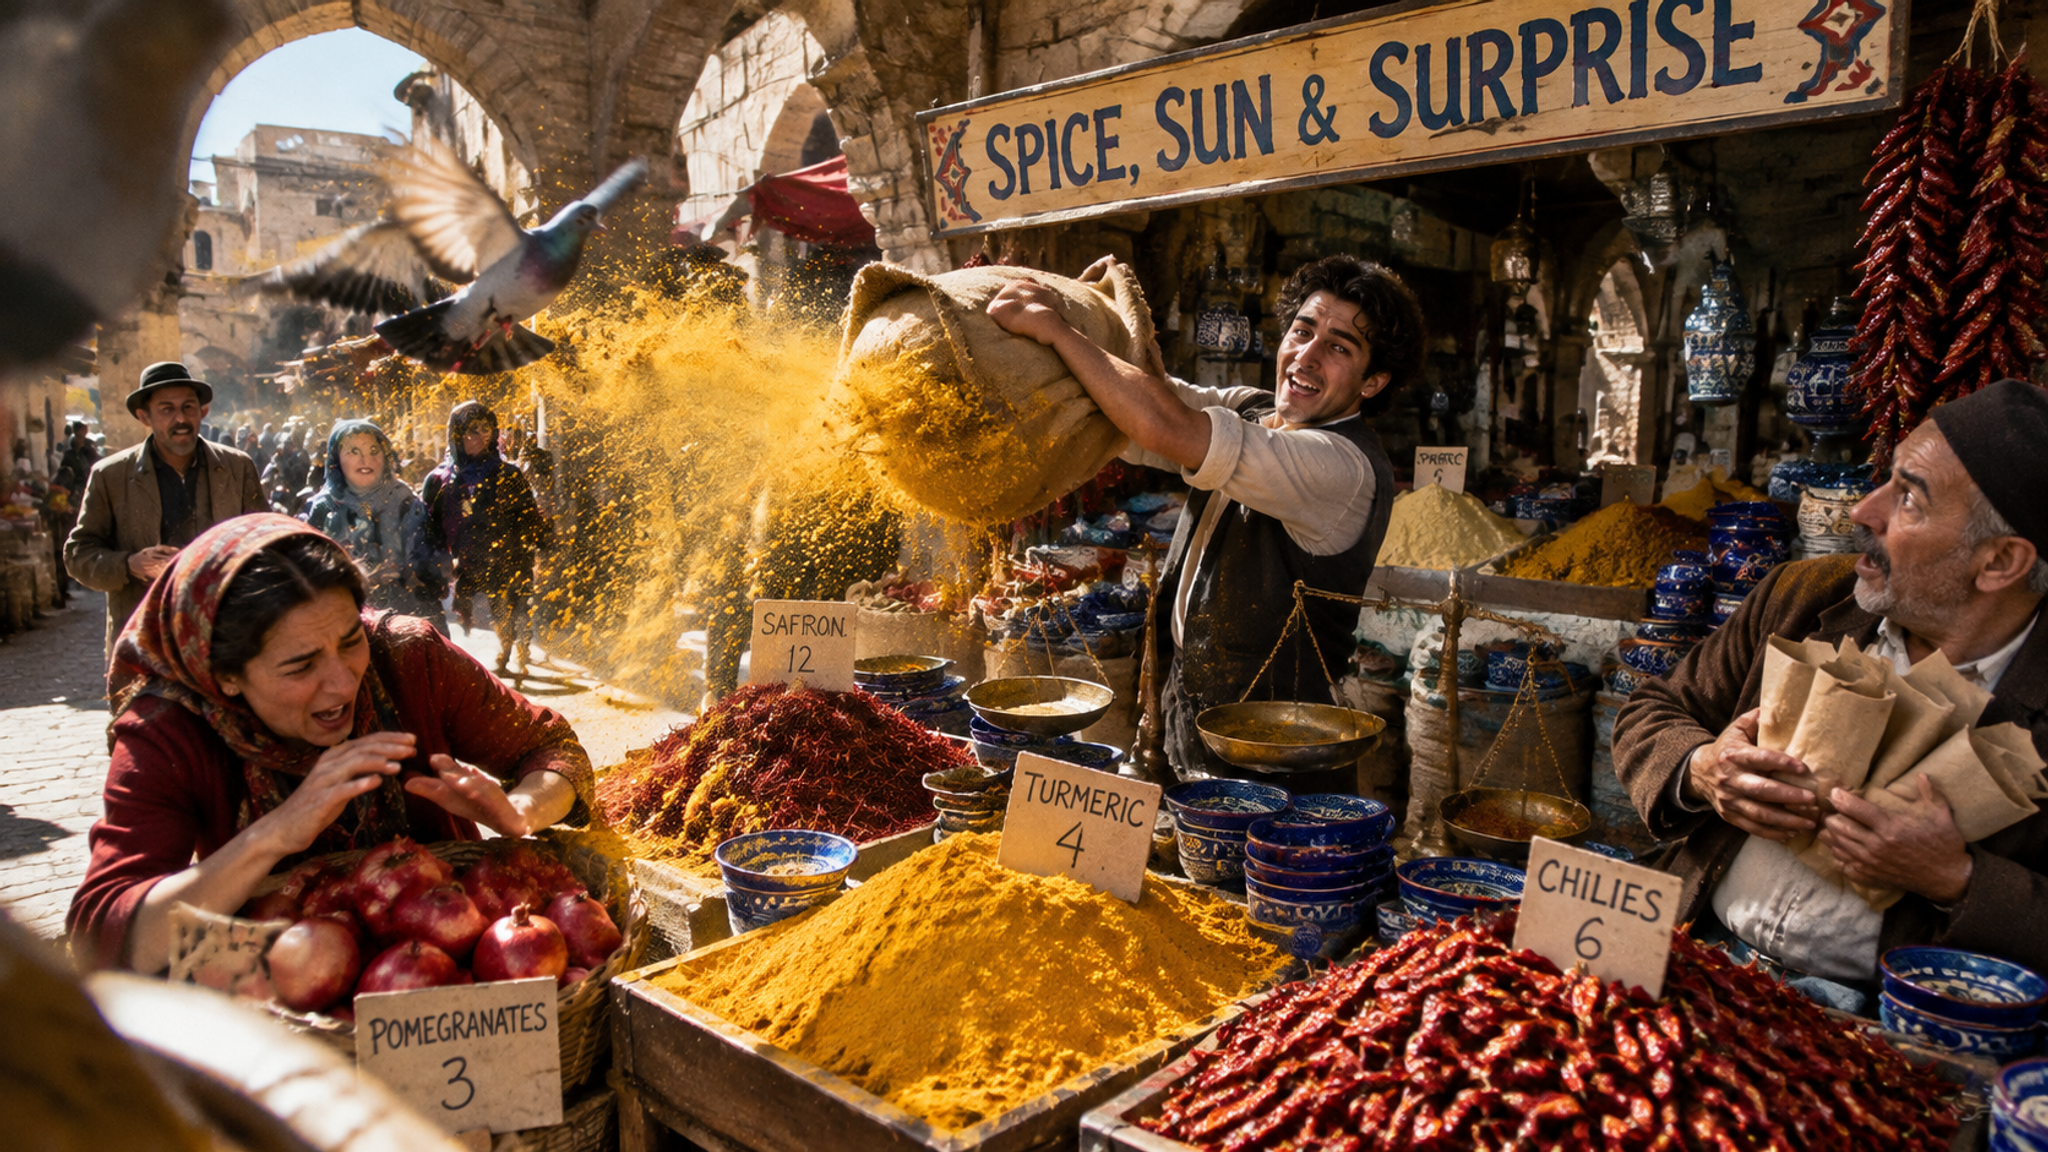
Generated with Seedream v5.0 Pro Text-to-Image on Atlas Cloud
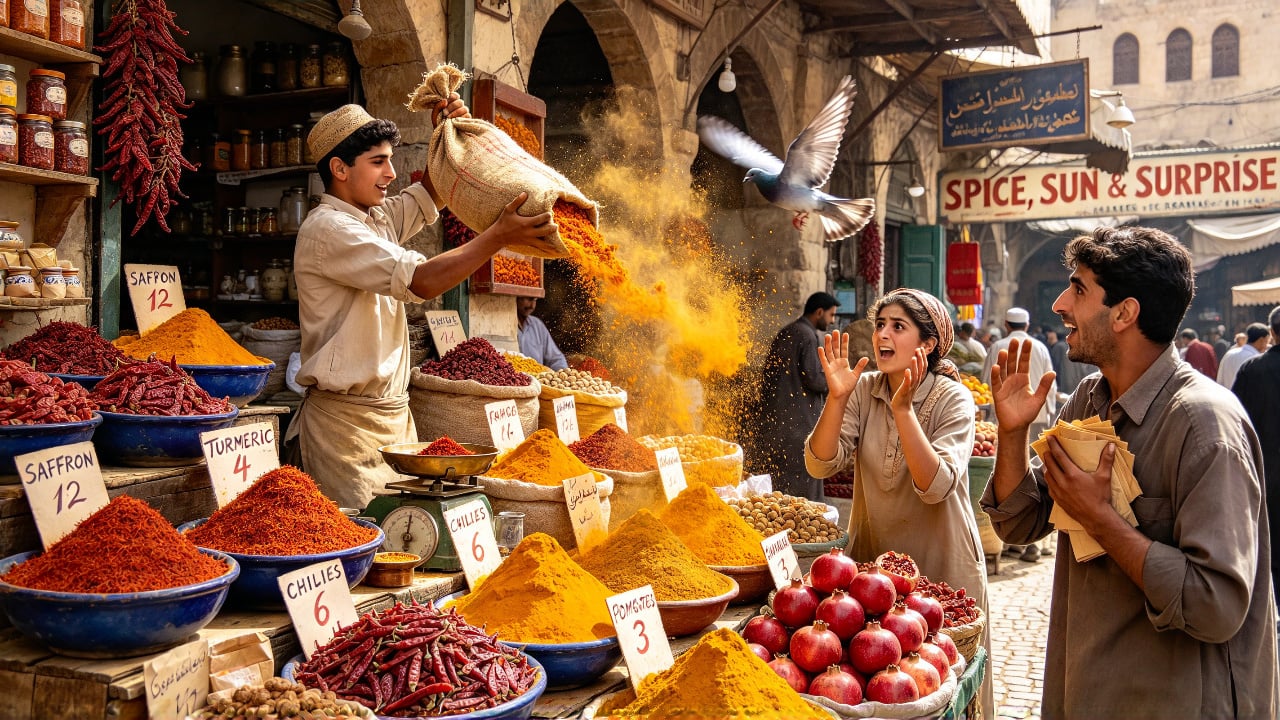
Generated with Qwen Image 3.0 Text-to-Image on Atlas Cloud
Cinematic documentary photograph inside a self-service laundromat on a rainy night, capturing the decisive instant when a front-loading washing machine suddenly gushes a huge cascade of white foam; a young woman in a bright yellow raincoat laughs spontaneously as she catches the spill with a red plastic washbasin, her hands naturally gripping the rim with anatomically correct fingers, while her friend stands outside the fogged glass and clearly finger-writes the exact mirror-reversed text “LAST WASH 11:30,” legible from inside the laundromat; at that same moment, one wet sock slaps against and sticks to the glass. Rows of circular washer doors create bold repeating geometry and strong leading lines into deep space, while layered reflections in the window reveal both the playful interior action and the rain-soaked neon street outside, forming a coherent double narrative. Directional cold-white fluorescent ceiling light carves crisp silhouettes and clean contours across faces, raincoat, hands, foam, and chrome; restrained magenta neon bleeds through the window and reflects in pavement puddles, with a disciplined cyan-blue, vivid yellow, and magenta three-color palette. Photorealistic water droplets on glass, translucent bubbles, damp woven fabric, brushed metal, rubber door seals, condensation, puddle reflections, subtle motion blur in the flying foam, gentle high-ISO film grain, natural youthful skin texture, candid expressions, complex yet spatially consistent reflections and transparent surfaces. Eye-level environmental reportage, 35mm lens, moderate depth of field, cinematic realism, subtle imperfections, no staged posing, no greasy over-rendering, no HDR look, no plastic skin, no muddy colors, no excessive glow, no cheap epic lighting, wide horizontal 16:9 aspect ratio, full-bleed.
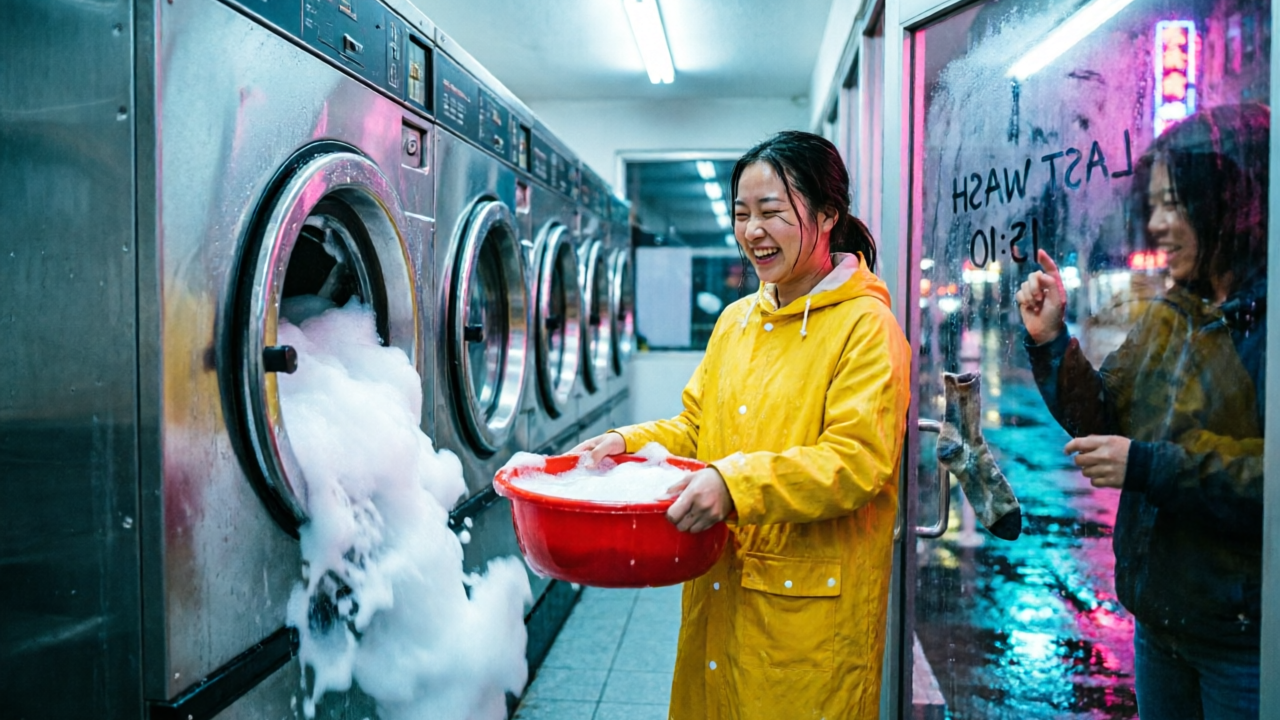
Generated with Qwen Image 3.0 Pro Text-to-Image on Atlas Cloud
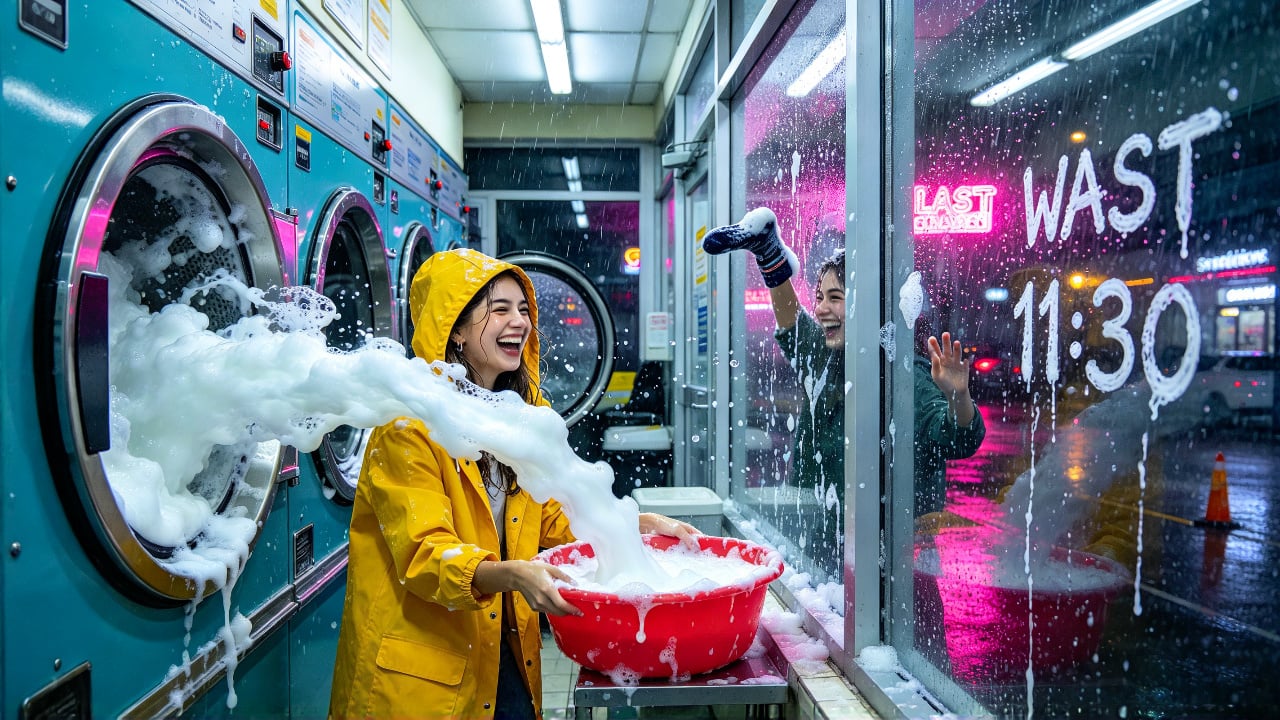
Generated with Seedream v5.0 Pro Text-to-Image on Atlas Cloud
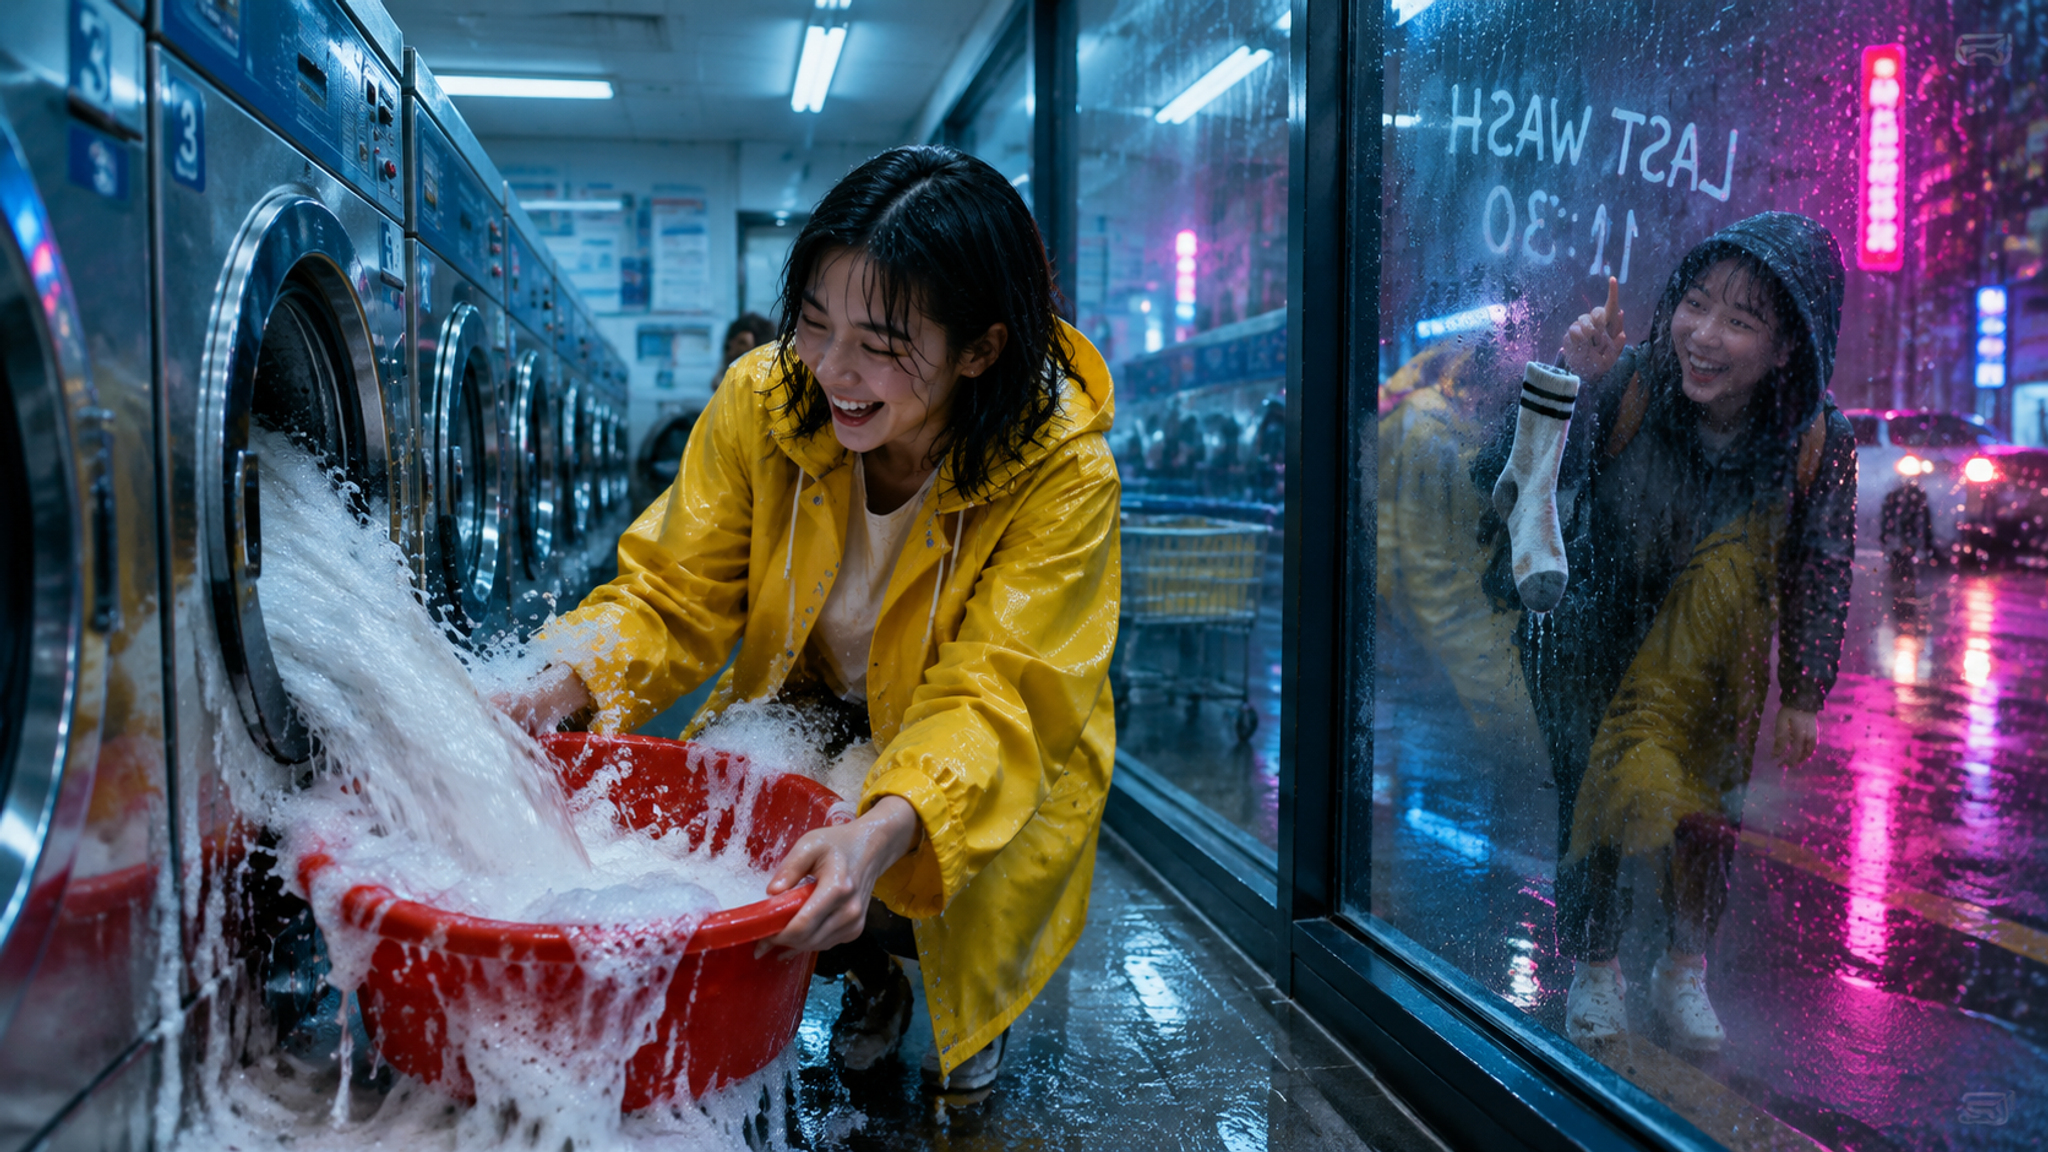
Generated with Qwen Image 3.0 Text-to-Image on Atlas Cloud
Build Visual Systems with Qwen Image 3.0 Pro
Qwen Image 3.0 Pro supports campaign graphics, product visuals, interface concepts, storyboards, and identity preserving edits through precise prompt adherence, complex text rendering, up to 2048×2048 output, and one to three reference images.

Campaign Posters with Qwen Image 3.0 Pro
Turn demanding prompts into campaign posters, banners, and social graphics using Qwen's strength in complex text rendering and precise prompt adherence. Create brand assets at up to 2048×2048 for launches, events, and promotions.

Qwen Image 3.0 Pro Product Visuals
Generate product scenes from text while automatic prompt rewriting expands brief ideas and prompt-guided sizing selects a fitting canvas. The result supports catalog images, ecommerce promotions, and rapid concept testing for small teams.

Identity Preserving Portrait Edits
Preserve facial features and identity while changing wardrobe, setting, lighting, or visual style through natural-language edits. Portrait studios and creator apps can produce recognizable campaign variations from one to three reference images.

Interface and Infographic Concepts
Need information-rich visuals from detailed instructions? Use precise prompt adherence and complex text rendering to prototype interface concepts, educational diagrams, annotated explainers, and presentation graphics for product or learning teams.

Multi-Reference Compositions
Bring up to three reference images into a single editing request, then direct changes in natural language while key details remain intact. This fits composites, merchandise variations, and character-centered creative workflows.

Storyboards with Qwen Image 3.0 Pro
Sketch sequential scenes from carefully written prompts, with prompt adherence helping each frame follow the requested subjects, settings, and visual direction. Filmmakers, agencies, and game teams can turn early ideas into storyboard panels.
Qwen Image 3.0 pro vs Leading Image APIs
Compare Qwen Image 3.0 pro with Seedream and Nano Banana endpoints by workflow, maximum output size, reference capacity, prompt tools, and Atlas Cloud standard price.
| Model | Workflow | Max Output Size | Max Reference Images | Prompt Tools | Standard Price |
|---|---|---|---|---|---|
| Qwen Image 3.0 Pro Text-to-Image | Text to image | 2048×2048 | - | Automatic prompt rewriting | $0.04/image |
| Qwen Image 3.0 Pro Edit | Image editing | 1440×1440 | 3 | Automatic prompt rewriting | $0.04/image |
| Seedream v5.0 Pro Text-to-Image | Text to image | Up to 4.19 MP | - | Thinking and prompt optimization | $0.045/image |
| Seedream v5.0 Pro Edit | Image editing | Up to 4.19 MP | 10 | Thinking and prompt optimization | $0.045/image |
| Nano Banana 2 Text-to-Image | Text to image | 4K | - | Thinking and search grounding | $0.08/image |
| Nano Banana 2 Edit | Image editing | 4K | 14 | Thinking and search grounding | $0.08/image |
How to Use Qwen Image 3.0 Pro on Atlas Cloud
Get started in minutes — follow these simple steps to integrate and deploy models through Atlas Cloud's platform.
Create an Atlas Cloud Account
Sign up at atlascloud.ai and complete verification. New users receive free credits to explore the platform and test models.
Why Use Qwen Image 3.0 Pro on Atlas Cloud
Combining the advanced Qwen Image 3.0 Pro models with Atlas Cloud's GPU-accelerated platform provides unmatched performance, scalability, and developer experience.
Performance & flexibility
Low Latency:
GPU-optimized inference for real-time reasoning.
Unified API:
Run Qwen Image 3.0 Pro, GPT, Gemini, and DeepSeek with one integration.
Transparent Pricing:
Predictable per-token billing with serverless options.
Enterprise & Scale
Developer Experience:
SDKs, analytics, fine-tuning tools, and templates.
Reliability:
99.99% uptime, RBAC, and compliance-ready logging.
Security & Compliance:
SOC 2 Type II, HIPAA alignment, data sovereignty in US.
Qwen Image 3.0 Pro API Questions, Answered
Qwen Image 3.0 Pro is Alibaba's image generation and editing model for producing images from text or modifying existing visuals with natural language instructions. On Atlas Cloud, it supports outputs up to 2048×2048 and editing with one to three reference images.
Use it to generate images that require detailed prompt adherence, complex text rendering, or high resolution output. For editing workflows, natural language instructions can change an image while preserving important details such as facial features and identity.
Choose the text-to-image or edit route, then call it through Atlas Cloud's OpenAI-compatible API with the matching model ID. Treat the linked Playground parameter schema as the source of truth when constructing and validating your request.
Select qwen-image-3.0-pro/text-to-image when generating an image from a prompt, or qwen-image-3.0-pro/edit when modifying reference images. Both routes have separate Playground schemas, so use the schema associated with your chosen workflow.
Text-to-image generation supports resolutions up to 2048×2048. When resolution is not selected manually, the model can use the prompt to guide its resolution choice.
Provide between one and three reference images together with a natural language editing instruction. The edit model uses those inputs to apply the requested changes while retaining key visual details, including facial features and identity.
Yes. The text-to-image model includes automatic prompt rewriting alongside prompt-guided resolution selection. Review outputs against your original instructions when precise wording, layout, or embedded text is important.
Atlas Cloud lists a standard base price of $0.04 per image for both the text-to-image and edit models. Billing follows a pay-as-you-go model, allowing developers to use either workflow without a subscription commitment.
Both versions support text-to-image generation and image editing. Alibaba's official overview describes the standard model as balancing quality and speed, but the verified sources reviewed here do not provide a quantitative comparison with Pro. Run representative prompts through both versions before selecting a production default.
Start with a clear reference image and explicitly state which facial or identity details must remain unchanged. The edit endpoint accepts up to three references and is designed to preserve those details. If drift persists, simplify the requested transformation and evaluate another generation.
Explore More Families
Seedance 2.5
Seedance 2.5 API is now available on Atlas Cloud! It gives developers ByteDance's newest video model. It generates up to 30 seconds of native video in a single pass from text, a single image, or as many as 50 multimodal references, with synchronized audio and in-frame multilingual text. On Atlas Cloud you reach it through one key, with subject consistency and improved physics keeping long shots coherent. (Update: Seedance 2.5 1080P API Is Available NOW!)

Wan 3.0
Wan 3.0 API is the next generation of Alibaba's Wan video family, built to push long-form generation, multi-reference control, and audiovisual quality to new heights. Atlas Cloud already hosts Wan 2.7, 2.6, and 2.5, and Wan 3.0 runs on the same unified key with no separate setup. Start building today. Scroll down to the showcase to see what Wan 3.0 can create.
MiniMax H3
MiniMax H3 is MiniMax's multimodal video family for text, image, and reference guided creation. Across supported routes, it preserves subjects from reference media, offers flexible aspect ratios, and pairs generated sound with visuals through H3 Developer, with output profiles selected by endpoint. Atlas Cloud unifies the family behind one OpenAI-compatible key with transparent pay-as-you-go pricing from the standard rate of $0.038 per second. Start building today.
Seedream 5.0 Pro
Seedream 5.0 Pro API gives developers ByteDance's controllable image editing model on Atlas Cloud. It places edits precisely with anchors and coordinates, separates images into editable layers, fuses multiple references, and matches exact colors and materials, with multilingual text at 2K and 3K. On Atlas Cloud you reach it through one key!
Seedance 2.0
Seedance 2.0 is ByteDance’s production video model for precise shot creation. Turn prompts into video, animate a first-frame image with optional last-frame guidance, or shape results with reference media and optional web search. Atlas Cloud brings these workflows into one unified API with transparent pay-as-you-go pricing and one OpenAI-compatible key. Start building today.
GPT Image 2.5
The gpt-image-2.5 family from OpenAI gives developers a choice of Flare and Sunburst for production image workflows. Render at arbitrary resolutions up to 3840x2160 and select from five quality tiers, including xhigh and max, to match specific output requirements. Atlas Cloud provides ready-to-use REST inference with no cold starts and standard pricing from $0.004 per generation. Start building today.
GPT Image 2
The GPT Image 2 API gives developers access to OpenAI's latest image model, the successor to GPT Image 1.5. It generates and edits images with accurate text rendering across Latin and CJK scripts, plus strong composition for posters, mockups, and infographics. On Atlas Cloud you reach it through one unified API alongside 300+ models, with free credits, 99.99% uptime, and no OpenAI organization verification required.
Gemini Omni Flash
The gemini omni API brings Google DeepMind's natively multimodal Gemini Omni Flash family, including Gemini Omni 1.1 Flash, to developers. Create cinematic video with synchronized native audio, animate still images with precise start and end frame control, or revise existing footage through text guided edits that preserve untouched content. Atlas Cloud provides one OpenAI-compatible key, unified access, and transparent pay-as-you-go pricing. Start building today.
Grok Imagine
Grok Imagine Image is xAI's family for generating polished visuals and revising one or more reference images through natural language instructions. Its standard and quality endpoints cover text to image creation, single image changes, and indexed multi-image composition. Atlas Cloud brings these workflows into one API, with standard generation and editing priced at $0.02 per image. Start building today.
Google's most powerful creative models are all available on Atlas Cloud. Veo 3.1 delivers cinematic video generation, Nano Banana 2 powers high-fidelity image creation, and Gemini brings multimodal intelligence to every workflow. Access the full Google model suite through one API key with Day-0 availability and pay-as-you-go pricing.
Seedance 2.0 Mini
The Seedance 2.0 Mini API is the lightest, lowest-cost tier of ByteDance's Seedance video line, built for teams where throughput and unit cost matter more than maximum polish. Use it for batch generation, rapid prototyping, and draft passes, all through one OpenAI-compatible key on Atlas Cloud.
ByteDance
From cinematic video generation to high-fidelity image creation, ByteDance's most powerful models are live on Atlas Cloud. Run Seedance and Seedream at scale with the lowest inference pricing and zero infrastructure overhead.
Recommended Articles
Guides, tutorials, and product updates to help you get the most out of Atlas Cloud.





